Nano Banana 2.1 for Fashion, Ecommerce, and Marketing: Comparison

Nano Banana 2.1 is a strong candidate for commercial reference-based image work: it ranks third in Arena's multi-image-edit Product, Branding & Commercial Design category as checked on October 7, 2026. In our 31 reference-led samples, it preserves the jacket's main features and produces convincing on-model portraits, but does not win every identity, label, or campaign constraint. It belongs on a production shortlist alongside Sunburst and Flare, with product-specific approval before use.
For a fashion brand, a prettier picture with the wrong embroidery is a failed asset. For an ecommerce team, readable copy cannot compensate for a changed product shape. For a marketing team, composition, product fidelity, and copy accuracy need separate approvals.
Tested October 7, 2026. Five original briefs across five models, plus a clean-packshot-to-real-scene brief across six models, one output per cell. We show reviewed selections and report the rejected cells in text; there are no replacement runs in the comparison.
What Nano Banana 2.1 changes
Google's released model ID is gemini-nano-banana-2.1. Its predecessor, called Nano Banana 2 or 2.0 in this comparison, is gemini-3.1-flash-image. Nano Banana Pro is a separate model.
Google describes improvements to realism, instruction following, text rendering, and character consistency through successive edits. Outputs support 1K, 2K, and 4K; wide-image tiling fixes target panoramic ratios at higher resolutions. It supports up to 14 reference images, with documented consistency roles for up to four characters and ten objects. These are provider capabilities to qualify on a real brief, rather than proof of exact garment reconstruction. See Google's model documentation.
Google Cloud dates the generally available release to October 6, 2026. Its technical specifications also rule out provider-level seed and sampling controls. An identical seed is therefore not a fair-control promise for this comparison.
Arena's current commercial multi-image-edit ranking
Checked October 7, 2026; leaderboard displayed October 6, 2026 as its update date. The table below transcribes the relevant rows from Arena's multi-image-edit commercial-design leaderboard, with the Multi Image Edit category selected and license filter set to All.
| Displayed rank | Model in Arena | Score and displayed uncertainty | Rank spread | Votes | Status |
|---|---|---|---|---|---|
| 1 | GPT Image 2.5 Sunburst | 1557 ±10 | 1–1 | 6,958 | Preliminary |
| 2 | GPT Image 2.5 Flare | 1503 ±10 | 2–3 | 6,998 | Preliminary |
| 3 | Gemini Nano Banana 2.1 | 1490 ±13 | 2–4 | 2,389 | Preliminary |
| 4 | GPT Image 2 (medium) | 1484 ±7 | 3–4 | 25,342 | — |
| 5 | Seedream 5.0 Pro | 1431 ±8 | 5–6 | 14,067 | — |
| 6 | Muse Image | 1422 ±7 | 5–6 | 20,732 | — |
| 7 | Gemini 3.1 Flash Image / Nano Banana 2 [web-search] | 1403 ±7 | 7–9 | 16,876 | — |
| 8 | Ideogram 4.5 | 1391 ±16 | 7–11 | 1,327 | Preliminary |
| 9 | Gemini 3 Pro Image 2K / Nano Banana Pro | 1384 ±6 | 8–11 | 24,605 | — |
| 10 | Reve 2.0 | 1383 ±14 | 7–11 | 1,795 | — |
Nano Banana 2.1 sits behind Sunburst and Flare by displayed score and ahead of GPT Image 2 (medium). Its displayed score intervals overlap those of Flare and GPT Image 2, and Arena gives it a rank spread of 2–4. A rigid claim that it is conclusively the third-best commercial model would overstate this snapshot.
These scores concern human preference in commercial multi-image editing. They are not overall image-generation ranks, overall editing ranks, garment-accuracy percentages, or our test scores. The predecessor's entry explicitly includes web search; our Astria briefs do not request search grounding. We do not treat those configurations as identical.
Our comparison design
We selected Sunburst and Flare because they lead this specific Arena category, and Seedream 5 Pro because it ranks fifth and offers a relevant material-and-fashion alternative. The direct predecessor is required to isolate the practical upgrade question. Muse remains a useful multi-reference challenger; Ideogram 4.5 and Reve 2.0 are not interchangeable with the different versions currently exposed in Astria's catalog.
The five original cases use the same supplied images, exact semantic prompt, 4:3 requested aspect ratio, 2K requested resolution, and one requested output per model in Astria workspace 896, Articles. Face inpainting and film grain are disabled. The only returned image is the predetermined comparison candidate; there are no selective reruns.
We use 2K as the common resolution supported by Seedream Pro and the other selected endpoints. Actual dimensions differ between providers. The cover is a separate native 4K render with the supplied portrait and jacket. No source or output was enlarged to meet the resolution gate.
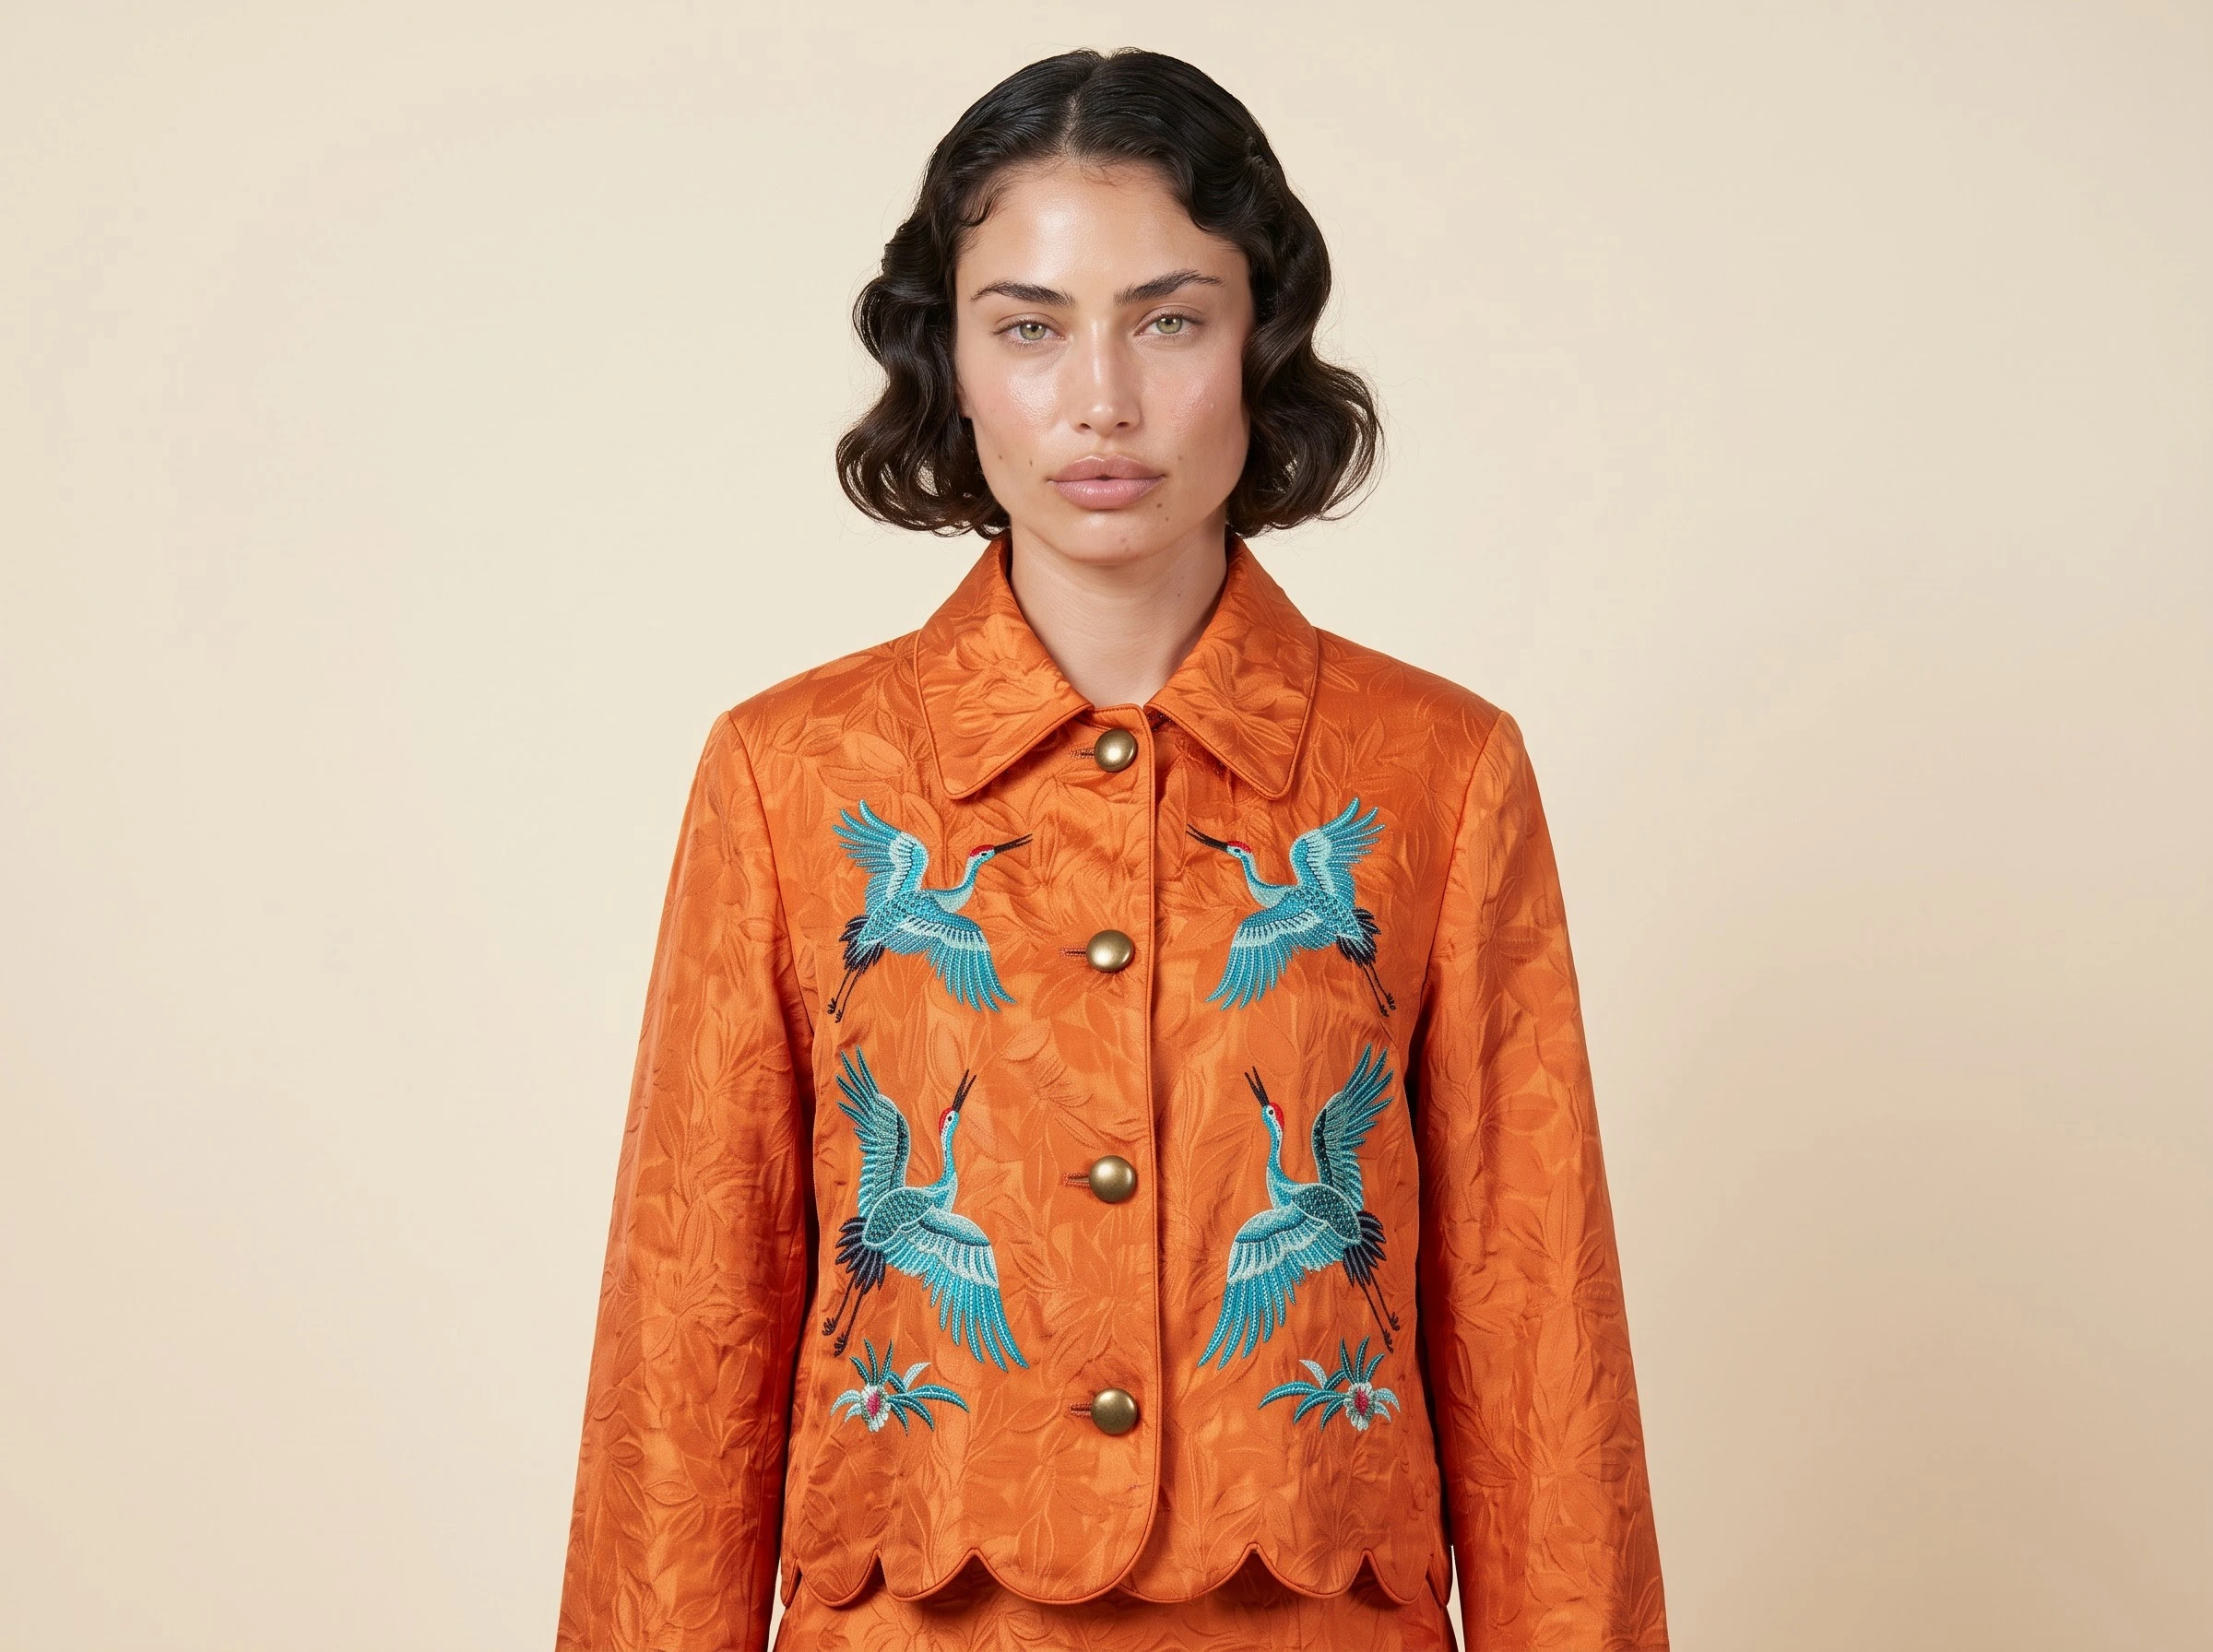
The synthetic jacket and serum references come from our earlier benchmark assets. The jacket source has four teal cranes, four brass buttons, two lower floral motifs, orange leaf-pattern jacquard, a pointed collar, and a scalloped hem. The serum source supplies the bottle, pump, carton, palette, and label design. These are fictional products made for testing, not customer SKUs.
We checked the deployed integration before submitting 2.1: production release v4821 contains the routing update. Tune 4180298 now targets gemini-nano-banana-2.1; separate tune 5850983 targets gemini-3.1-flash-image. The two product-only 2.0 baselines were generated before the upgrade, with the verified former mapping; all later 2.0 cases use the separate legacy tune. Spicy Mayo is deprecated and excluded. The curated MCP catalog still carries an older display label, which is why we verified release history and committed provider mappings instead of relying on names. Attempt-level transport telemetry is not exposed by the tool.
Garment detail: strong main features, imperfect labels
The brief asks for a complete front view on an invisible mannequin, with the referenced jacket's construction, motif counts, color, and weave preserved. This tests a catalog transformation before adding the complexity of a person or location.
The exact brief supplied to all five models was:
Create a product-only ecommerce photograph of <faceid:5851059:1> jacket on an invisible mannequin, front view with sleeves hanging naturally, against a warm ivory seamless studio background. Preserve the exact burnt-orange silk jacquard leaf weave, all four teal crane motifs and lower floral details, four brass dome buttons, pointed collar, cropped length and scalloped hem. Show the complete garment without clipping. Soft even catalog lighting, realistic material detail. No person, no accessories, no added text, no new logos.
Jacket — four reviewed comparison selections
The same supplied jacket and brief. The 2.1 output is withheld because it changes the collar label; its result is reported below.
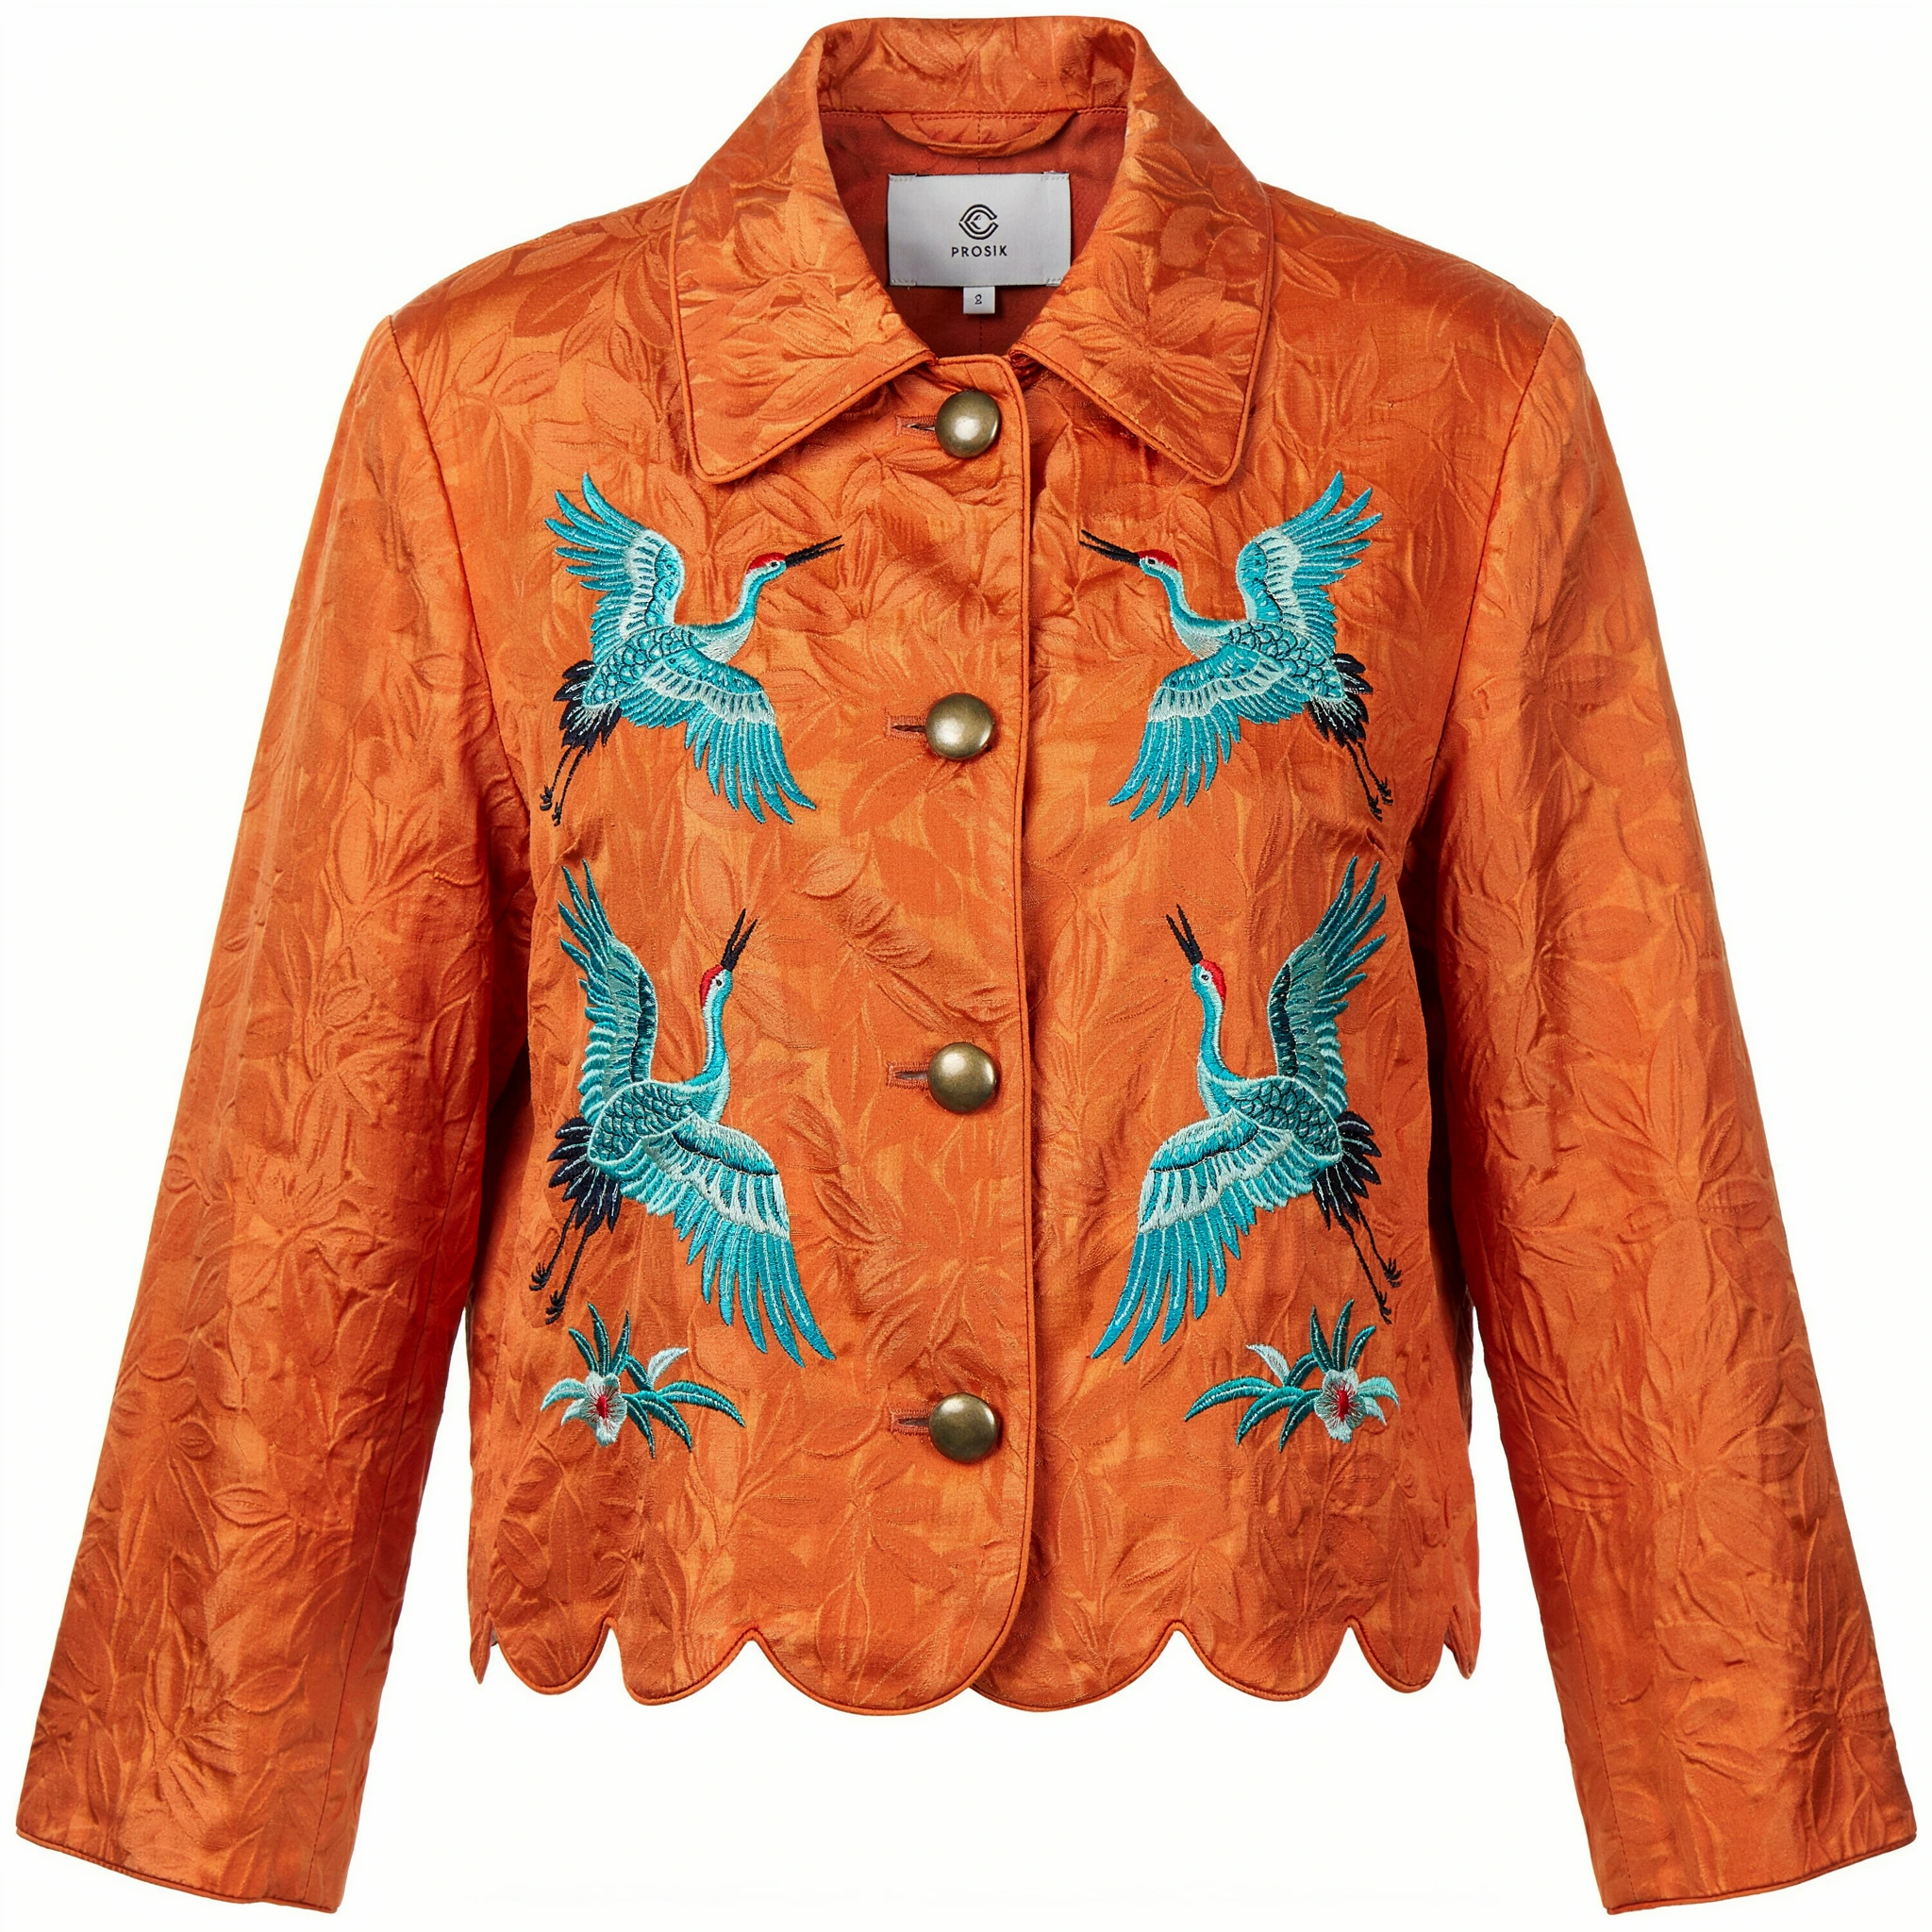
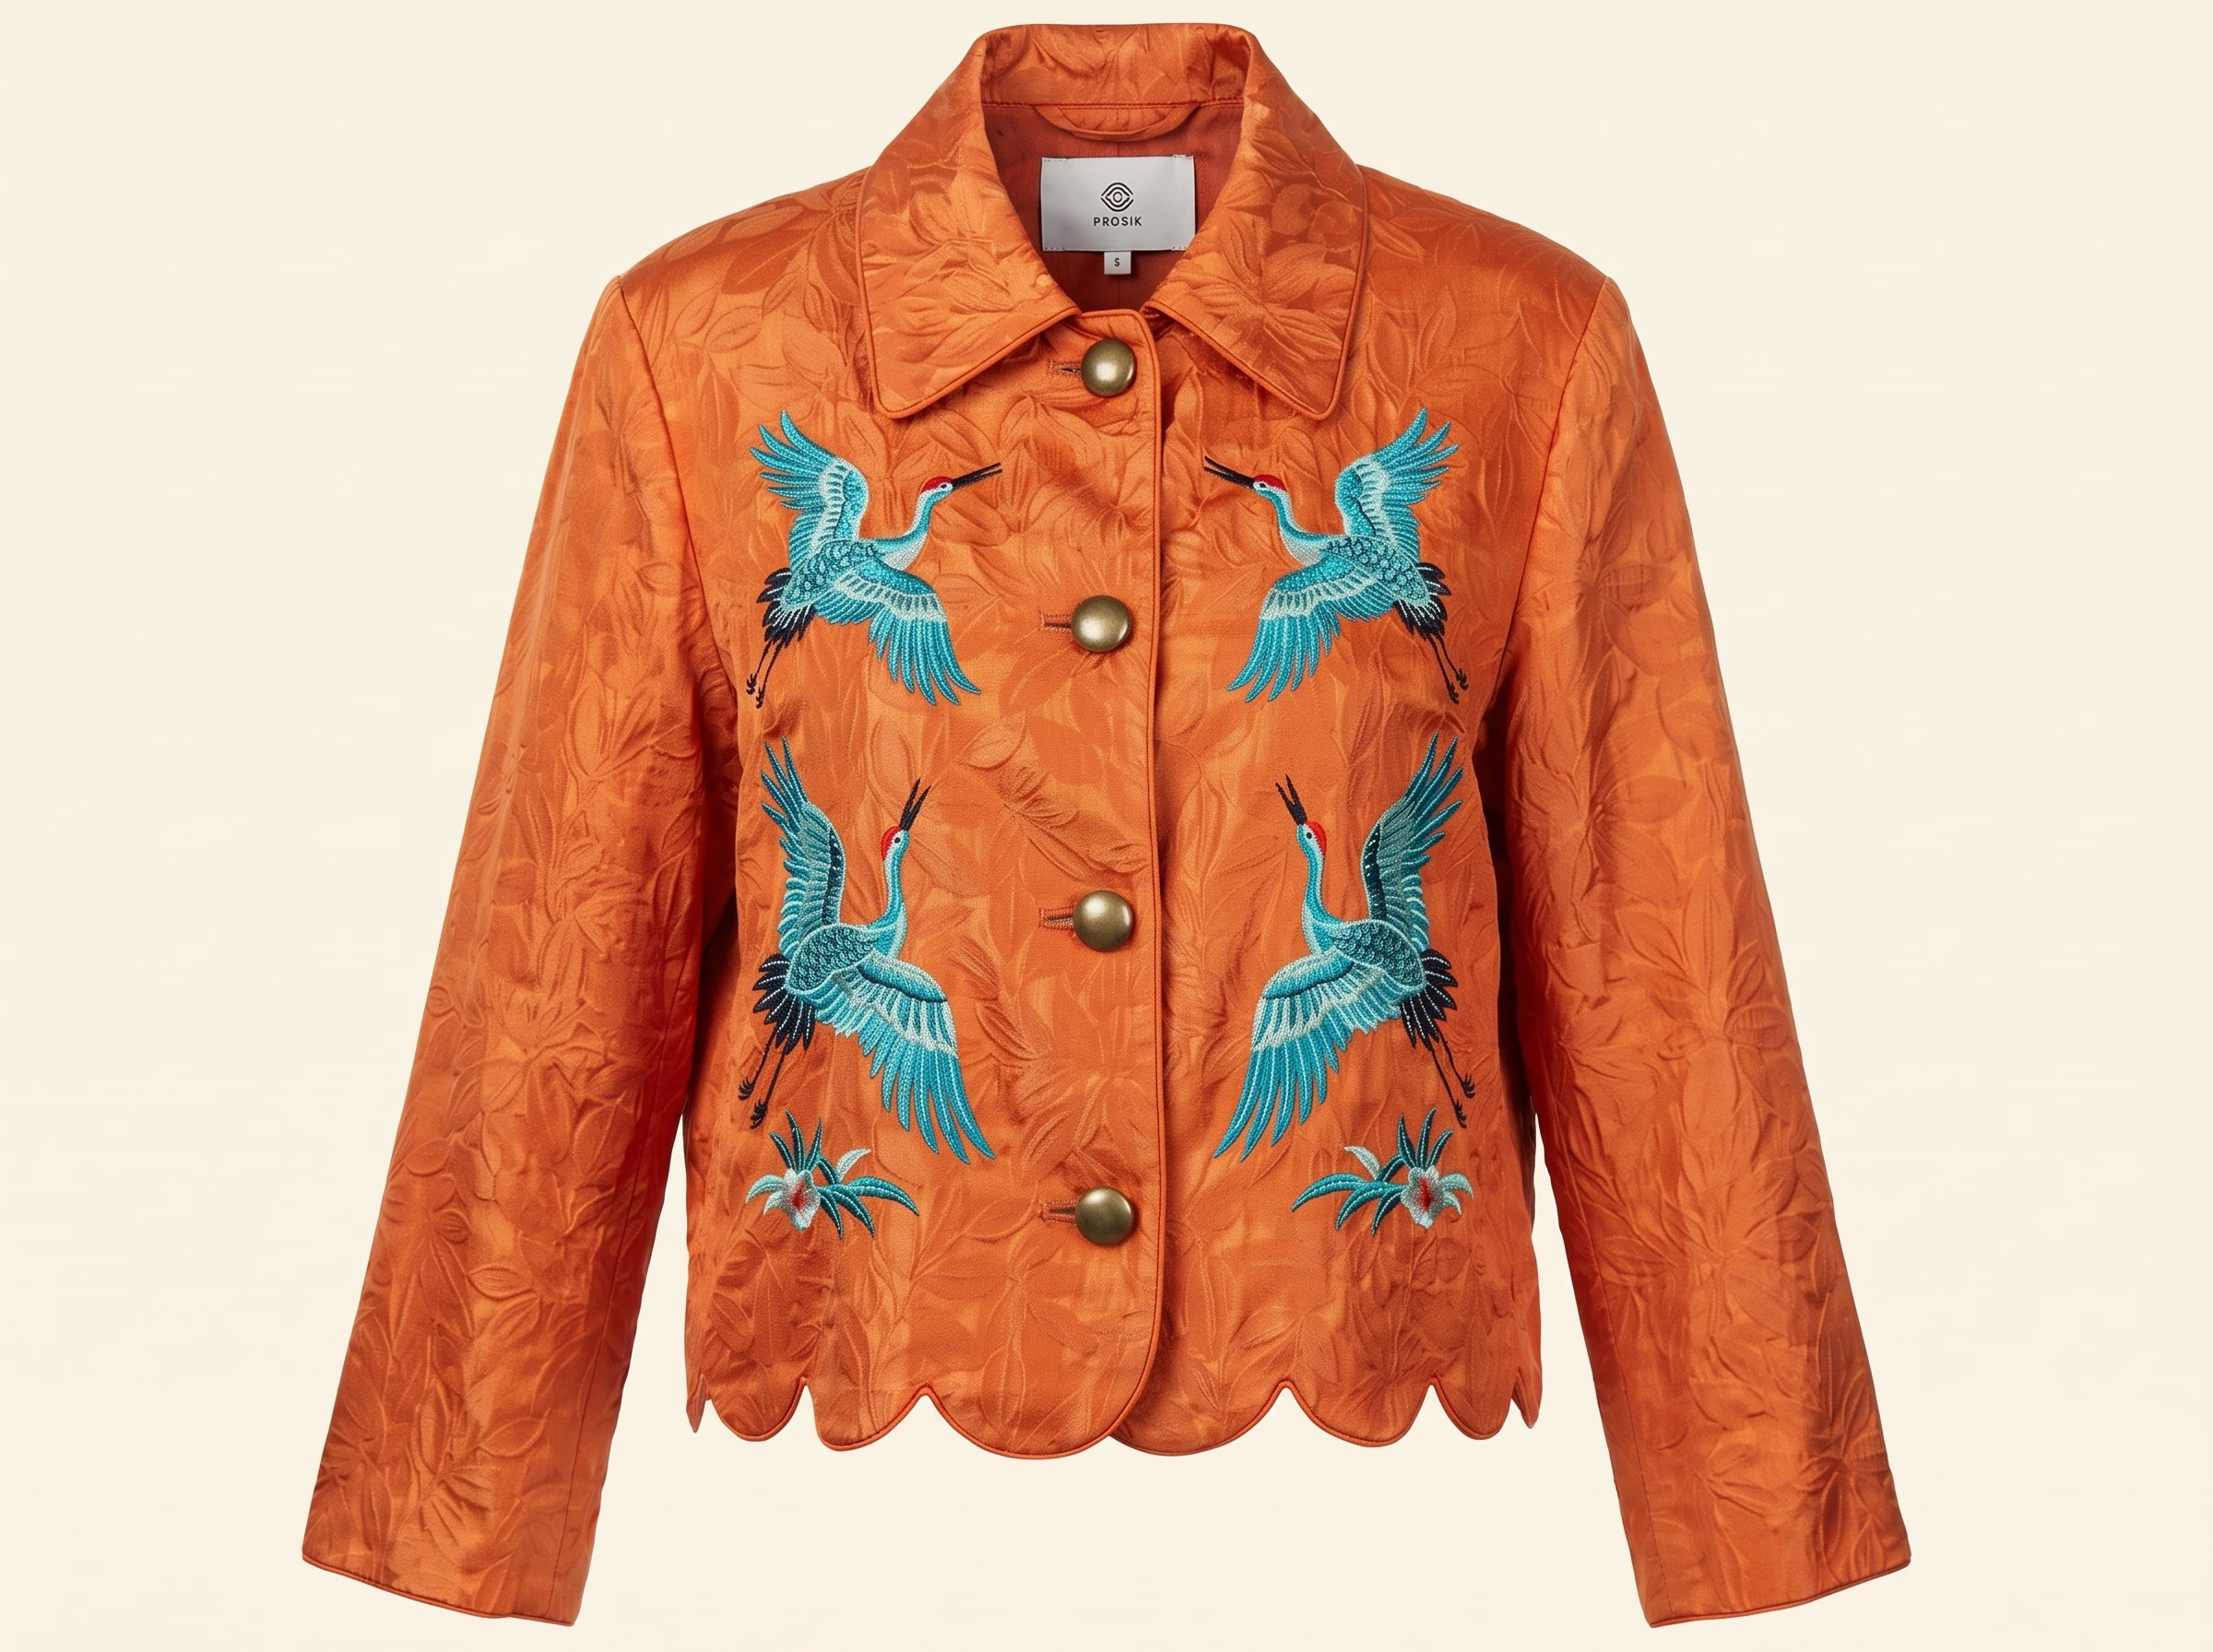
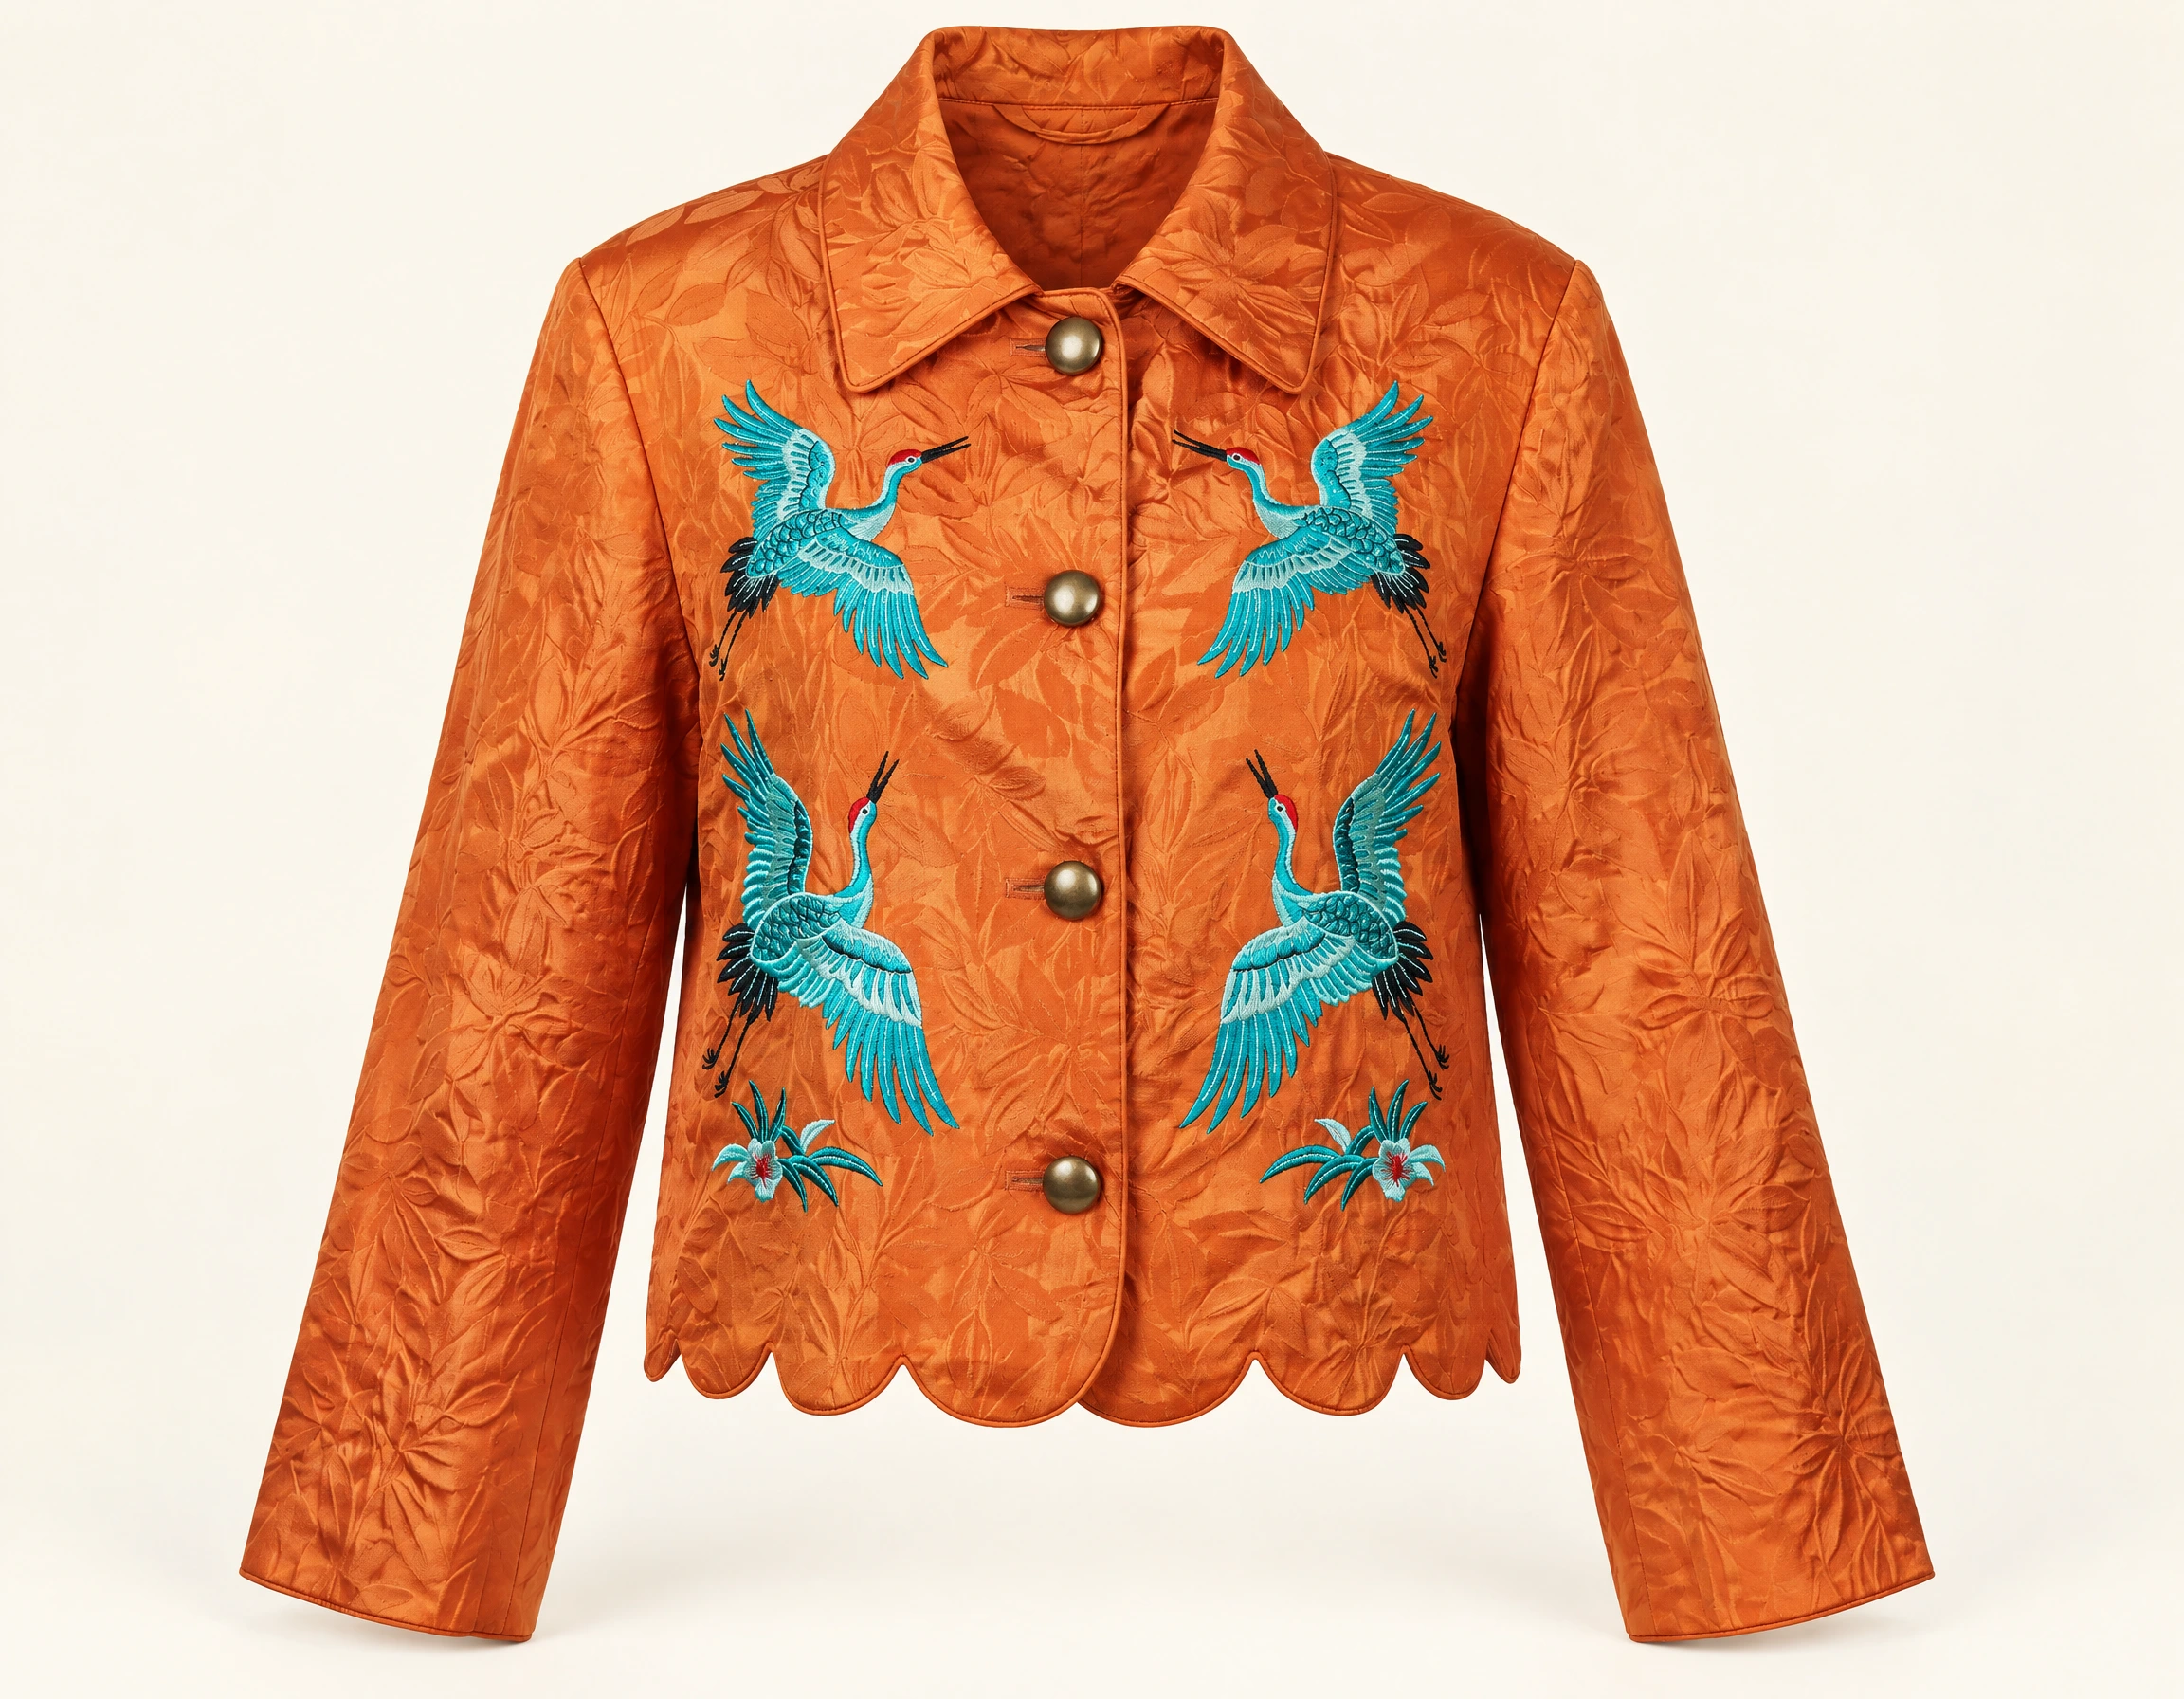
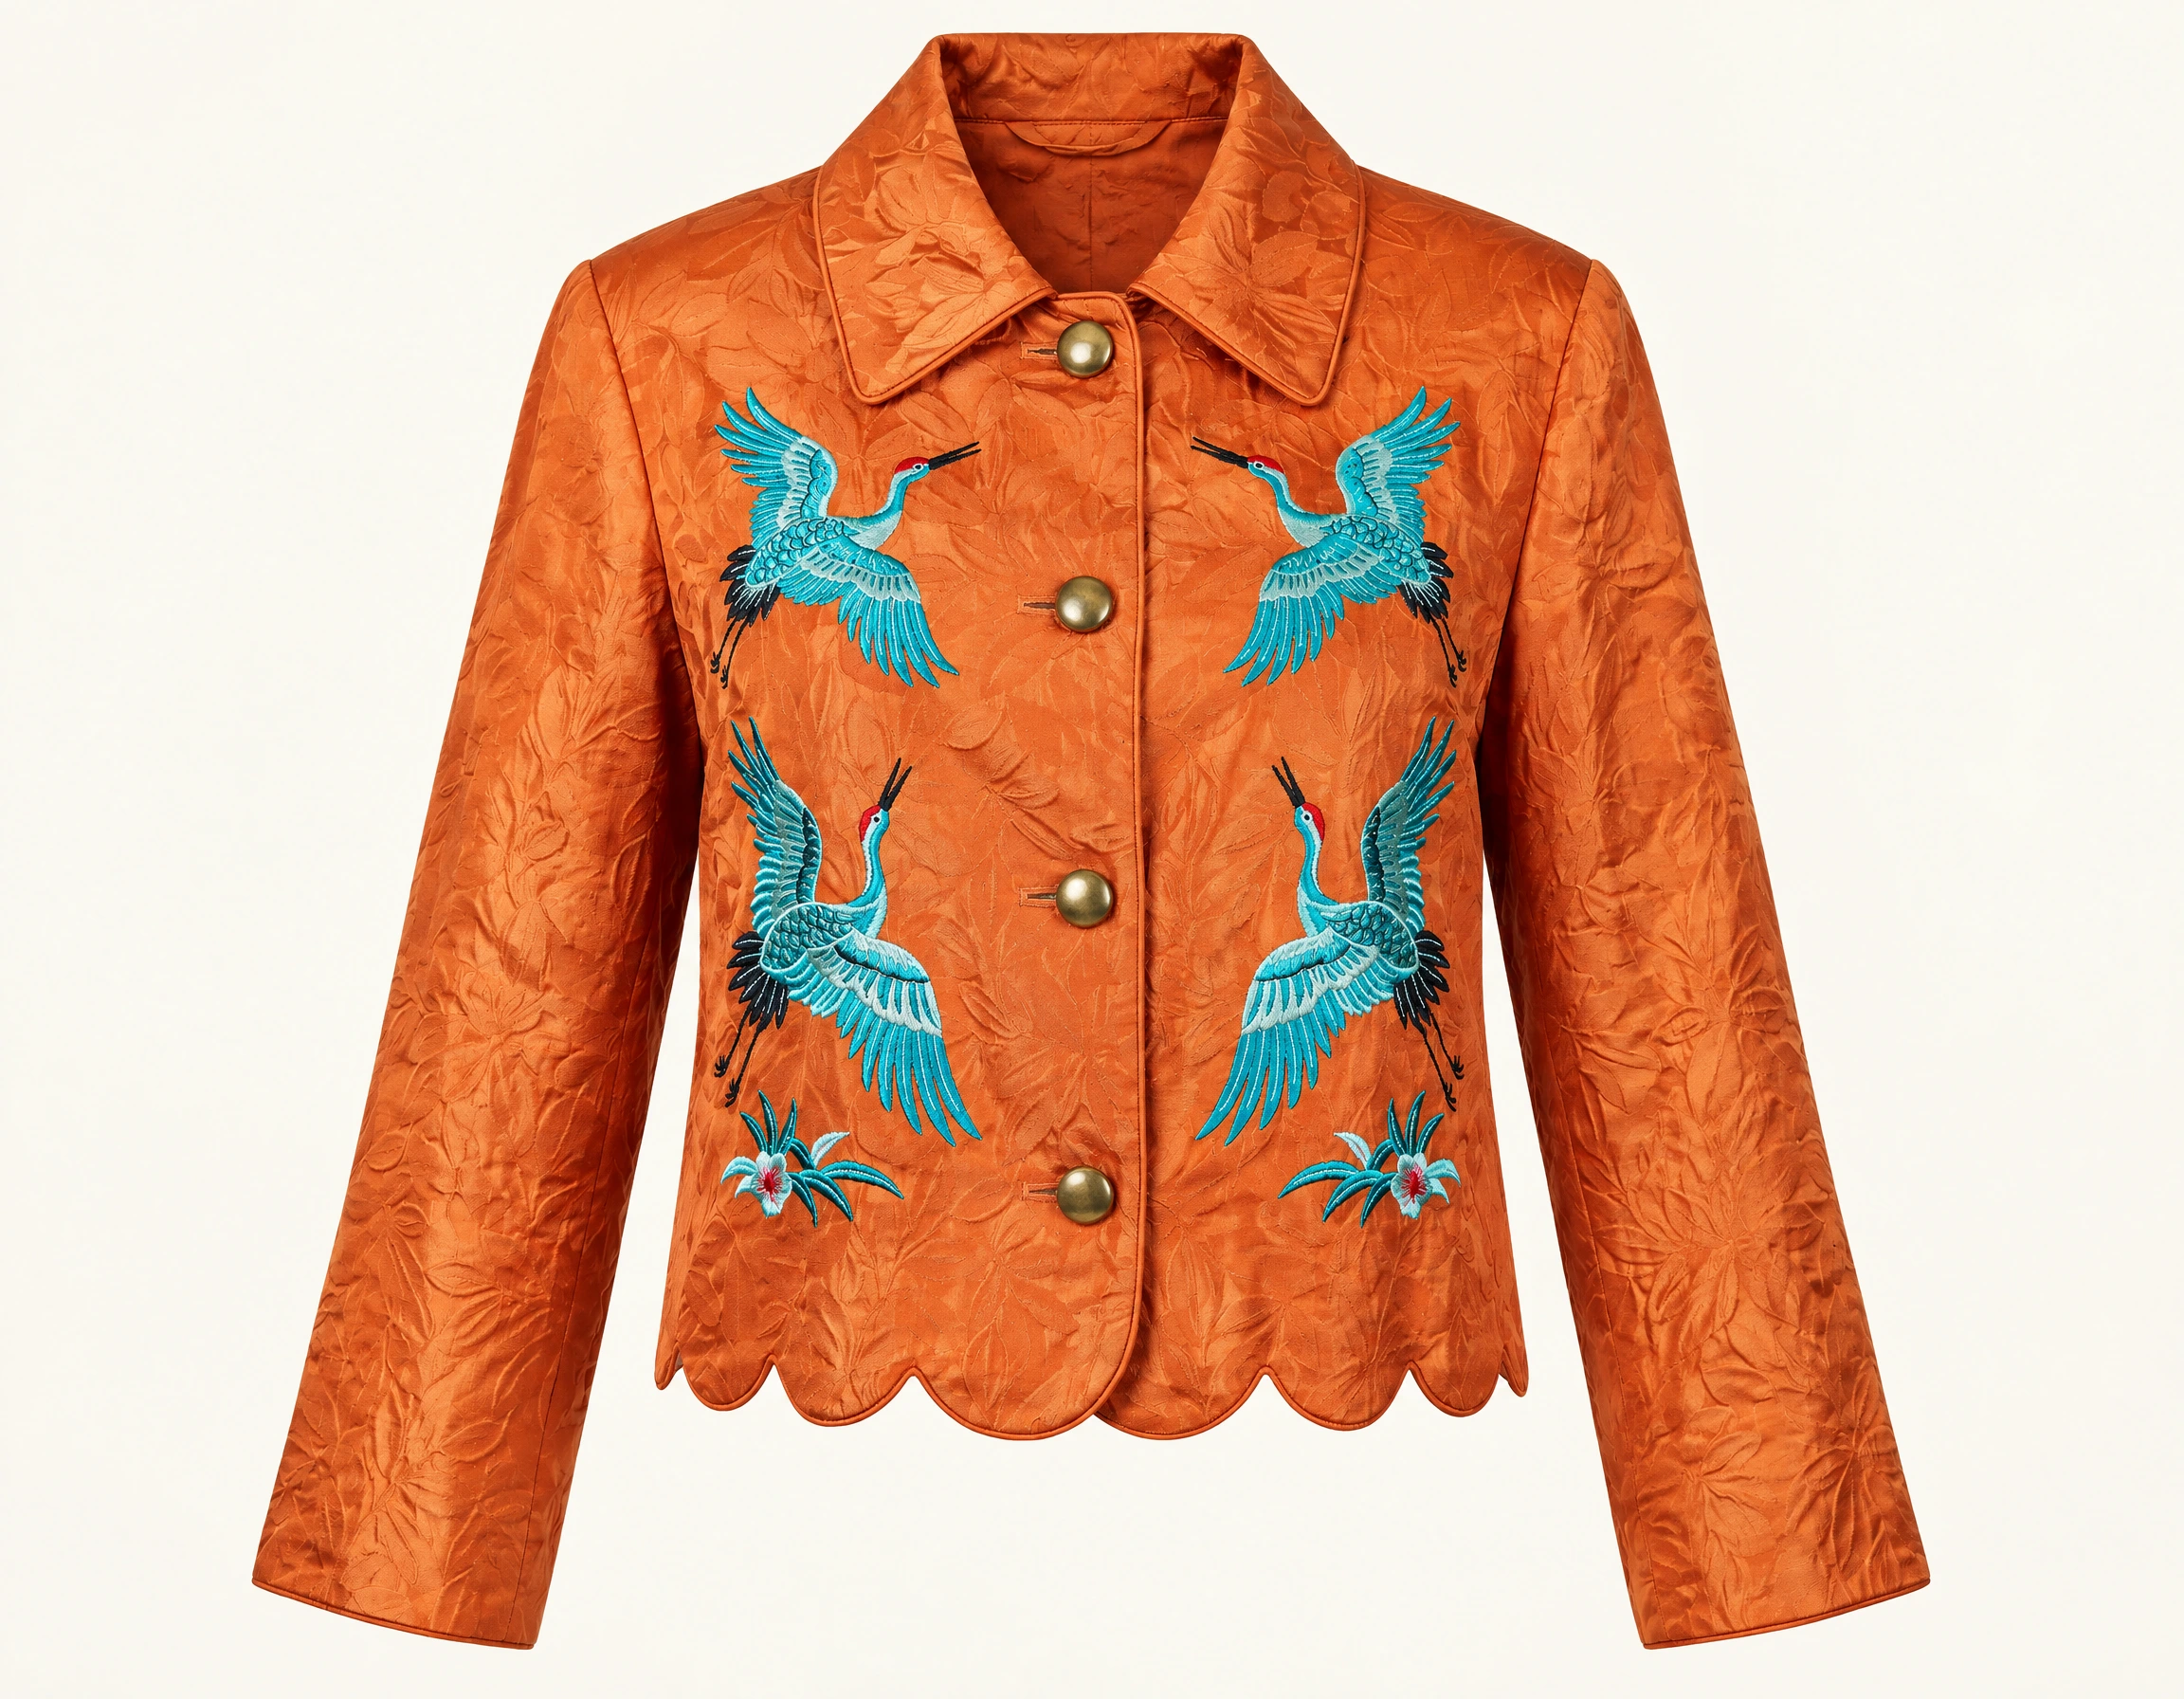
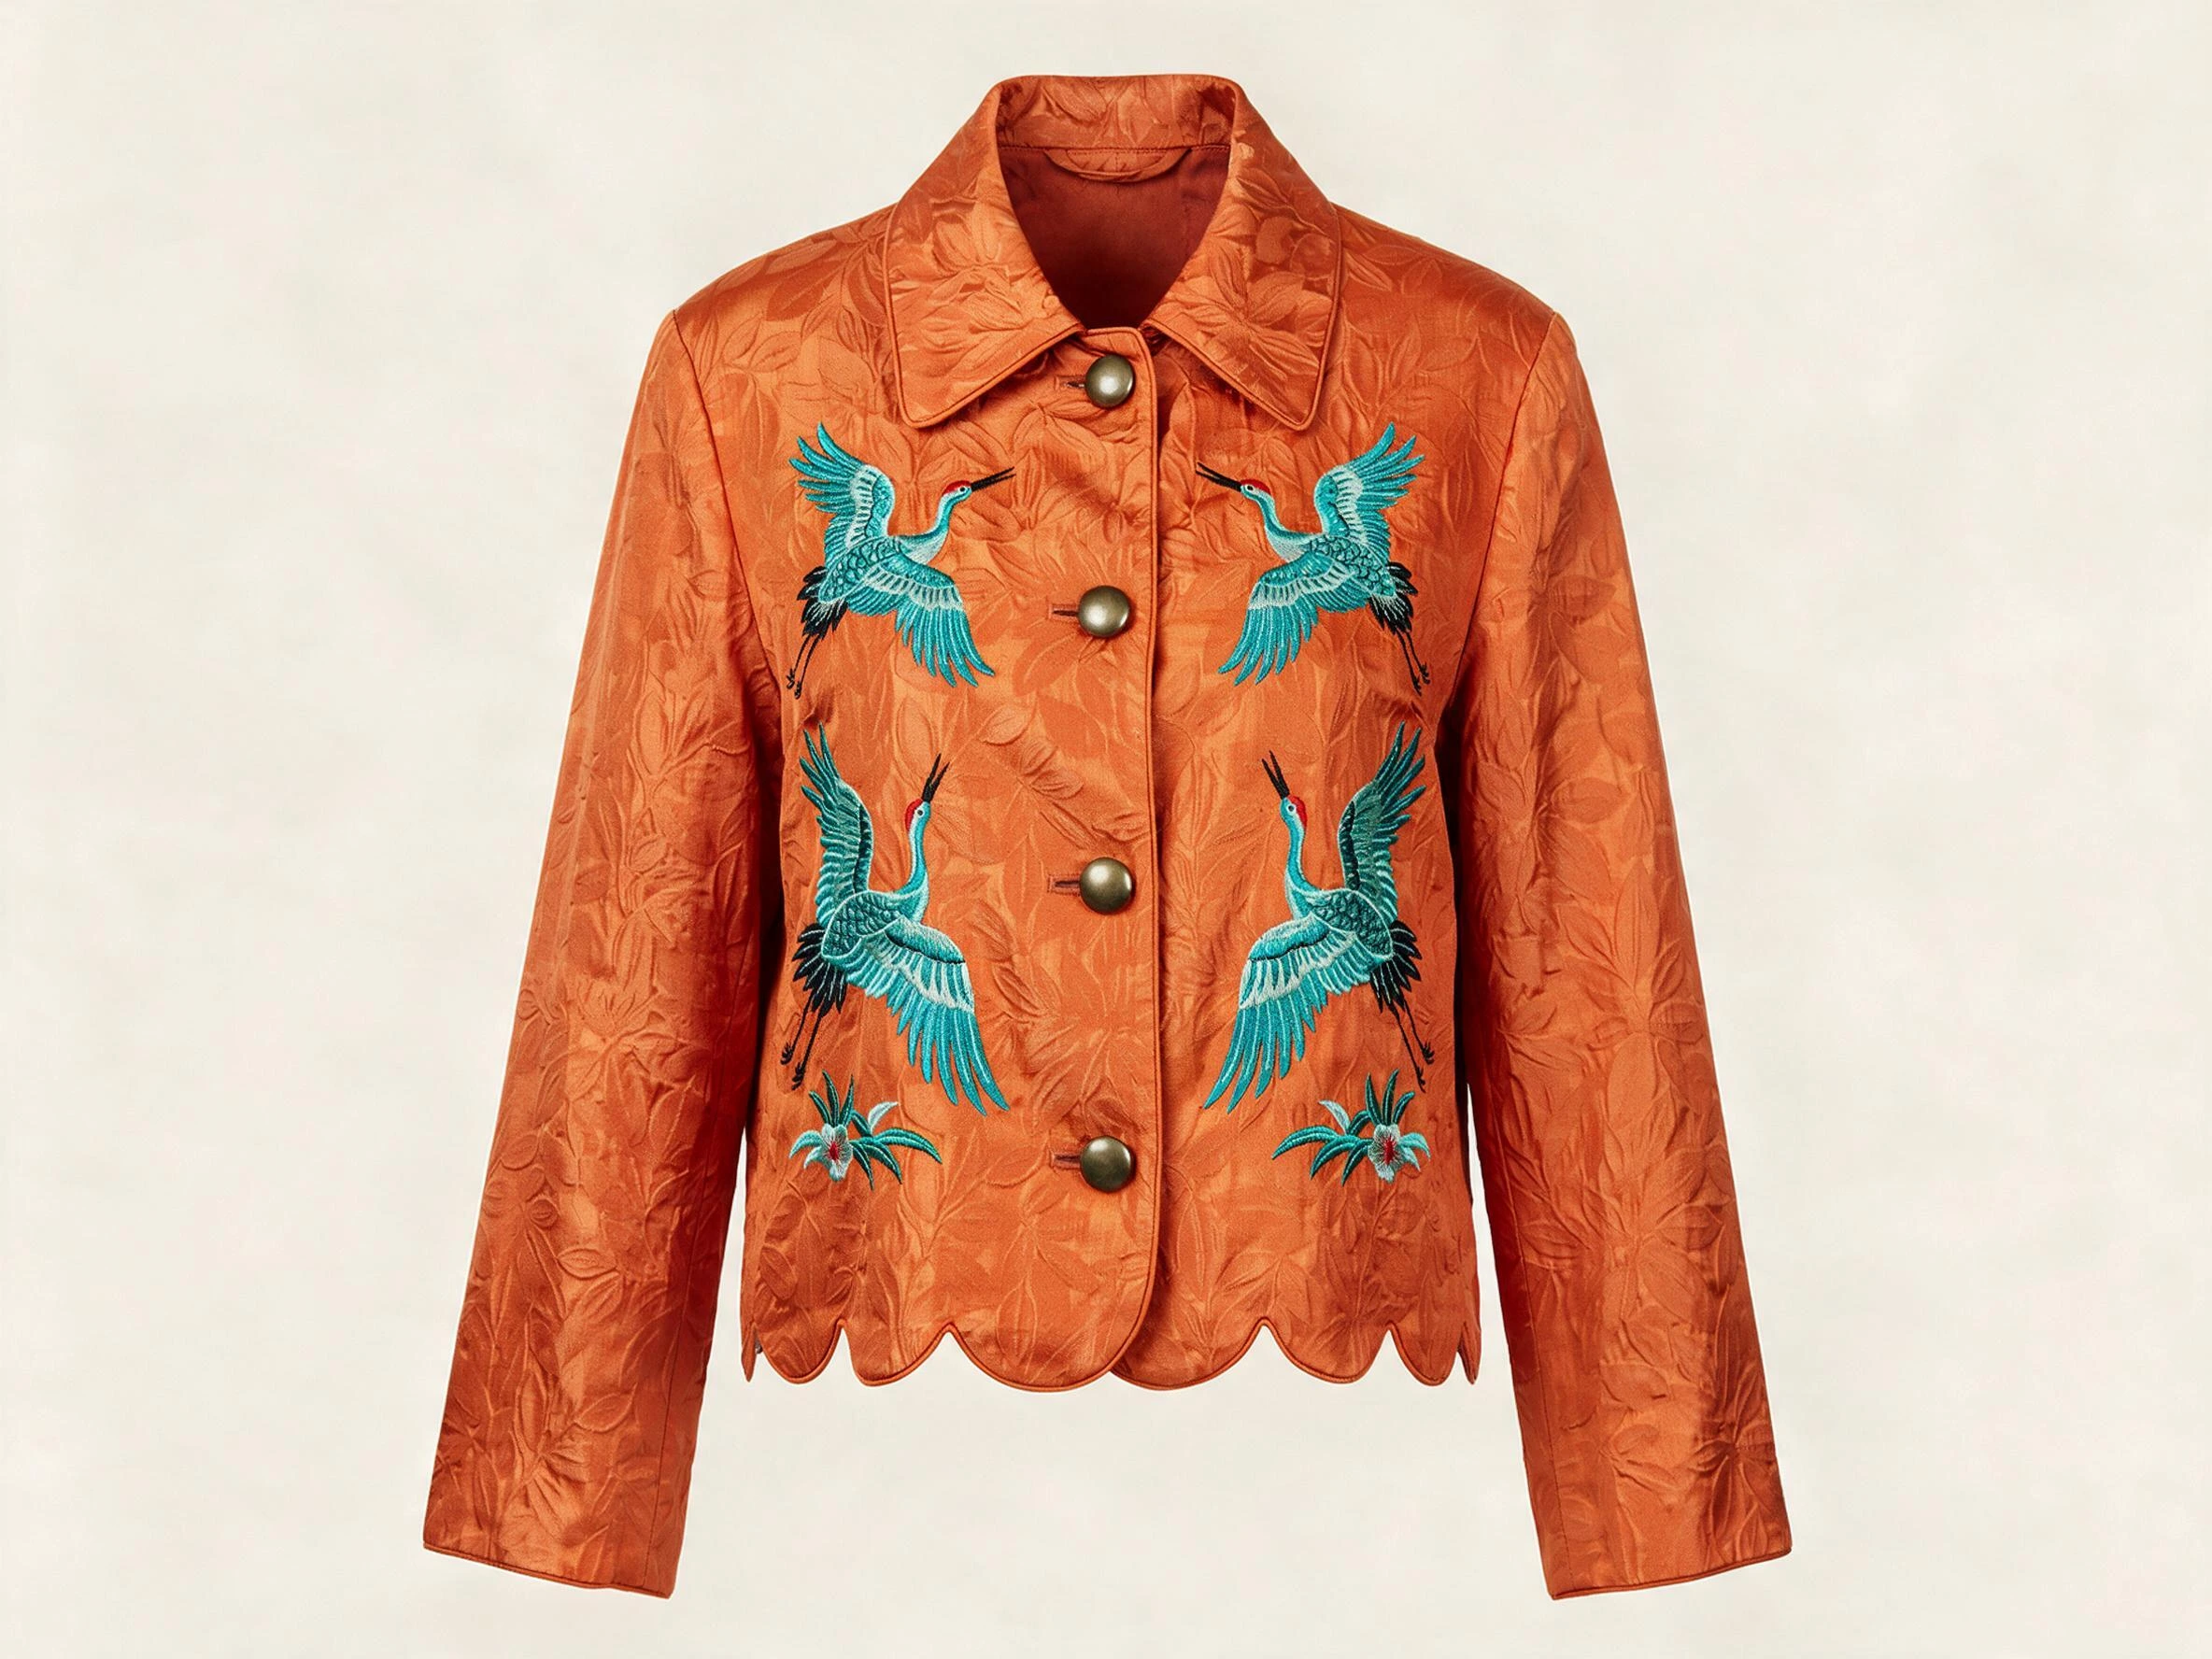
These images preserve the main garment features well enough for this editorial comparison. They are not pixel-identical product reproductions. We would check embroidery close-ups and trim placement against an actual SKU before approving ecommerce use. The source includes an invented collar label; its removal by Sunburst and Flare is another reason to keep packaging or brand-label fidelity separate from general visual quality.
Seedream also completed and retained the main garment structure, with simplified floral details and no collar label. The 2.1 sample also retains four cranes, four brass buttons, lower flowers, leaf-pattern cloth and a scalloped hem. However, it replaces the invented source collar label with different lettering. We keep that image internal rather than presenting it as an approved branded product asset. This is a specific miss on this run, not evidence that every 2.1 product edit fails. The five single-output cells do not establish a general winner for fabric fidelity. No missing or incompatible output is replaced with a text-only example.
| Tested endpoint | Prompt ID | Actual pixels |
|---|---|---|
| Nano Banana 2.1, label change; image withheld | 47133603 | 2400 × 1792 |
| Nano Banana 2.0, before routing upgrade | 47132456 | 2400 × 1792 |
| Sunburst | 47132457 | 2304 × 1792 |
| Flare | 47132458 | 2304 × 1792 |
| Seedream 5 Pro | 47132459 | 2368 × 1776 |
These are Astria endpoint tests, not reproductions of Arena's evaluation prompts or serving configuration. The successful transport provider of each attempt is not exposed by the generation tool.
Marketing copy: readable headlines are only half the job
The second brief turns a supplied serum bottle and carton into a rose-and-ivory campaign layout. It requests three exact copy lines: “LUMEN SERUM”, “A daily ritual.”, and “DISCOVER THE COLLECTION”, with the product on the right and copy on the left.
All five models render those three lines legibly in the completed baseline outputs. Sunburst adds an outlined call-to-action treatment; Flare uses an italic middle line; 2.0 uses a simpler sans-serif layout. Nano Banana 2.1 uses a restrained sans-serif headline and serif middle line. The copy pass therefore does not isolate an upgrade advantage on this brief.
Seedream renders the three marketing lines too, but duplicates “30 mL” near the bottom of the carton. That is an unrequested packaging change, even though the large ad copy reads correctly.
Product fidelity still needs a stricter judgment. Bottle and pump proportions differ, and the upright carton creates a new label presentation. The source bottle omits the “04” printed on the carton, while our prompt explicitly requests “No. 04 ROSE” on both. This tests controlled text normalization as well as preservation. Nano Banana 2.1 retains the source bottle's “No. ROSE” instead of applying the requested “No. 04 ROSE” normalization. We keep all five images internal because exact packaging and geometry did not pass. The typography findings remain useful, but none is an approved SKU advertisement.
| Model | Three requested ad lines | Specific packaging or layout observation |
|---|---|---|
| Nano Banana 2.1 | Correct and legible | Bottle omits requested “04”; carton includes it |
| Nano Banana 2.0 | Correct and legible | Carton text remains sideways despite upright presentation |
| Sunburst | Correct and legible | Adds an outlined CTA treatment; product proportions differ |
| Flare | Correct and legible | Italic middle line; pump and bottle proportions differ |
| Seedream 5 Pro | Correct and legible | Adds an extra “30 mL” near the carton bottom |
For marketers, approve the product first, then check spelling, hierarchy, contrast, and room for channel-specific crops. For ecommerce teams, retain approved product photography when an AI transformation changes the SKU's defining shape or hardware.
Clean packshot to real scene: five models preserve every text line
Nano Banana 2.1, Pro, Sunburst, Flare and Seedream tie at 11 / 11 preserved text lines. Nano Banana 2.0 scores 10 / 11. With a clearly readable source, the leading group reproduces even the small blue French copy. There is no single text-fidelity winner in this round.
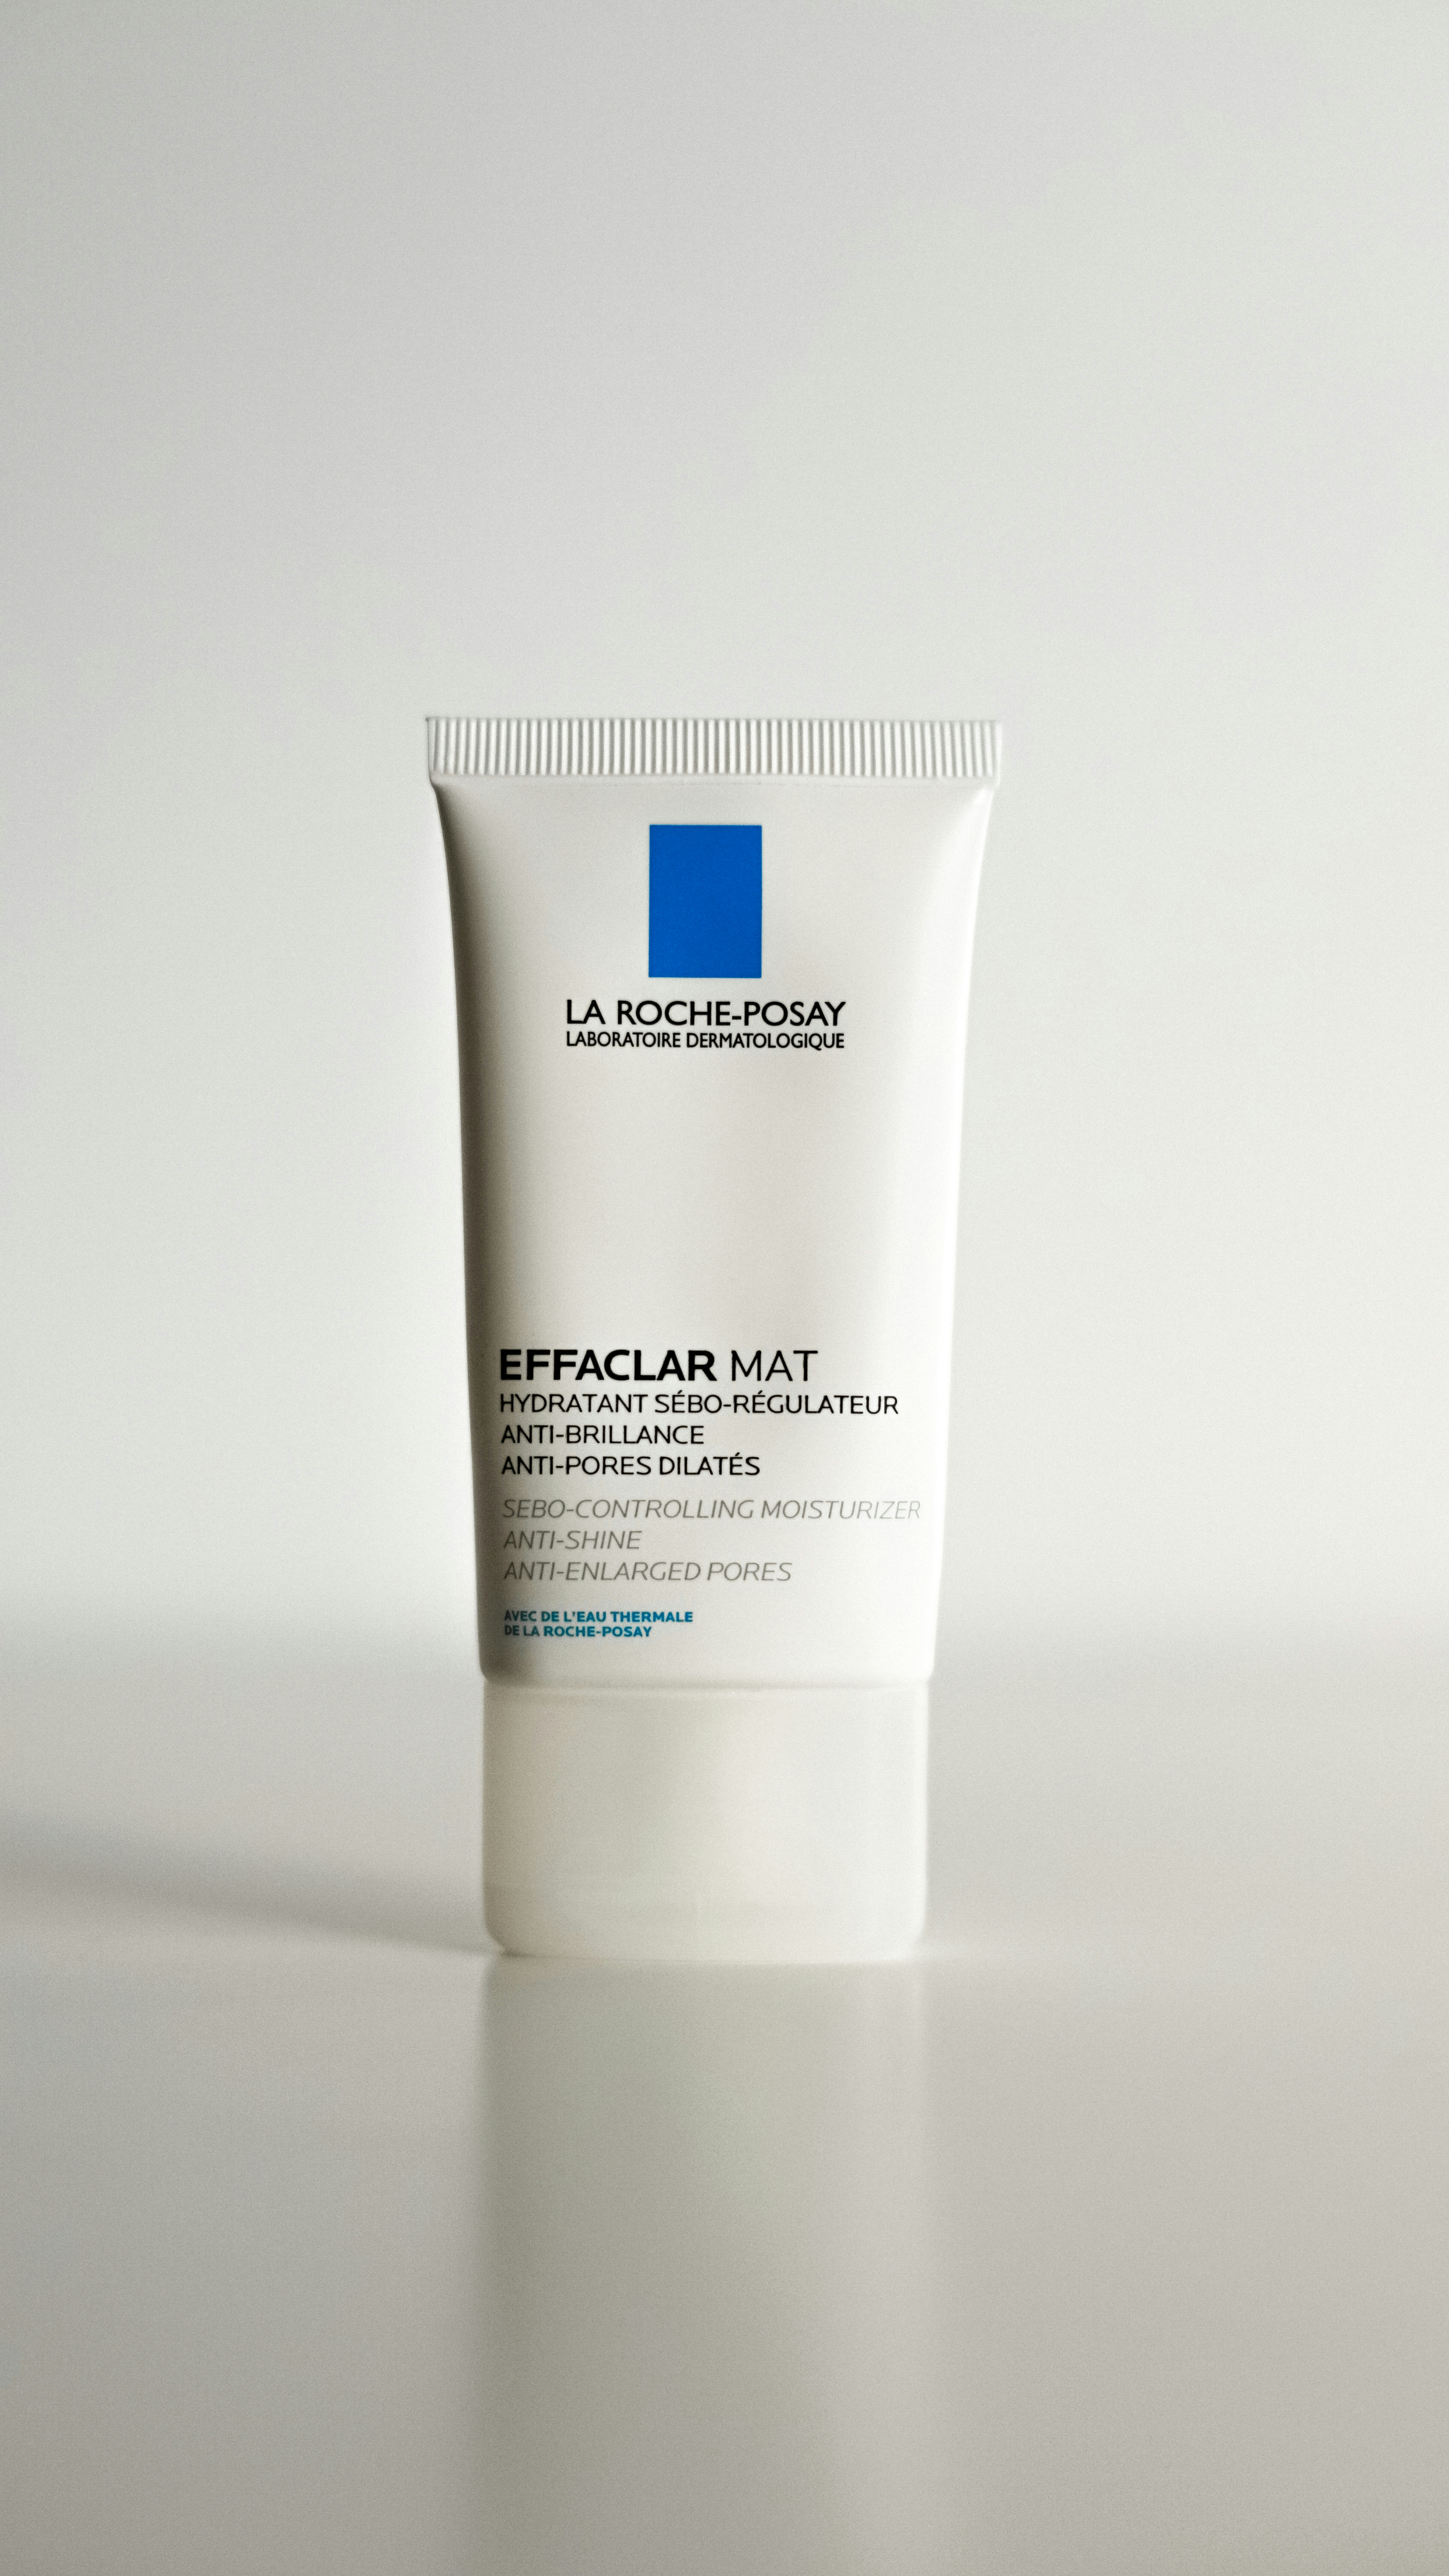
We start with one real product in a clean studio packshot: a white La Roche-Posay Effaclar Mat tube on a plain background, photographed by Cosmin Ursea on Unsplash, used under the Unsplash License. Every front-label line is readable in the original, including the small blue wording above the cap.
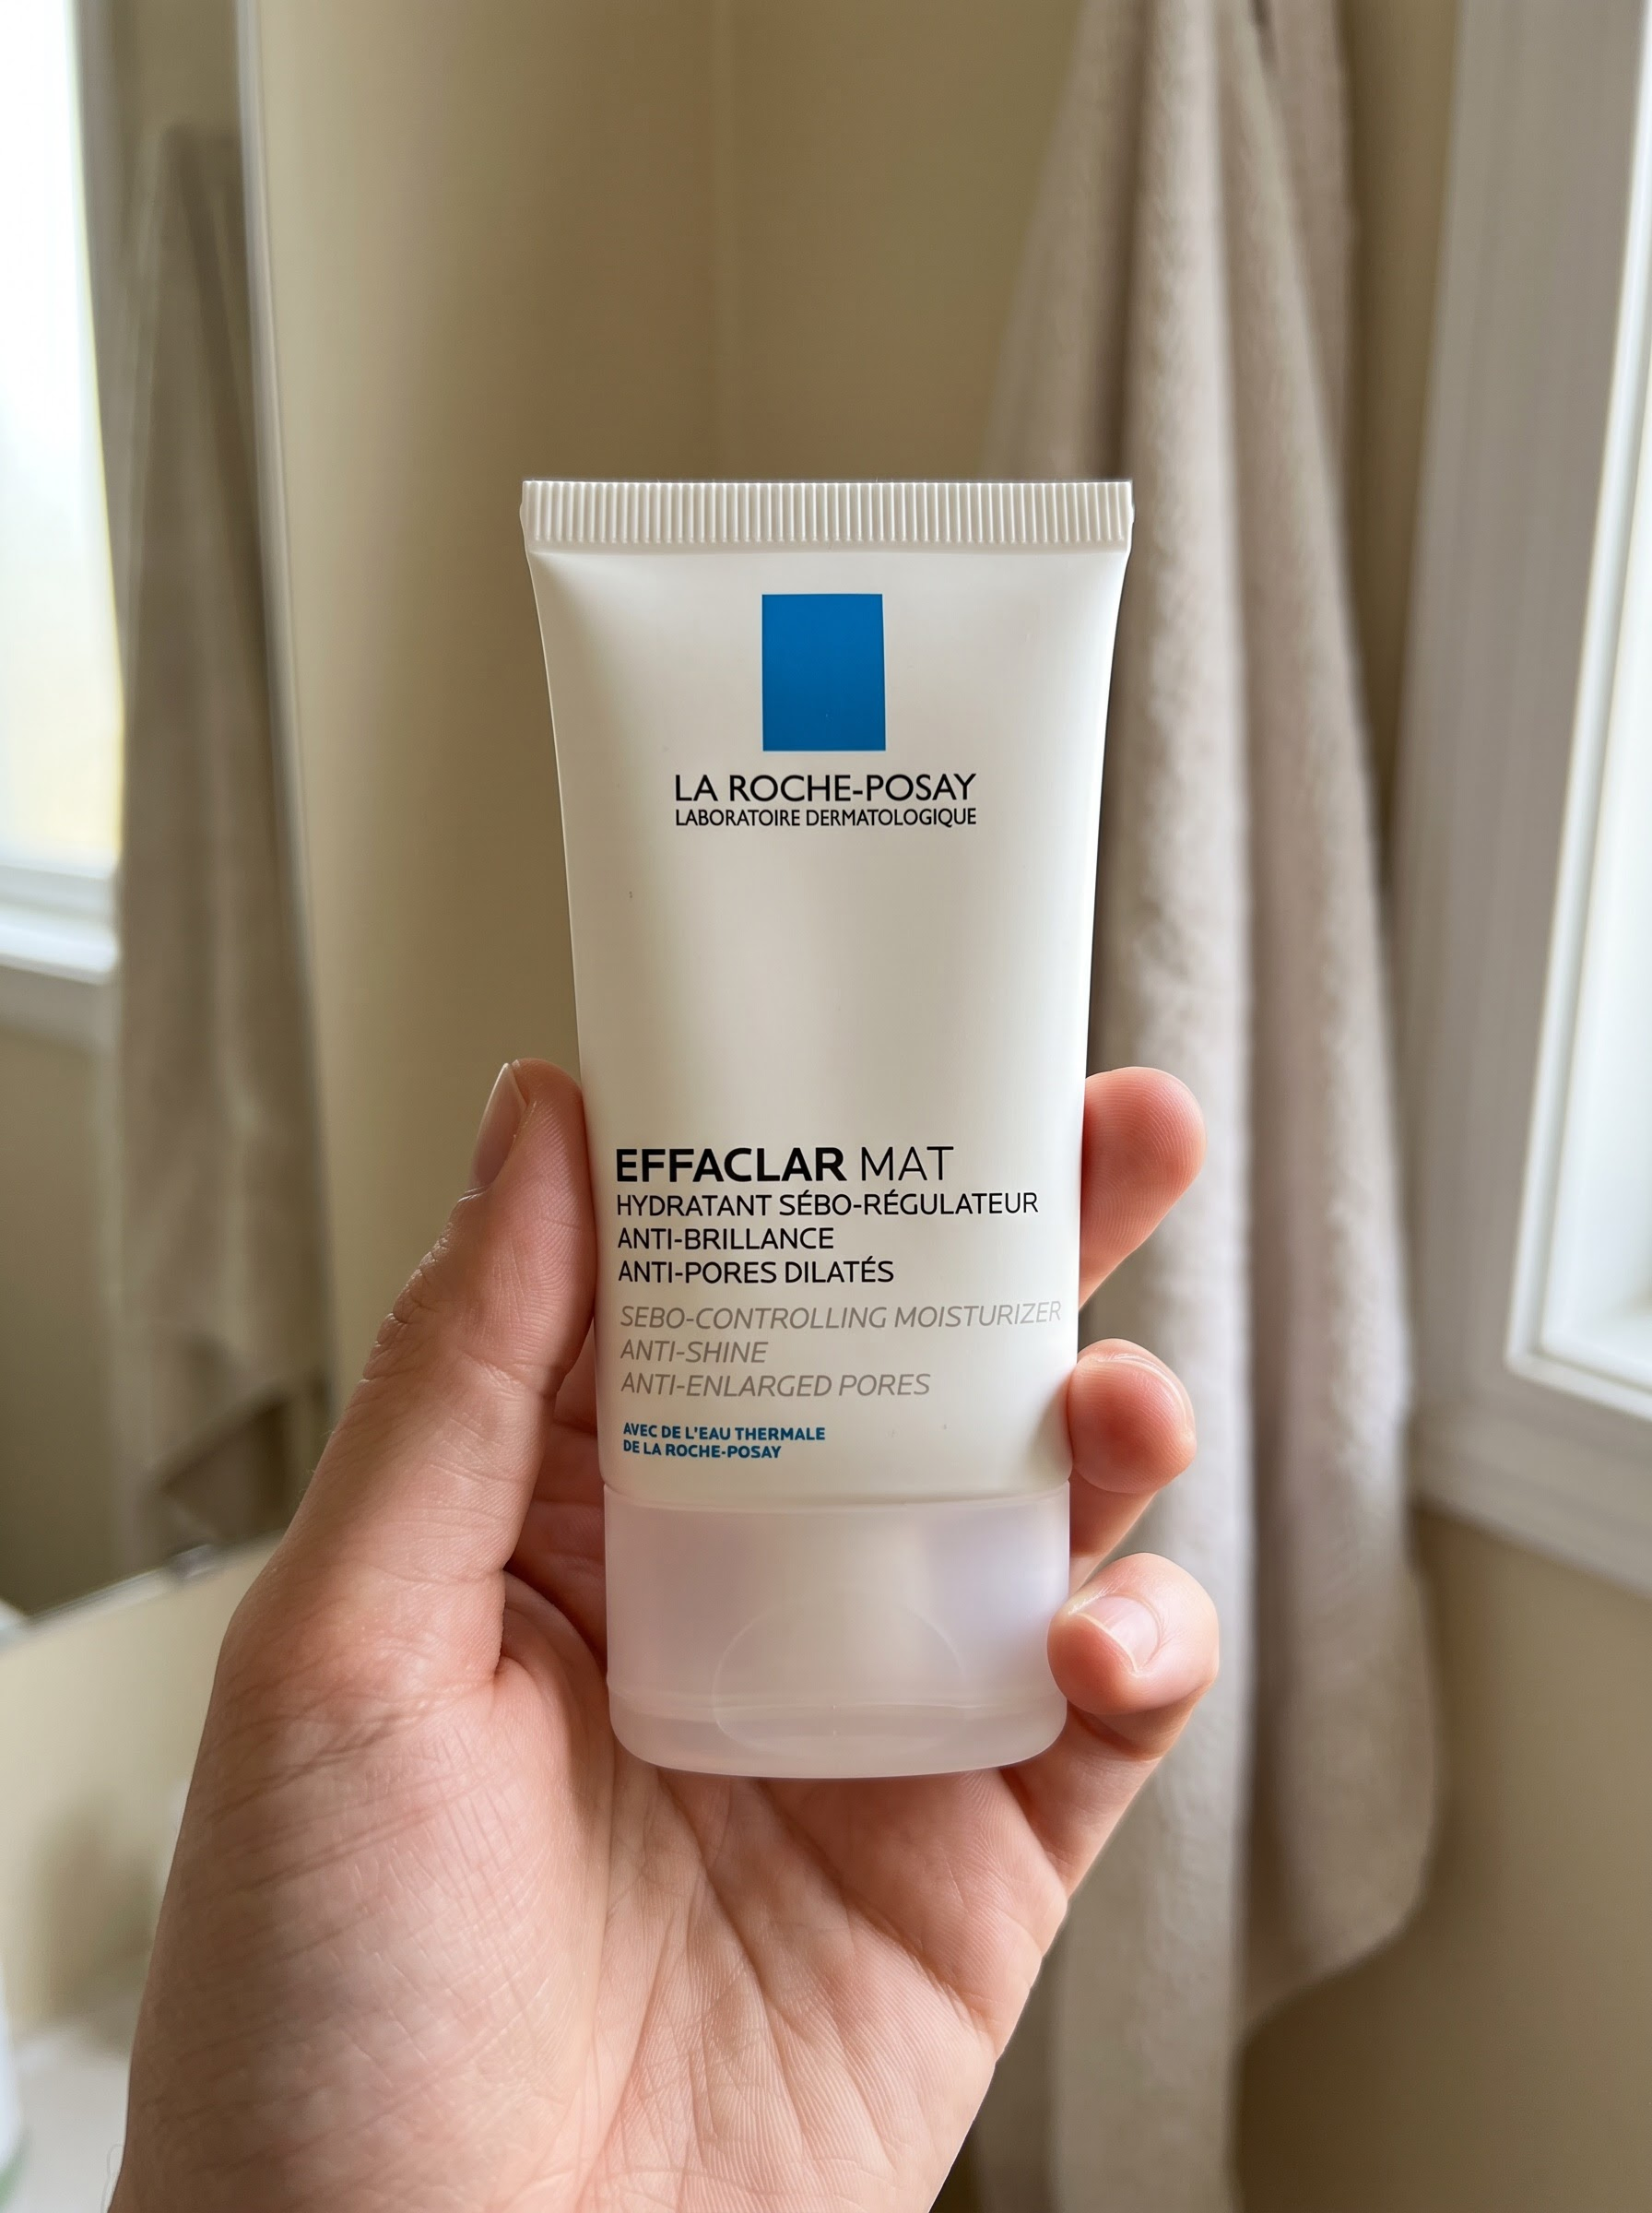
Each model gets that unchanged packshot and the same brief: put the product in an adult hand beside a bathroom window, keep the label uncovered, and reproduce all packaging text. The prompt does not supply the wording; models must read it from the image. One output per model, no reruns. Nano Banana Pro is included in this round only.
Single-product packshot → real scene — all six models
The clean studio reference is the text ground truth. Compare every real-scene result below, or use Scan line to inspect a pair.
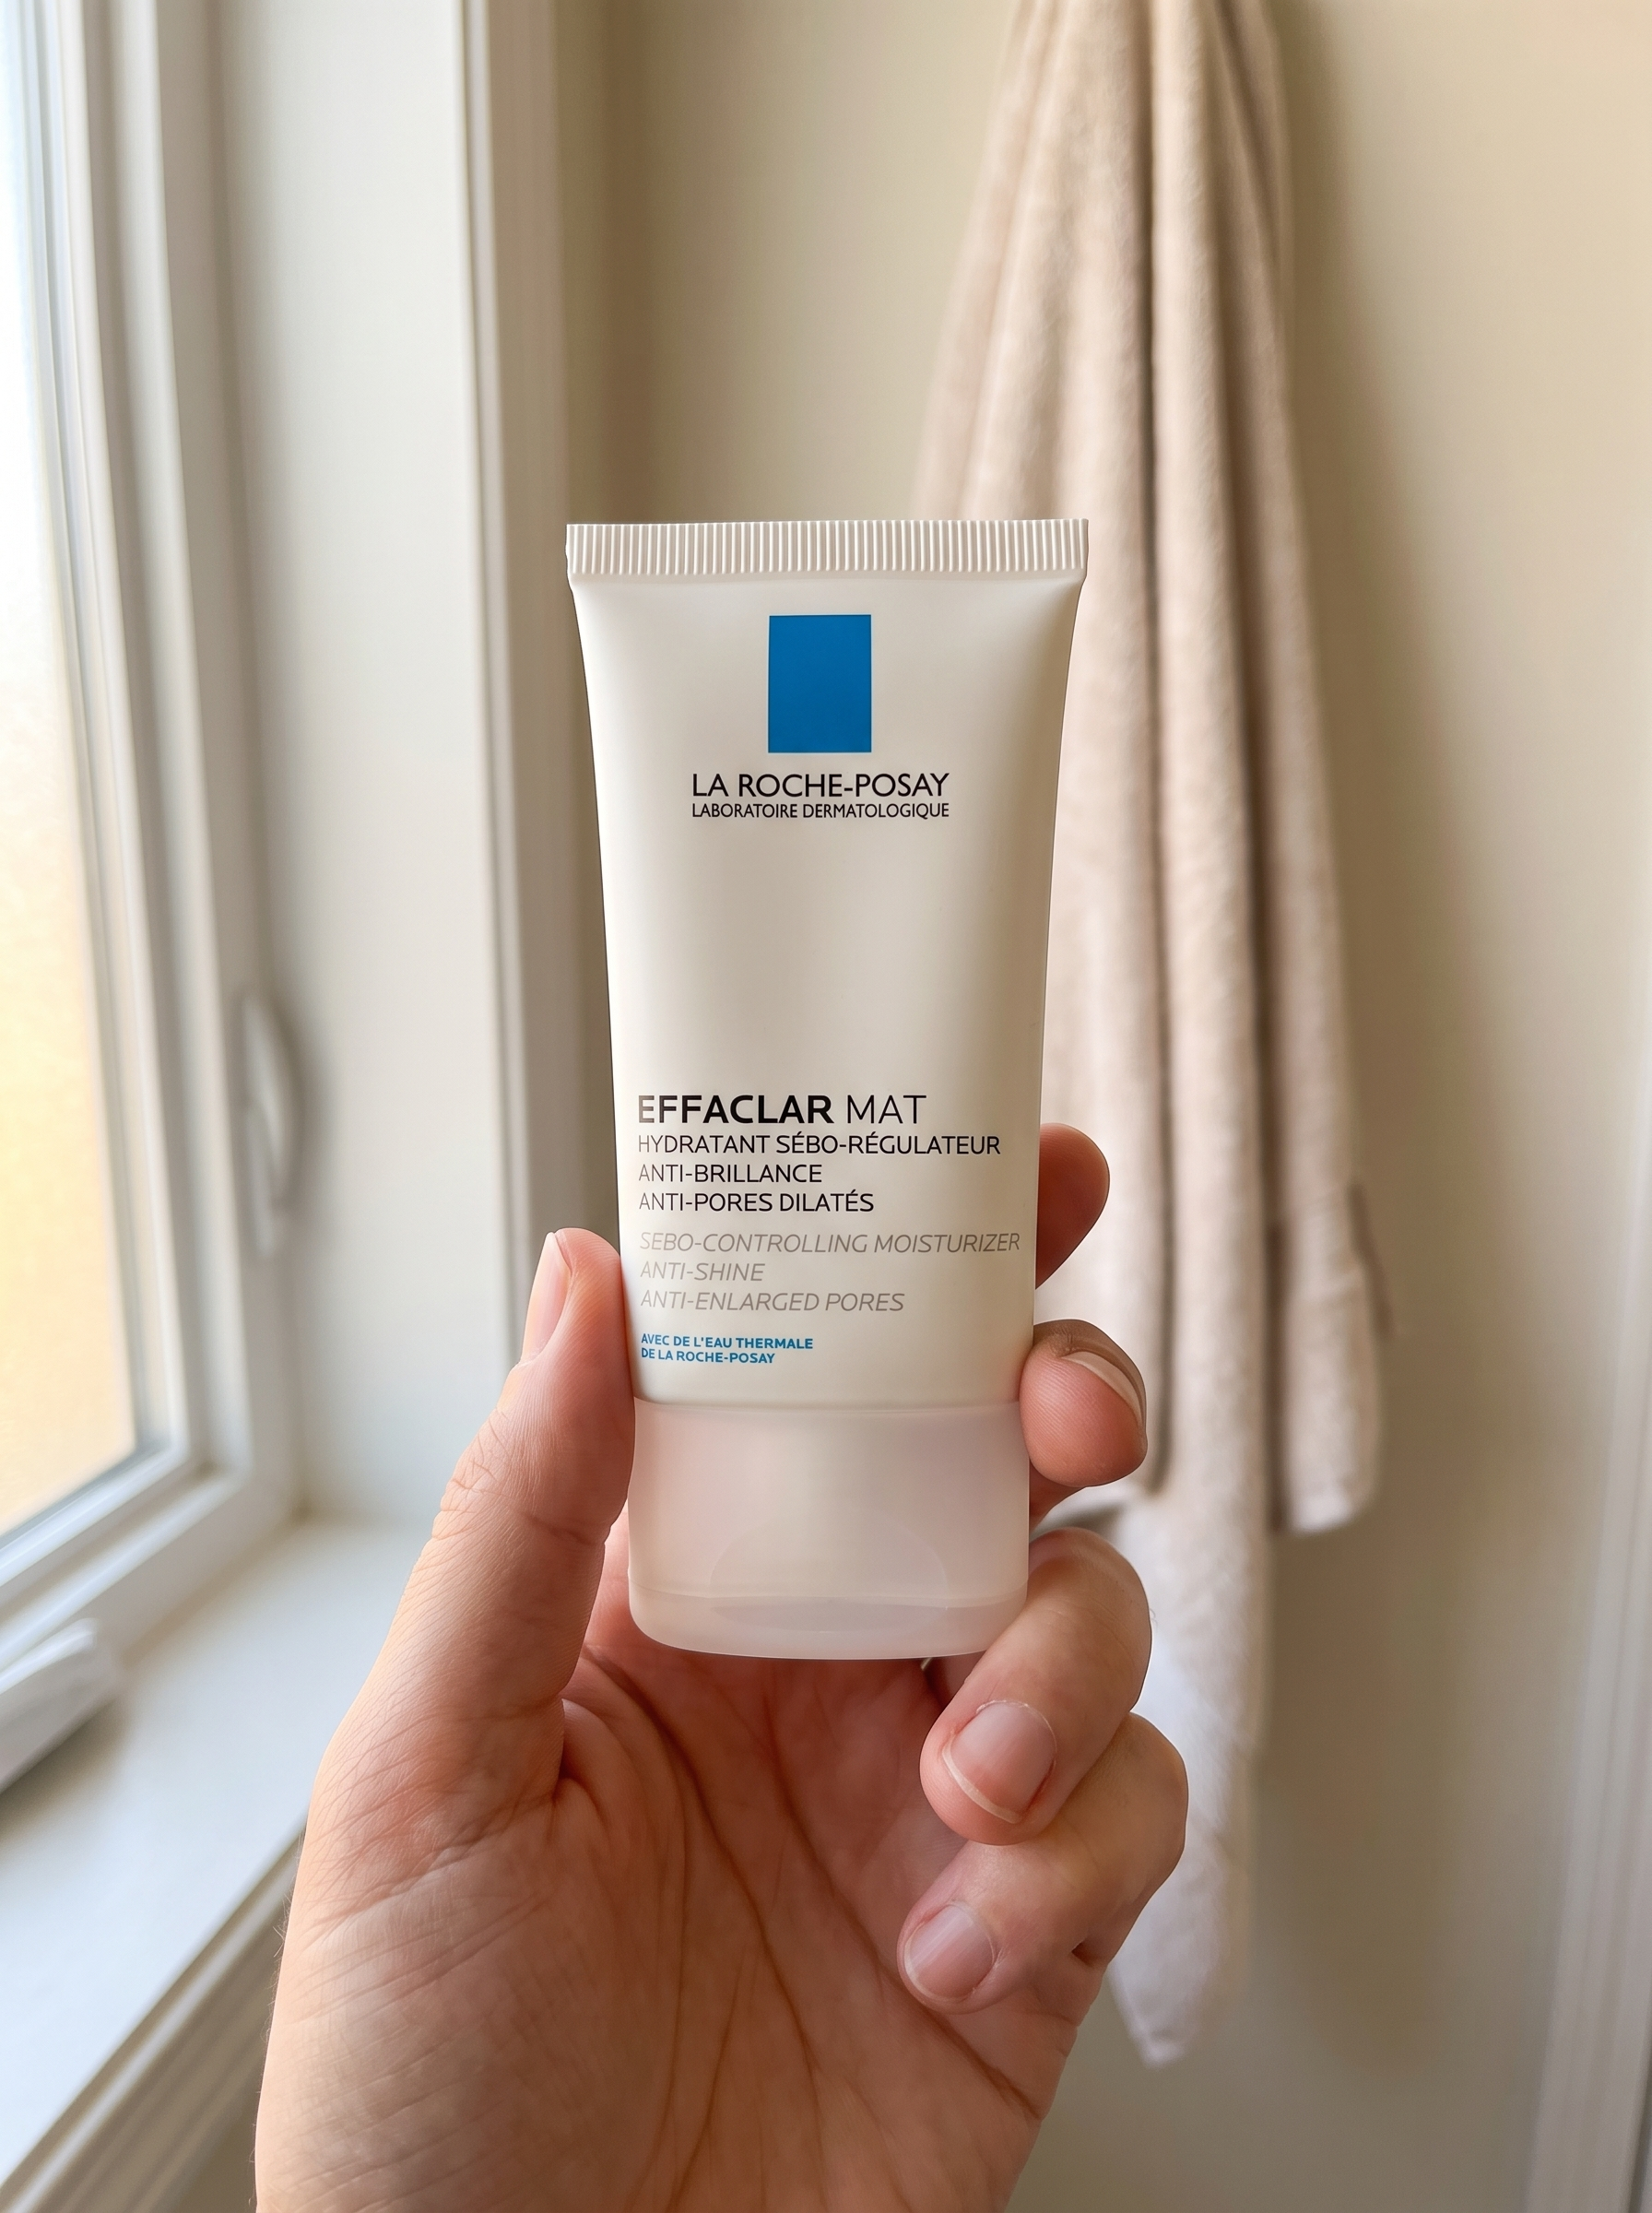
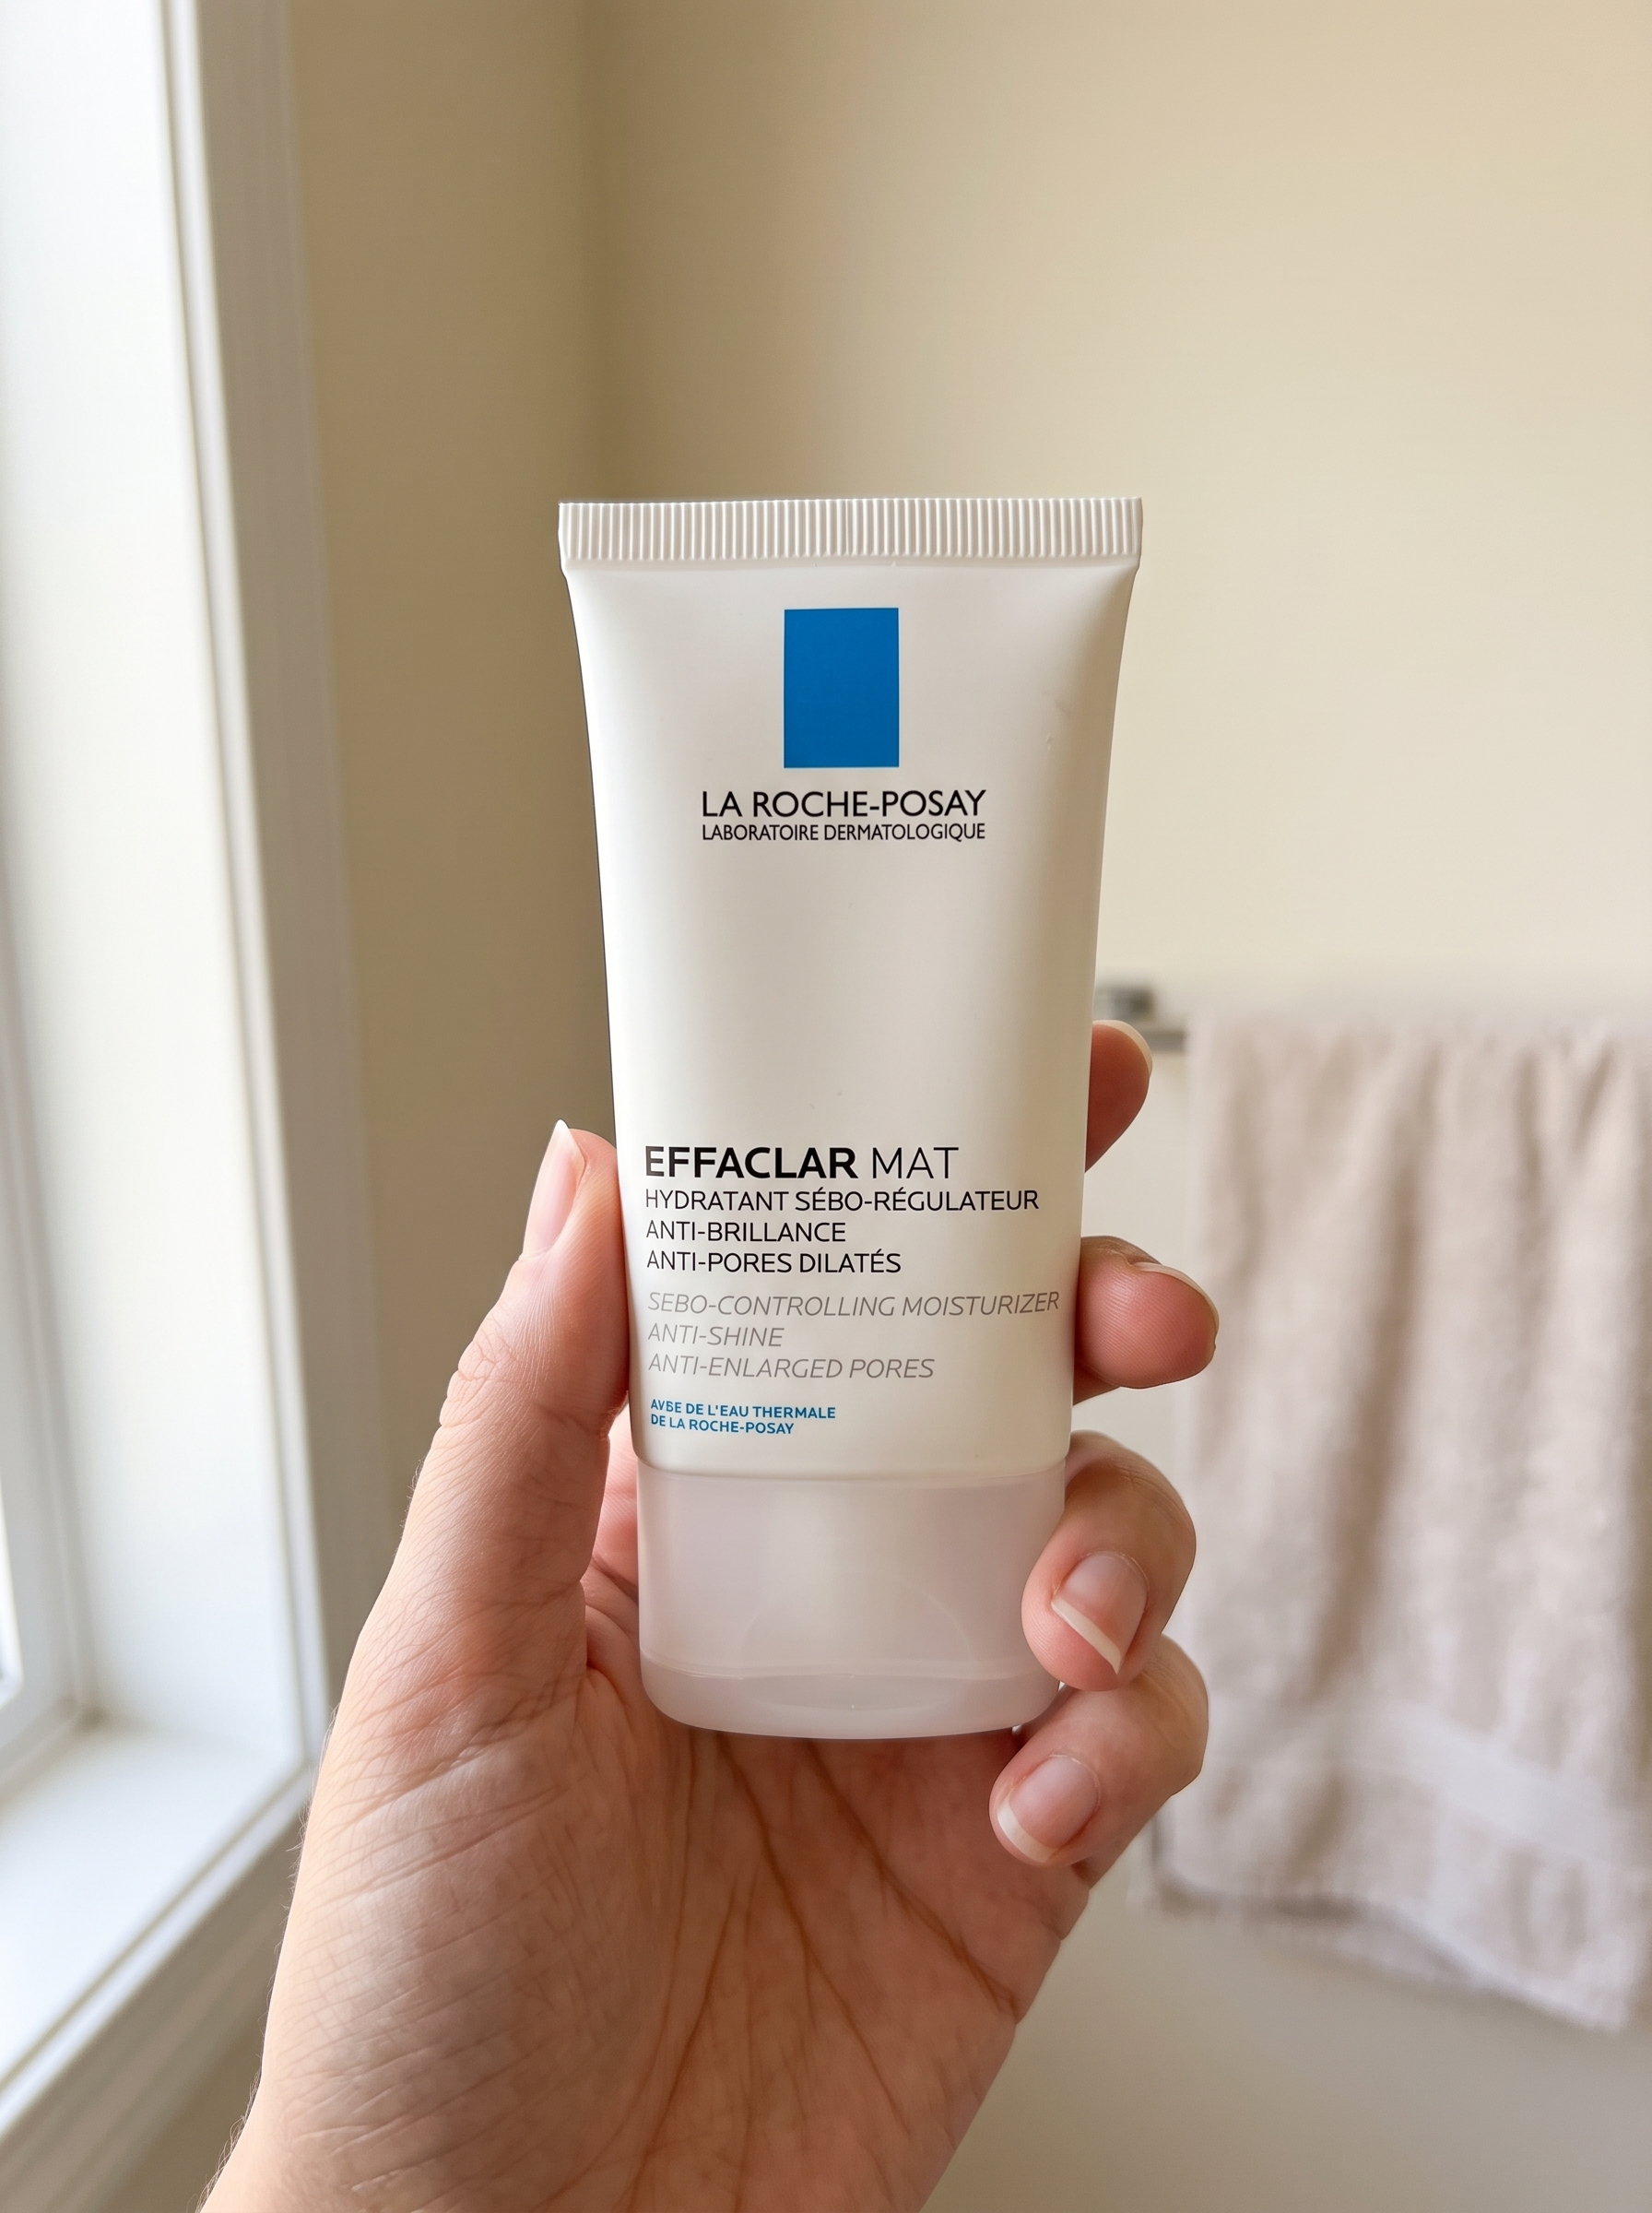
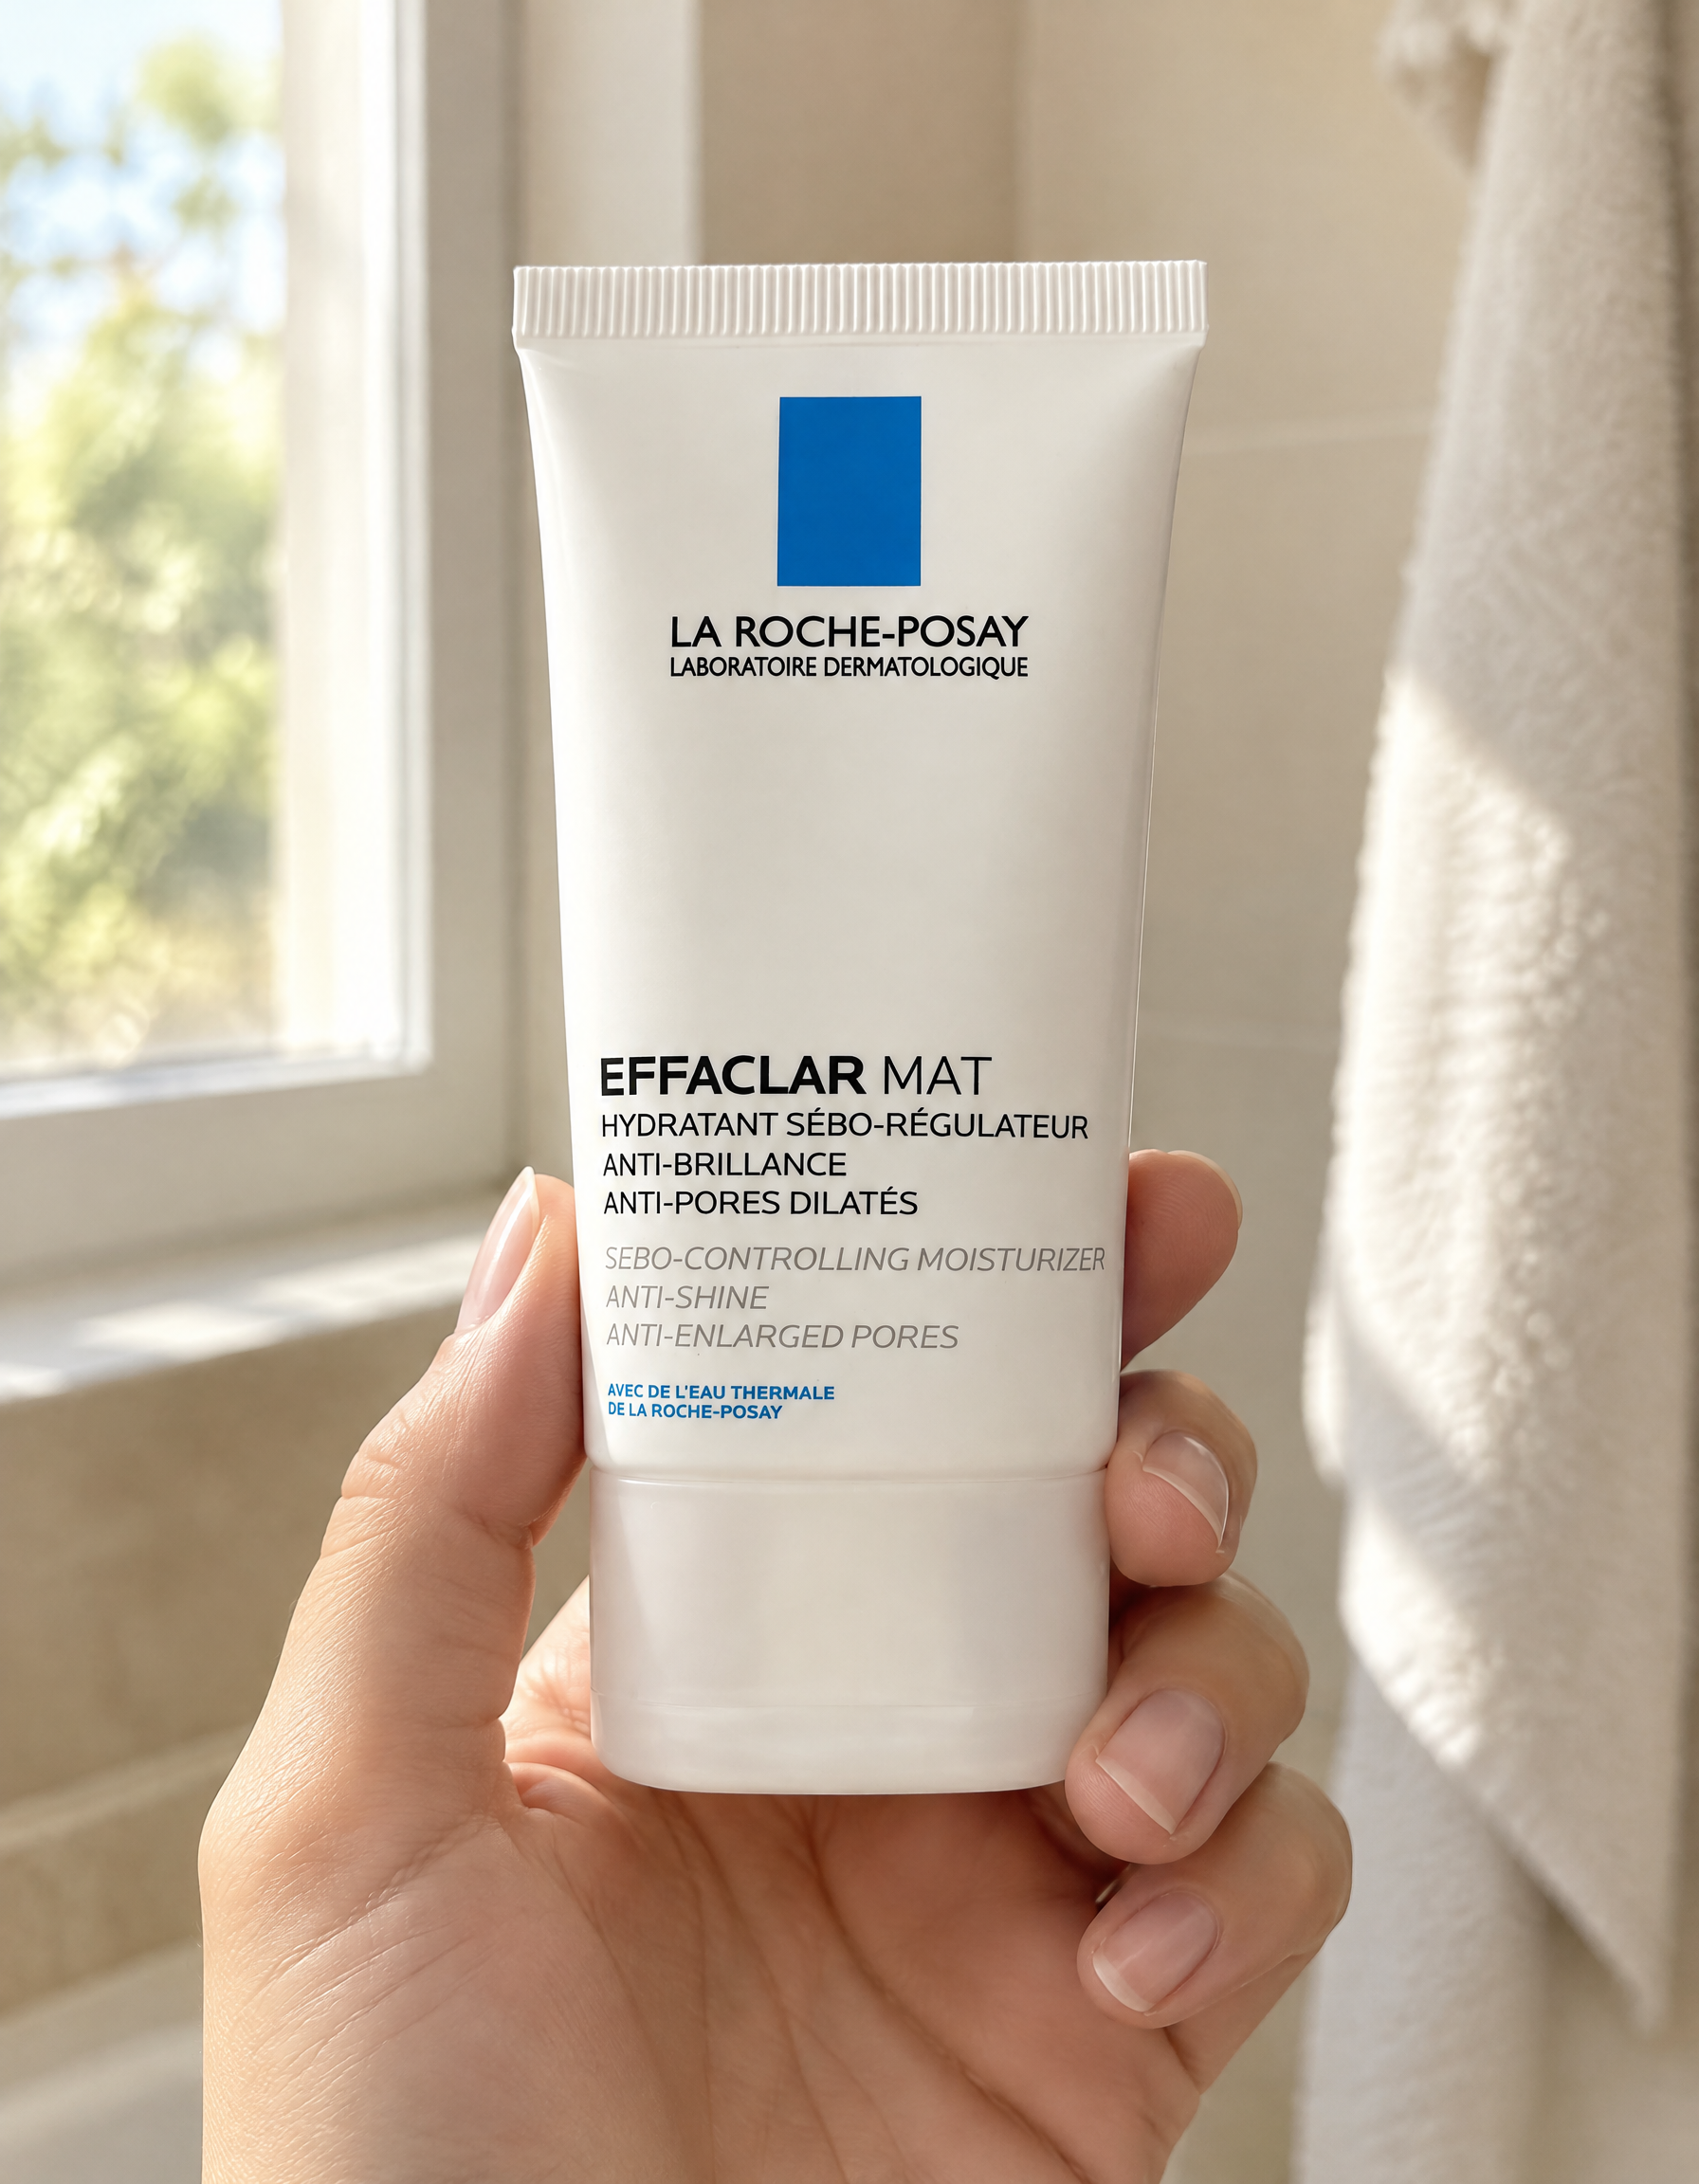
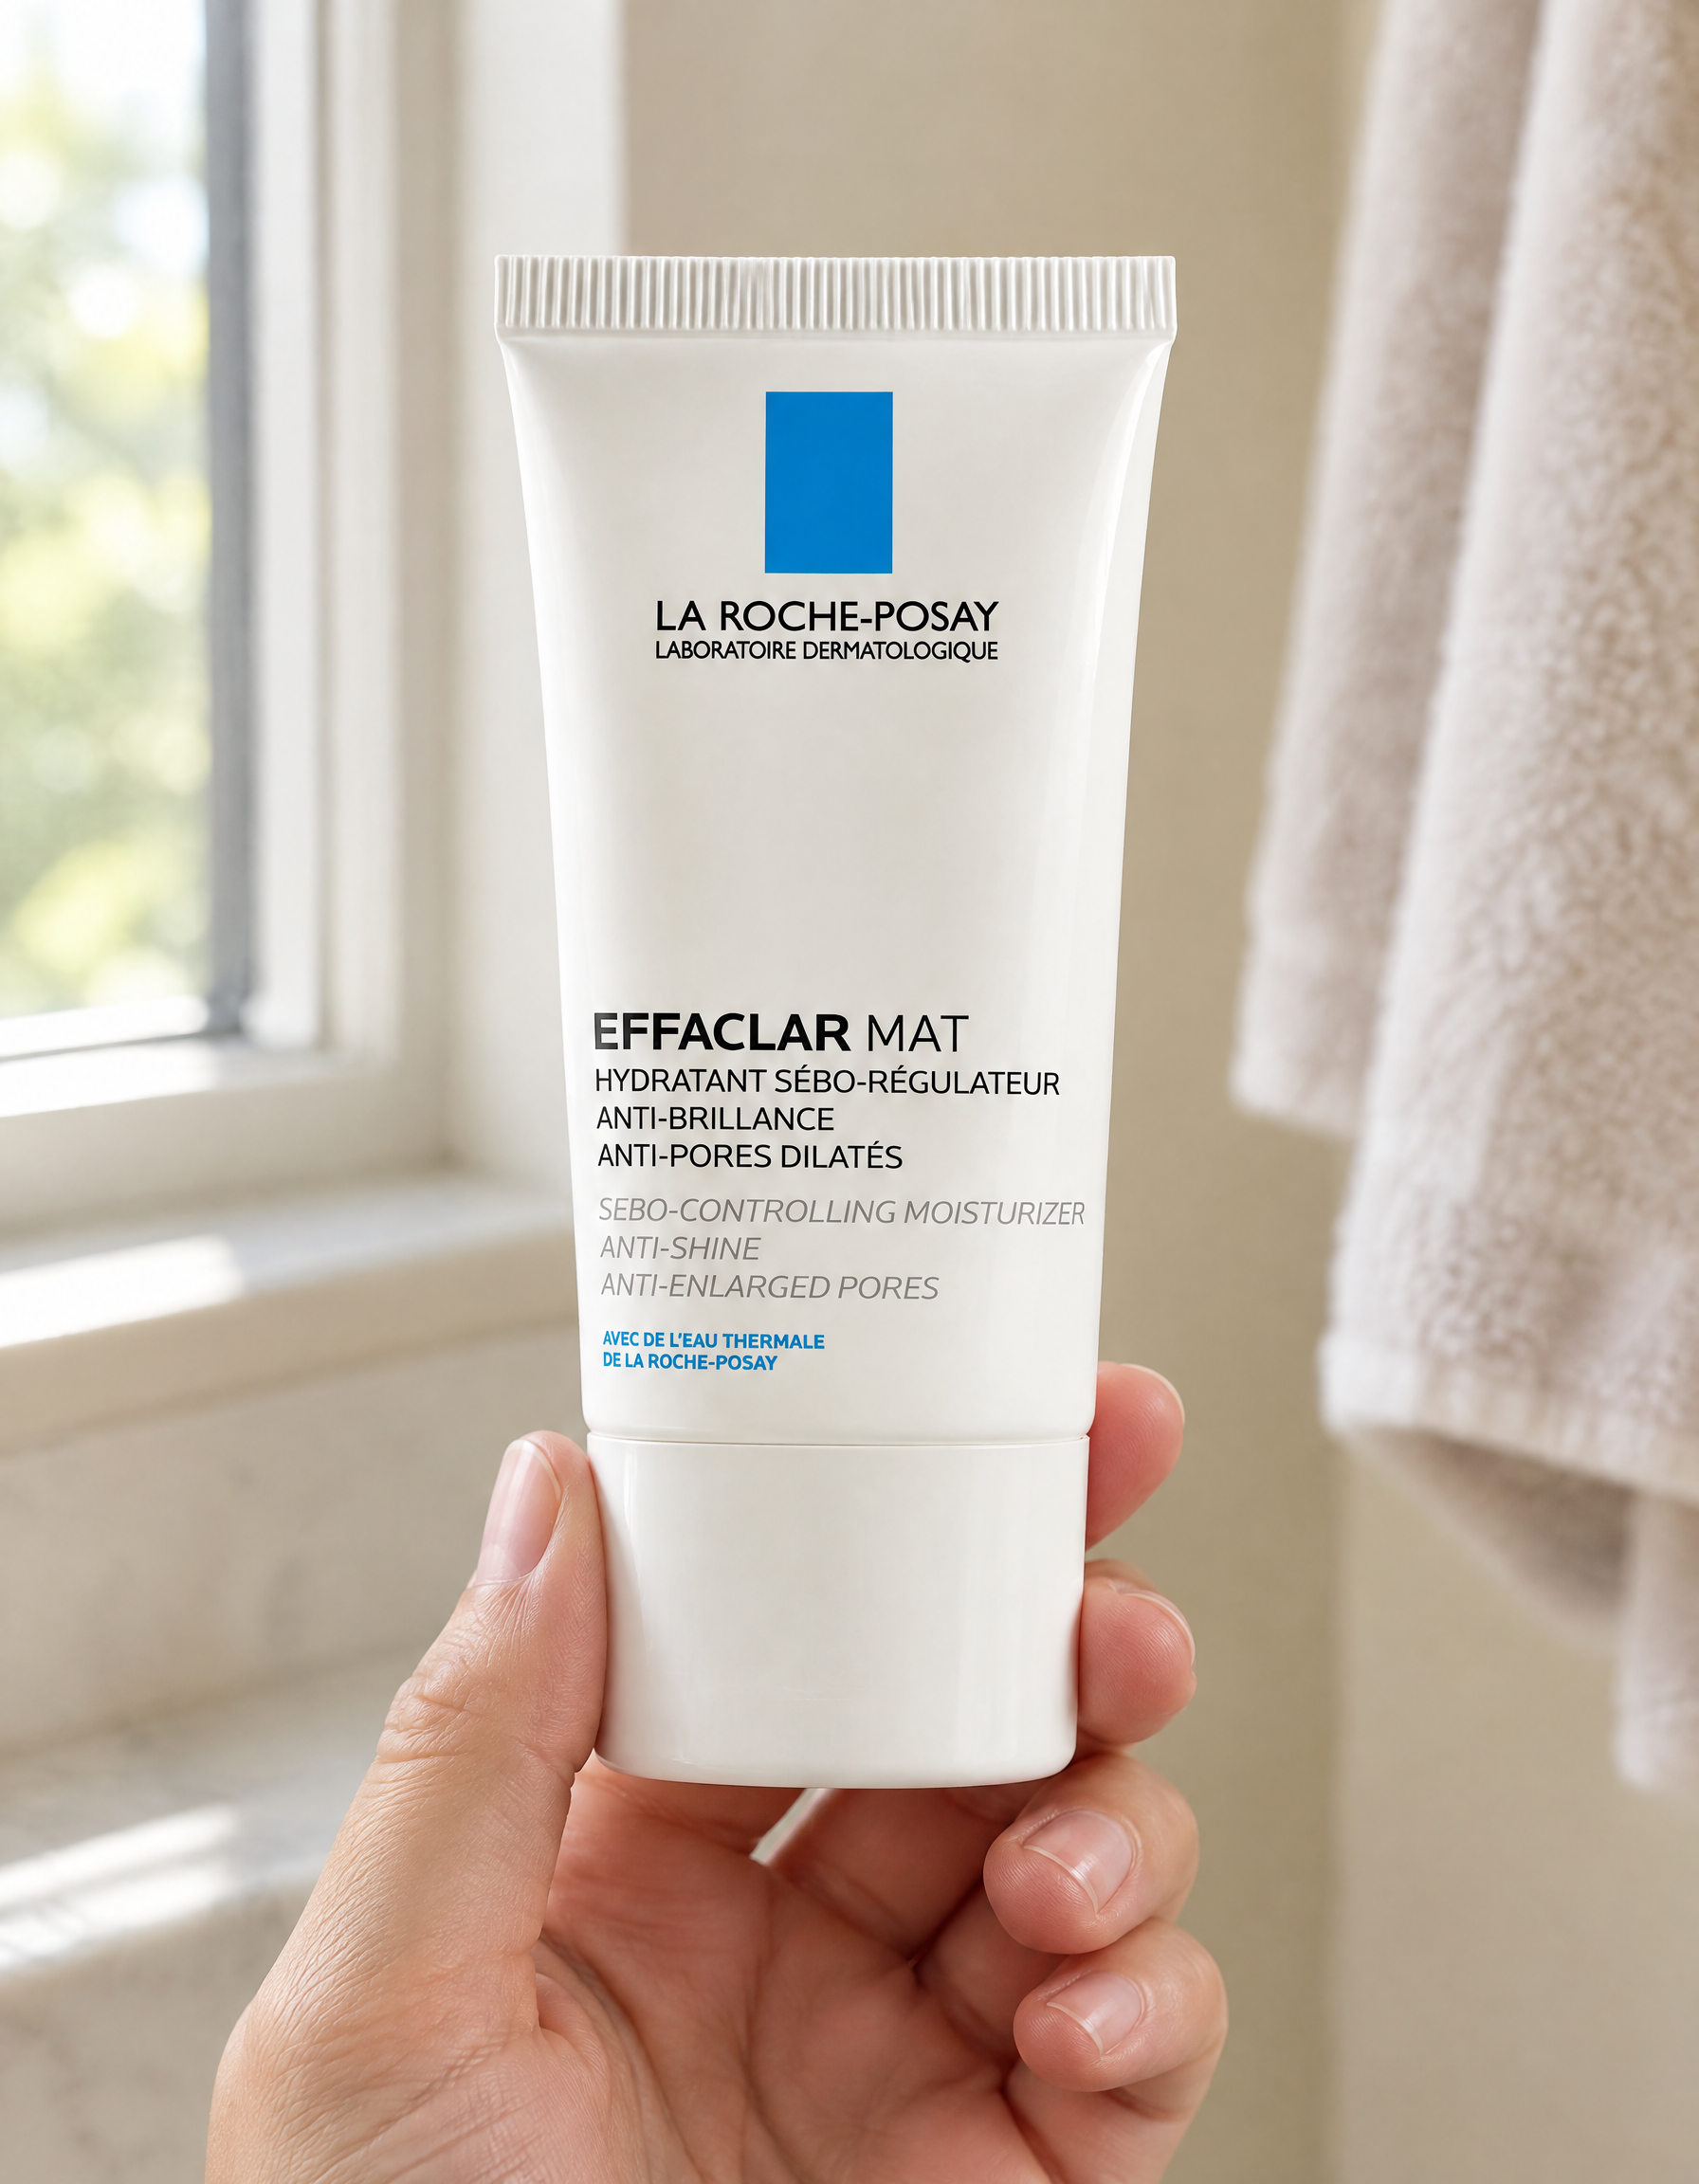
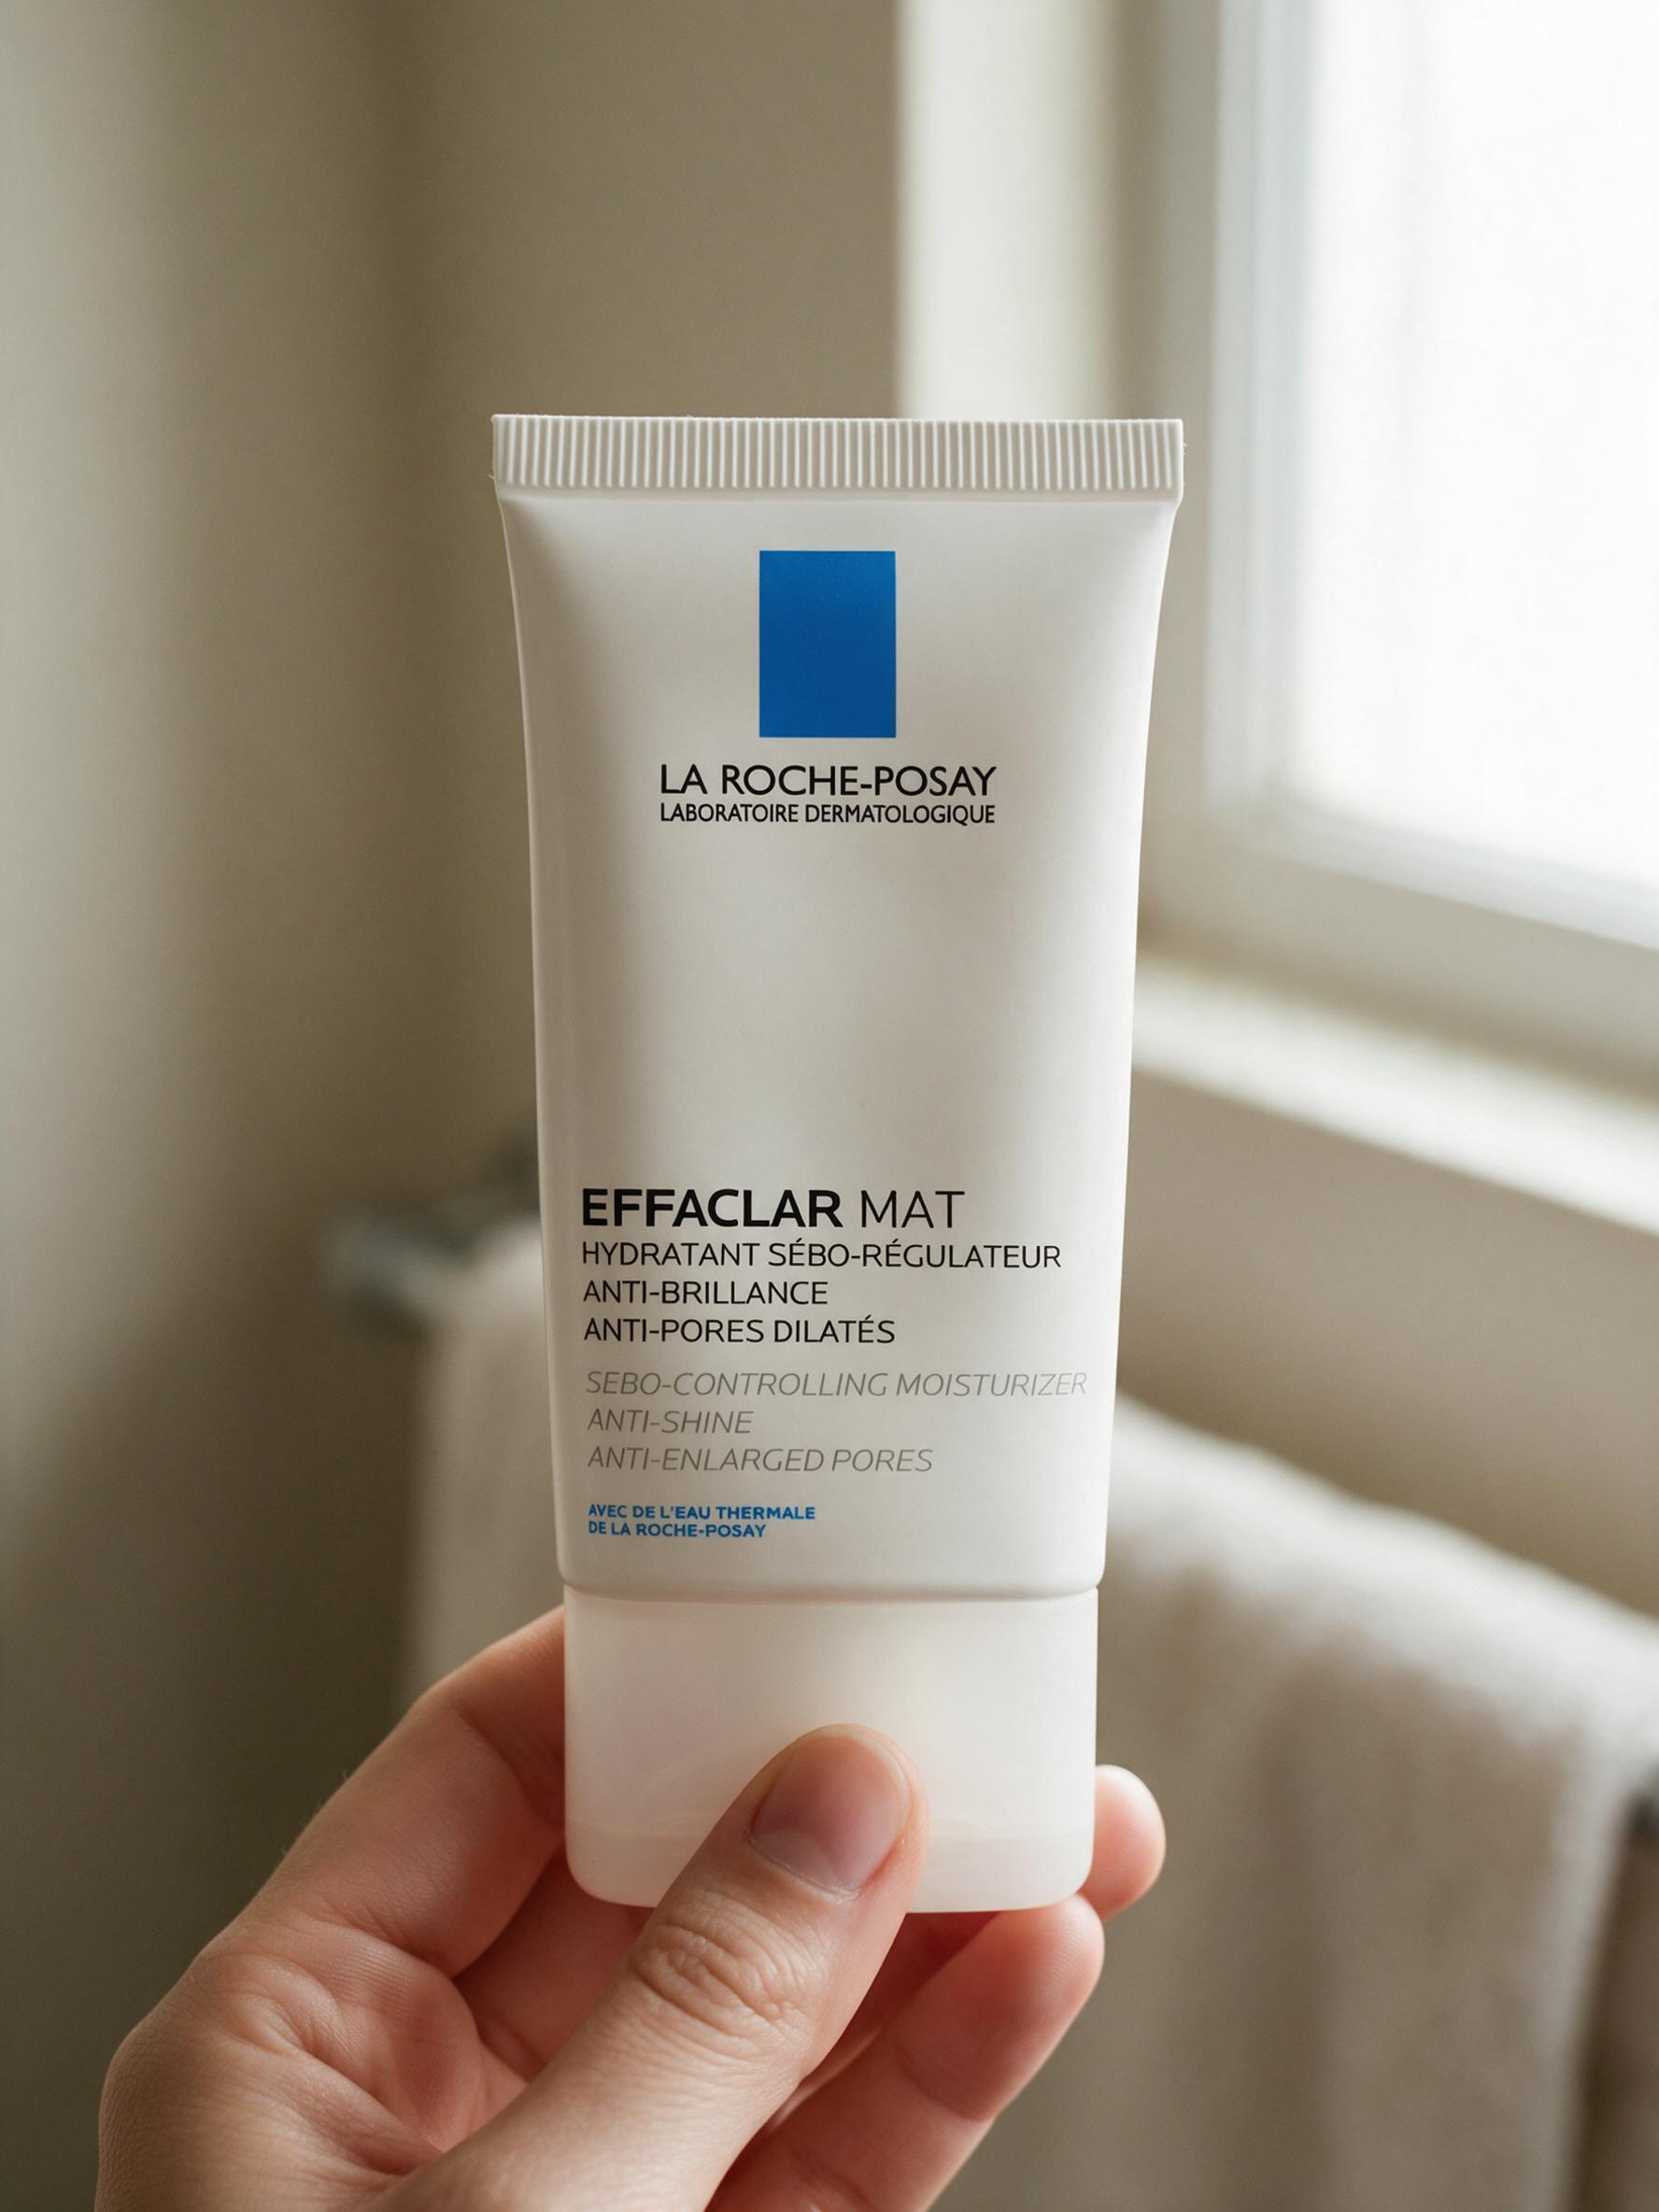
| Model | Exact text lines preserved | Result |
|---|---|---|
| Nano Banana 2.1 | 11 / 11 | Keeps all measured wording, accents and small blue copy. |
| Nano Banana Pro | 11 / 11 | Keeps all measured wording, including the small blue copy. |
| Nano Banana 2.0 | 10 / 11 | Changes the small blue “AVEC” to “AVBE”. |
| Sunburst | 11 / 11 | Keeps all measured wording and French accents. |
| Flare | 11 / 11 | Keeps all measured wording and the small blue copy. |
| Seedream 5 Pro | 11 / 11 | Keeps all measured wording and French accents. |
We manually checked the 11 source lines against each full-resolution output. A line passes only when its complete wording, accents and punctuation remain correct and legible; letter case, spacing and apostrophe styling do not affect the score. This measures copy reproduction in these six images, not exact typography or product geometry. The models still redraw type weight and cap details.
For this brief, 2.1 joins the leading group and avoids the predecessor’s small-copy error. A clear packshot makes this a useful test of text preservation when moving a product into a real scene; one sample per model cannot establish a general accuracy ranking.
Identity across two poses
For identity ground truth we adopted a detailed, synthetic portrait from our earlier GPT Image 2 benchmark: 1792 × 2304 pixels, not an enlarged casting thumbnail. Its wavy dark bob, green eyes, facial proportions and skin marks are the visual anchors. It already includes the jacket, so the separate garment reference reinforces that cue. This tests one supplied identity across views, not independent casting or every possible garment assignment. A source created by GPT Image 2 may also favor related models; a wider production study needs more casts and source styles.
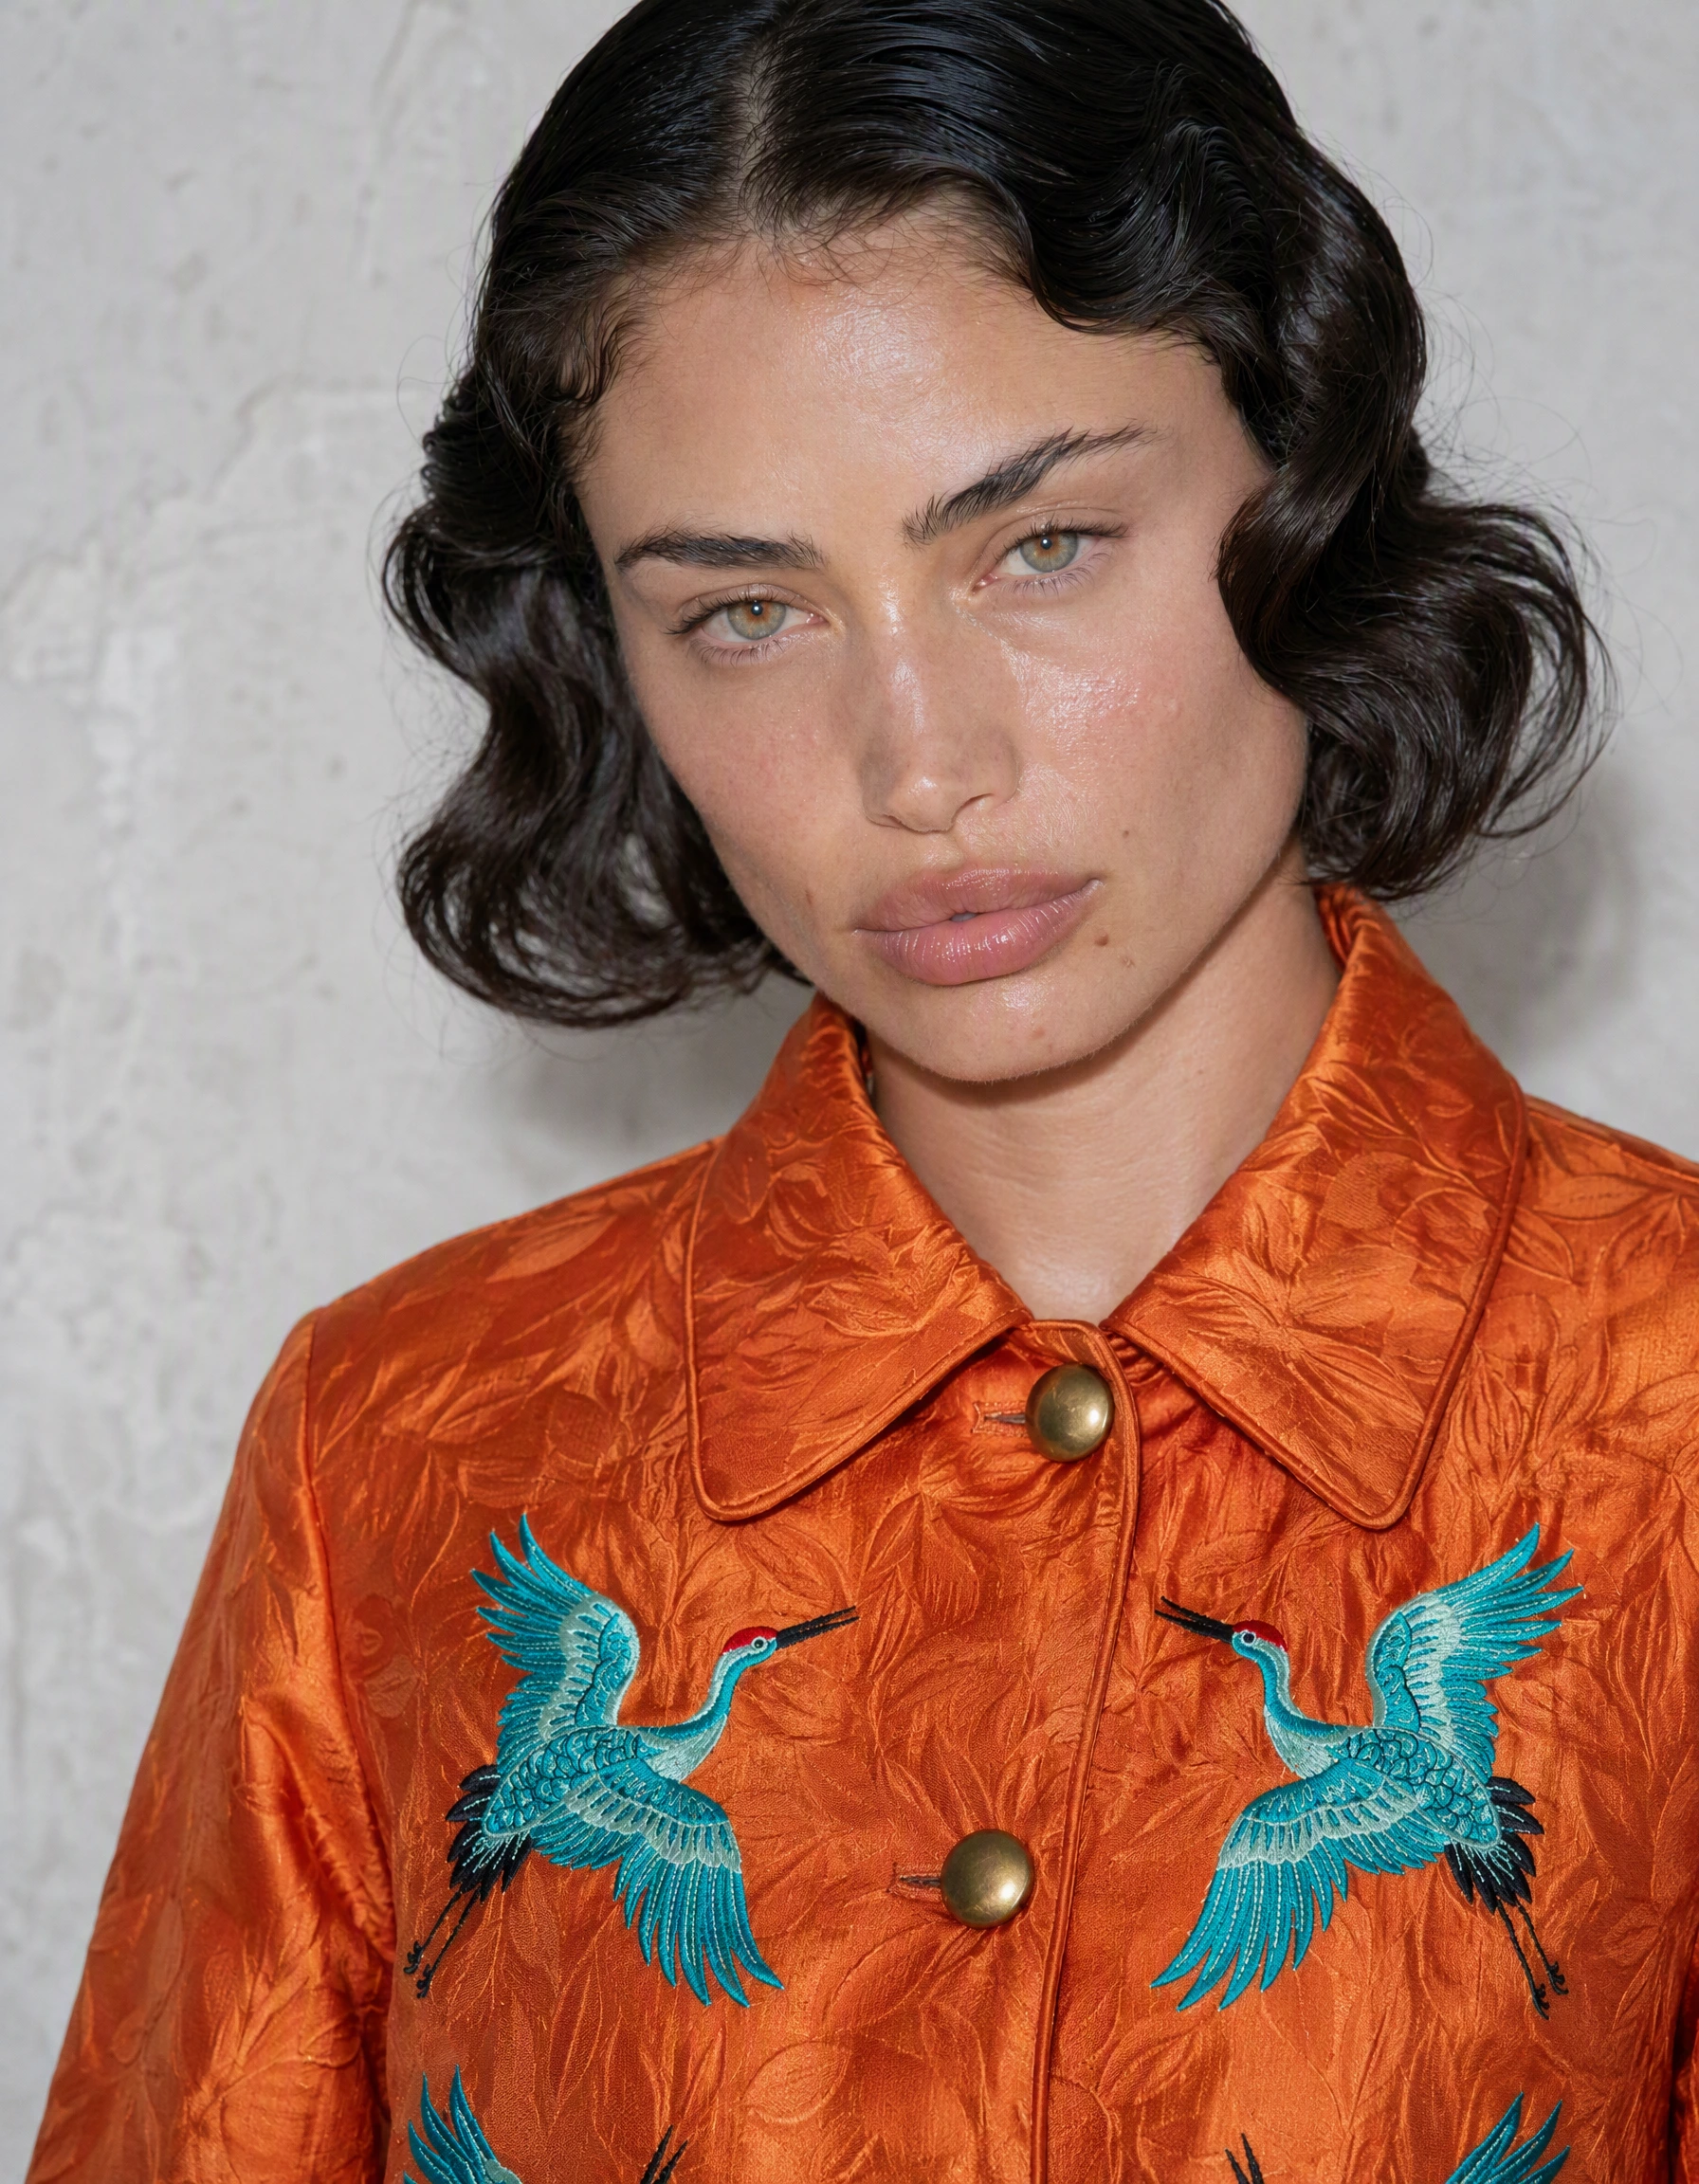
The first brief asks for a front-view waist-up portrait including the complete jacket and hem. The second changes only the pose: a 30-degree turn to camera-left, with the face looking back at camera. Both request the same facial and garment features, ivory background, soft light, no jewelry and no added text.
Front view — identity versus pose compliance
Same cast, jacket, semantic prompt and requested settings. Use the source references above to assess identity and garment detail.
Use this face and the separate jacket reference above to check each output.
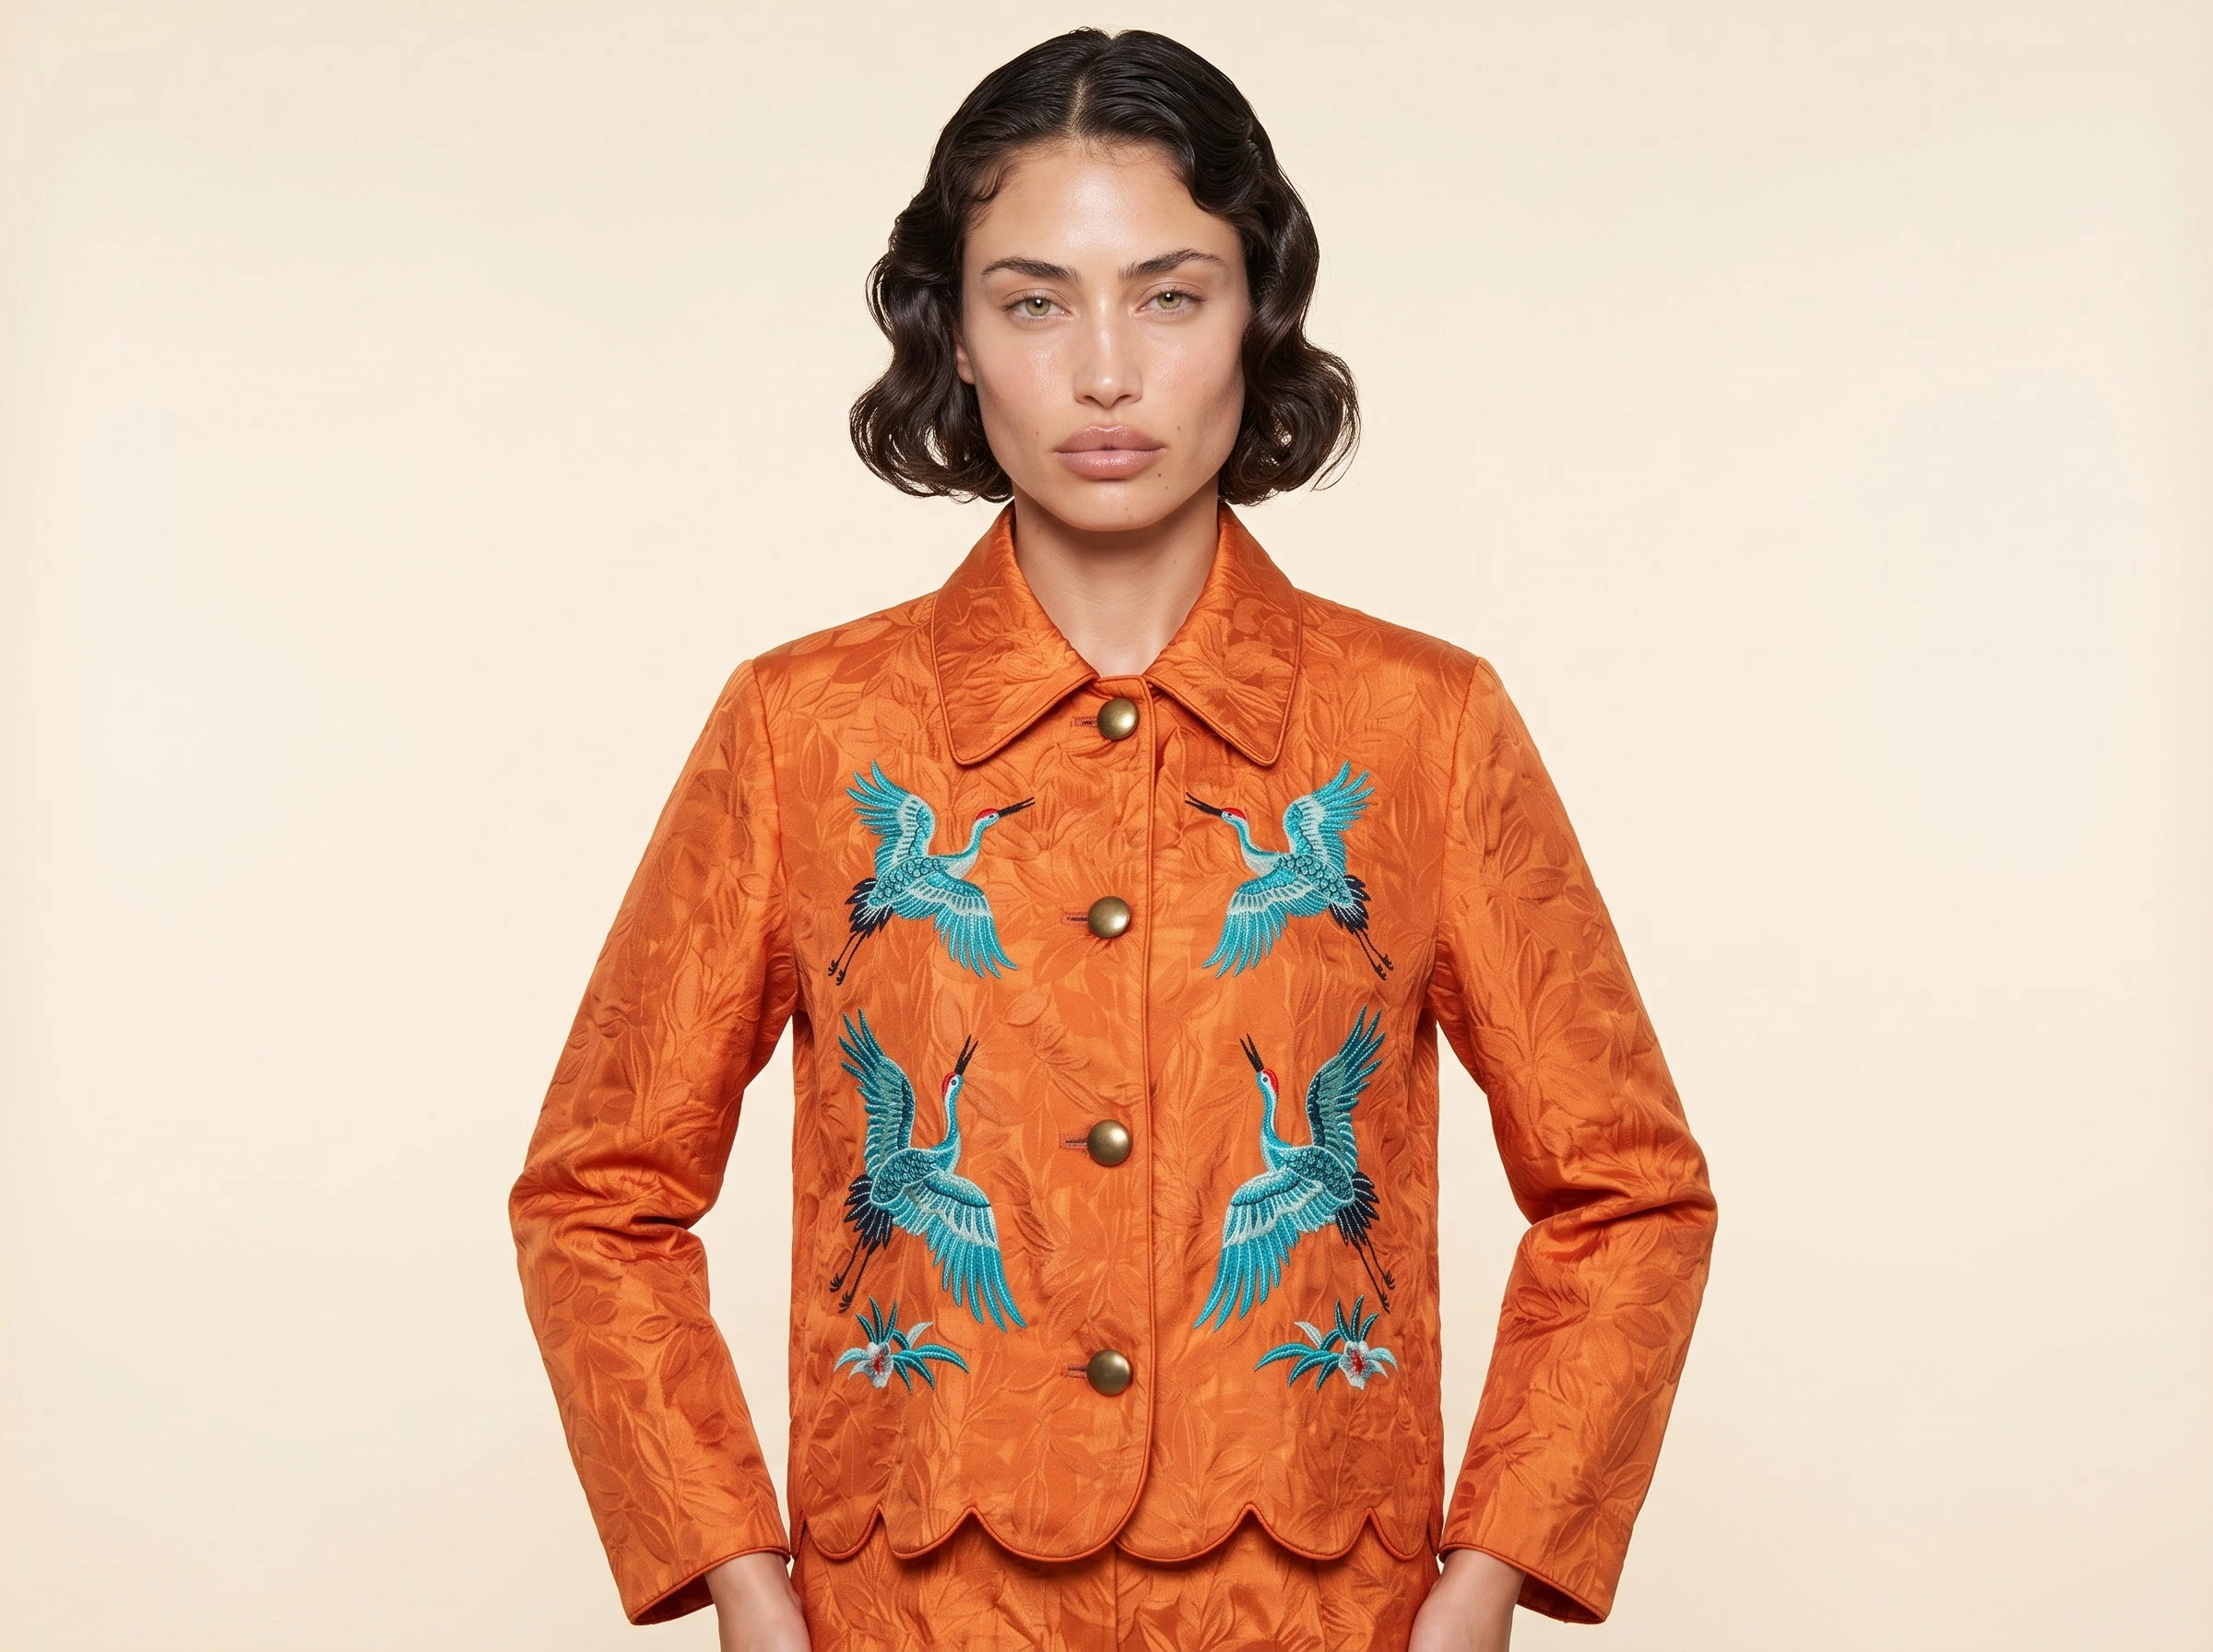
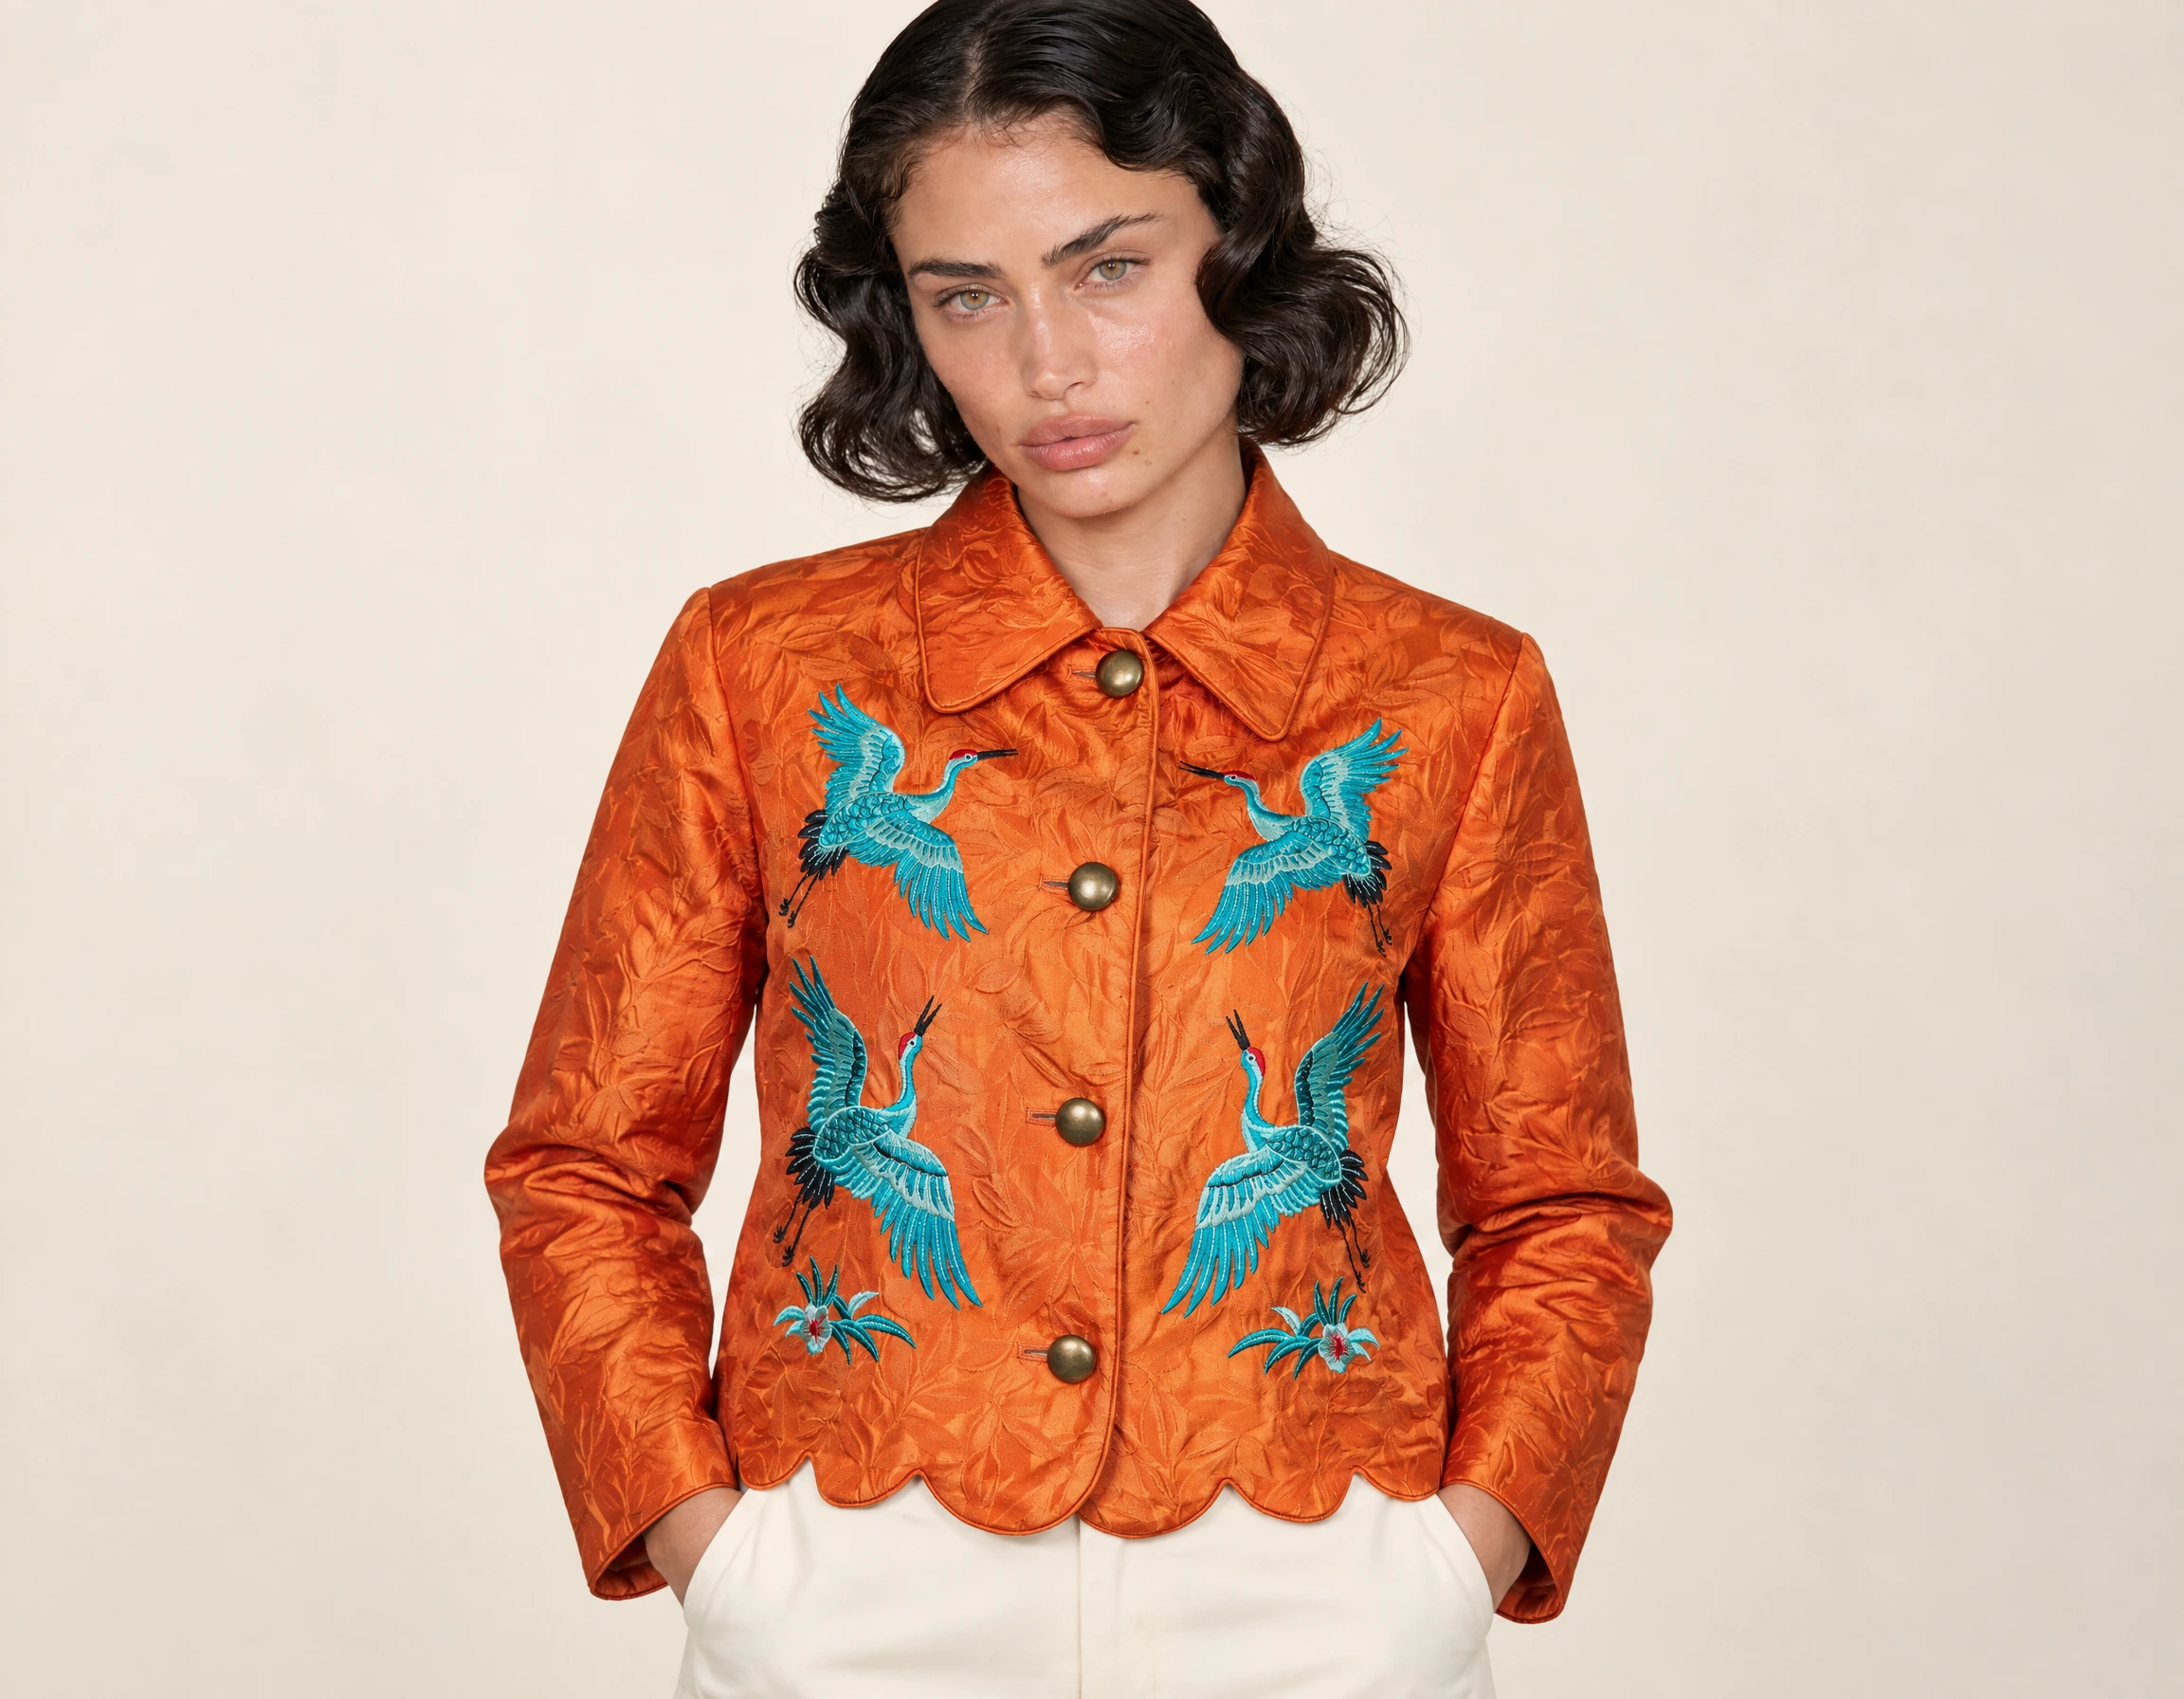
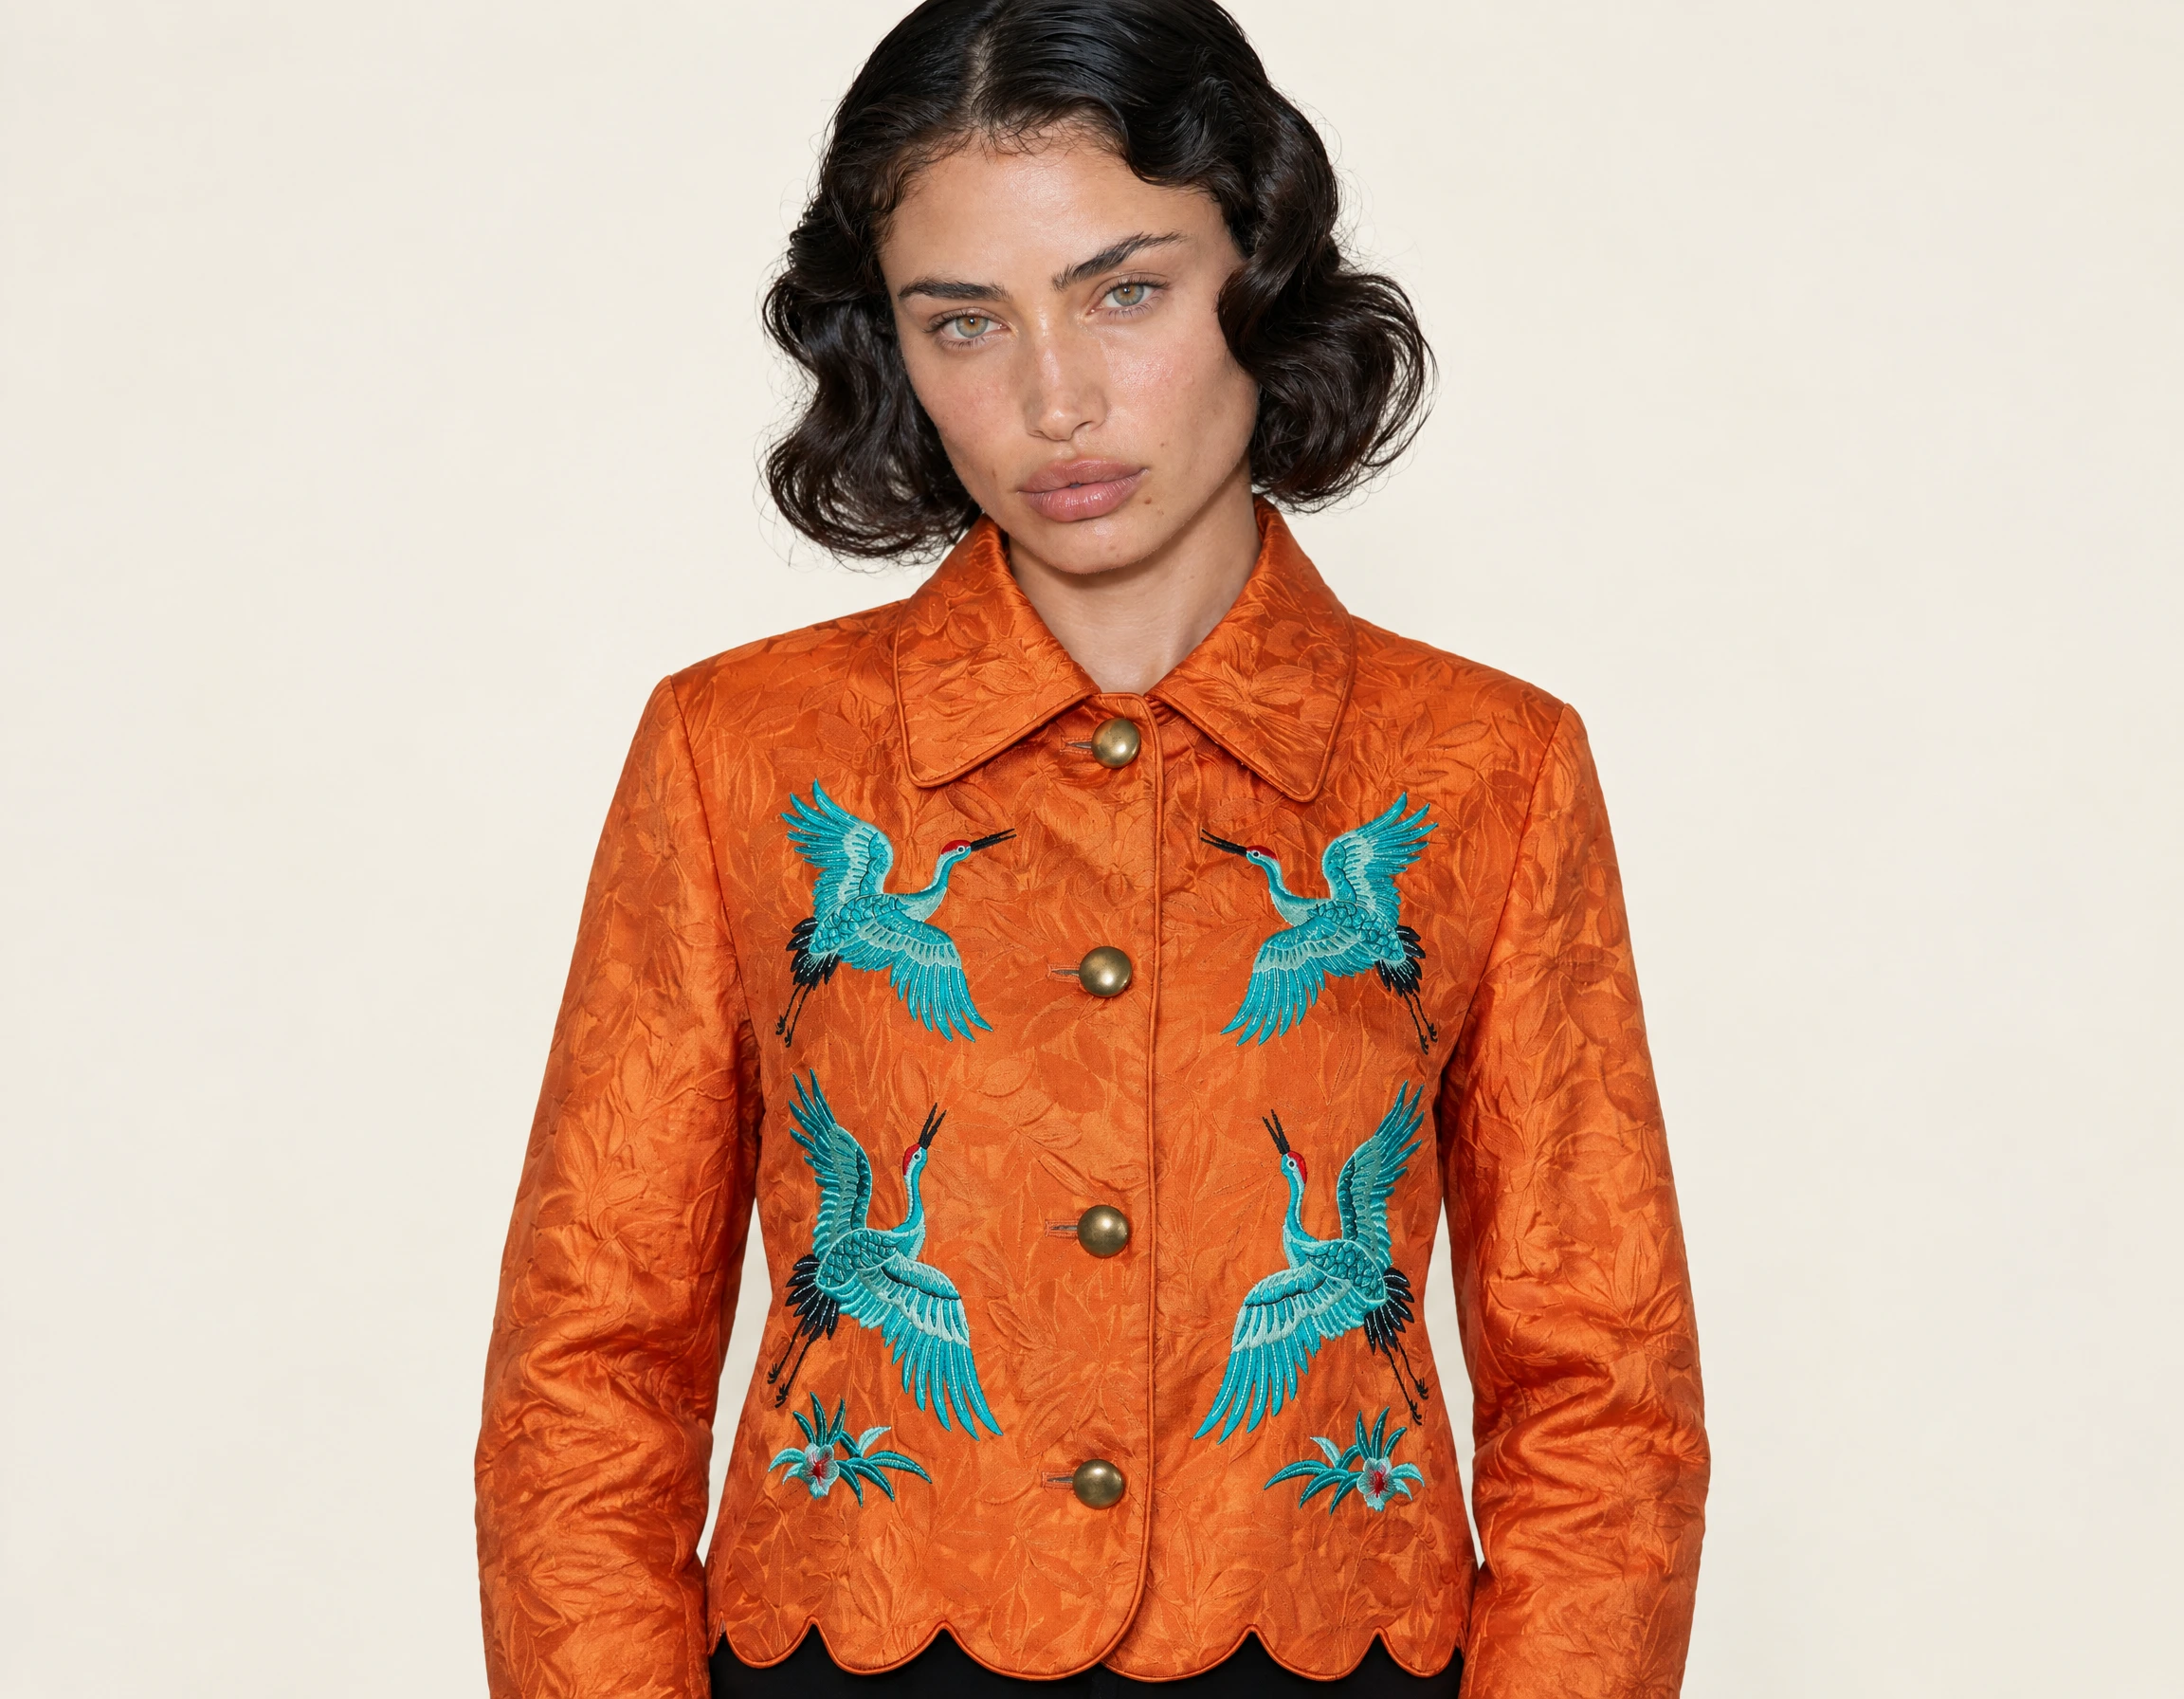
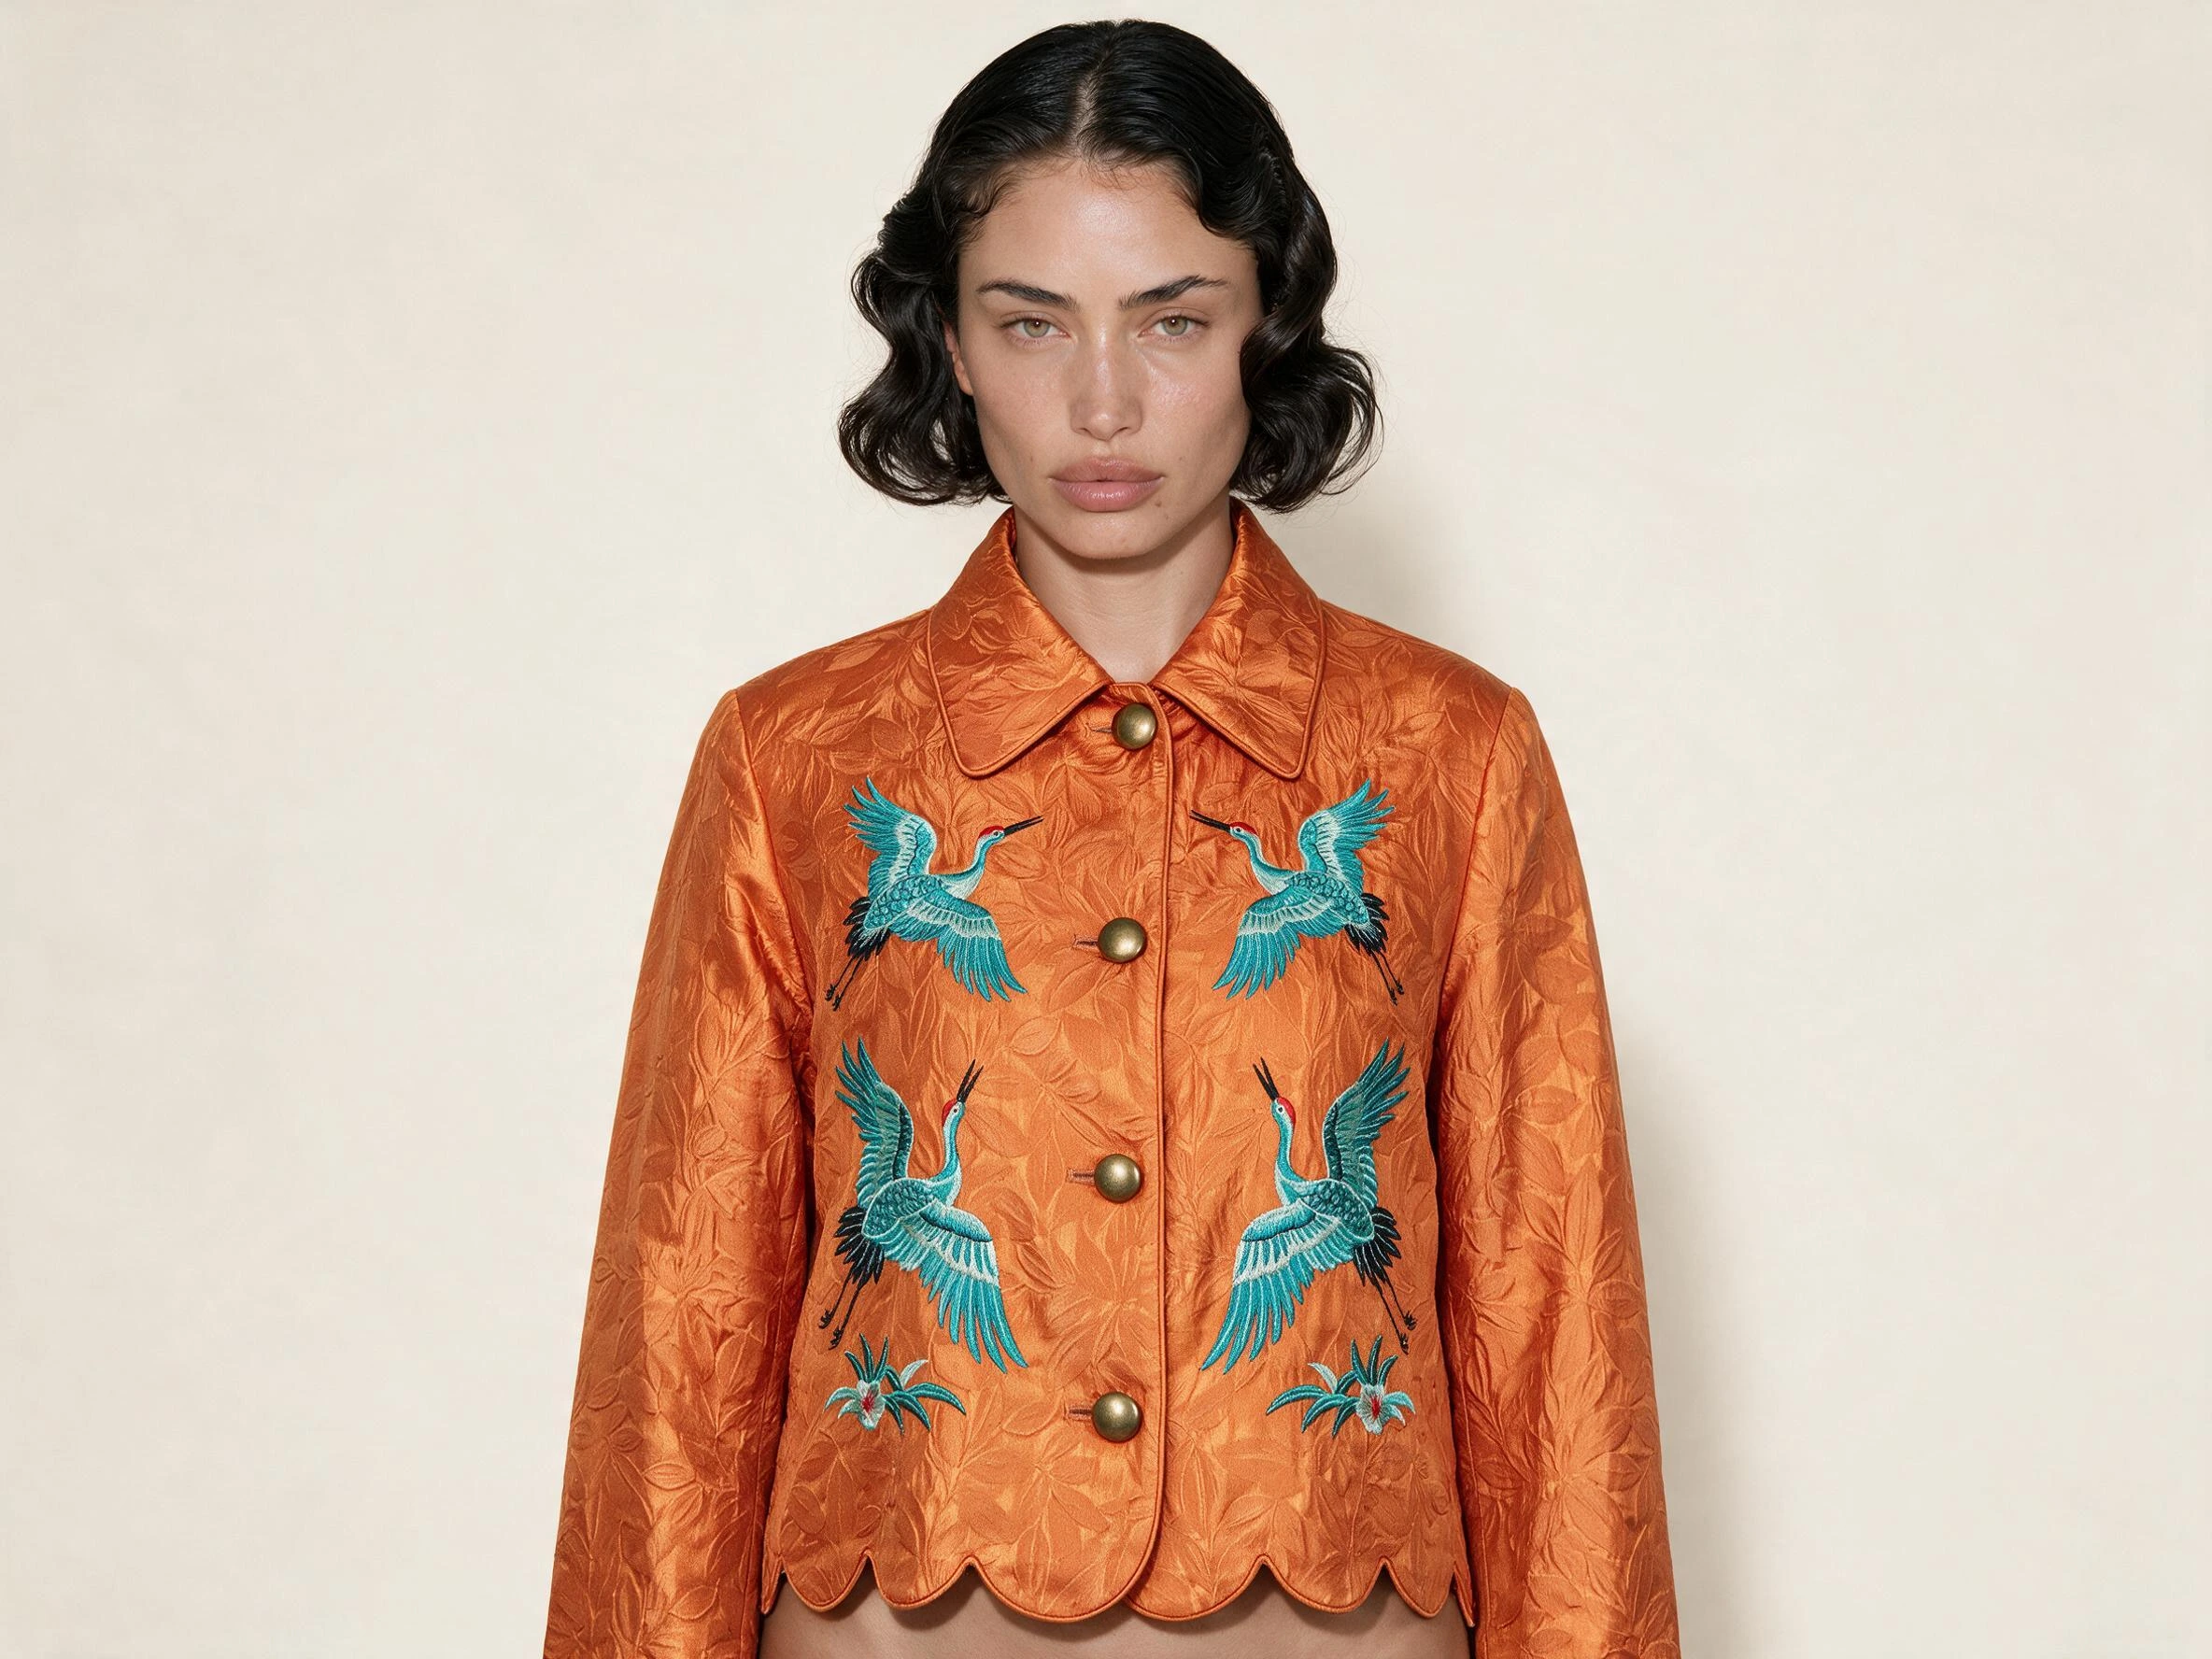
Nano Banana 2.1 and 2.0 follow the upright front-pose direction more clearly. Sunburst and Flare retain more of the supplied portrait's skin texture and head tilt, which helps likeness but weakens strict pose compliance. All five preserve the recognizable bob, eyes and face alongside the main jacket features. These are human visual judgments, not biometric similarity measurements.
Three-quarter view — the same identity and garment
Same cast, jacket, semantic prompt and requested settings. Use the source references above to assess identity and garment detail.
Use this face and the separate jacket reference above to check each output.
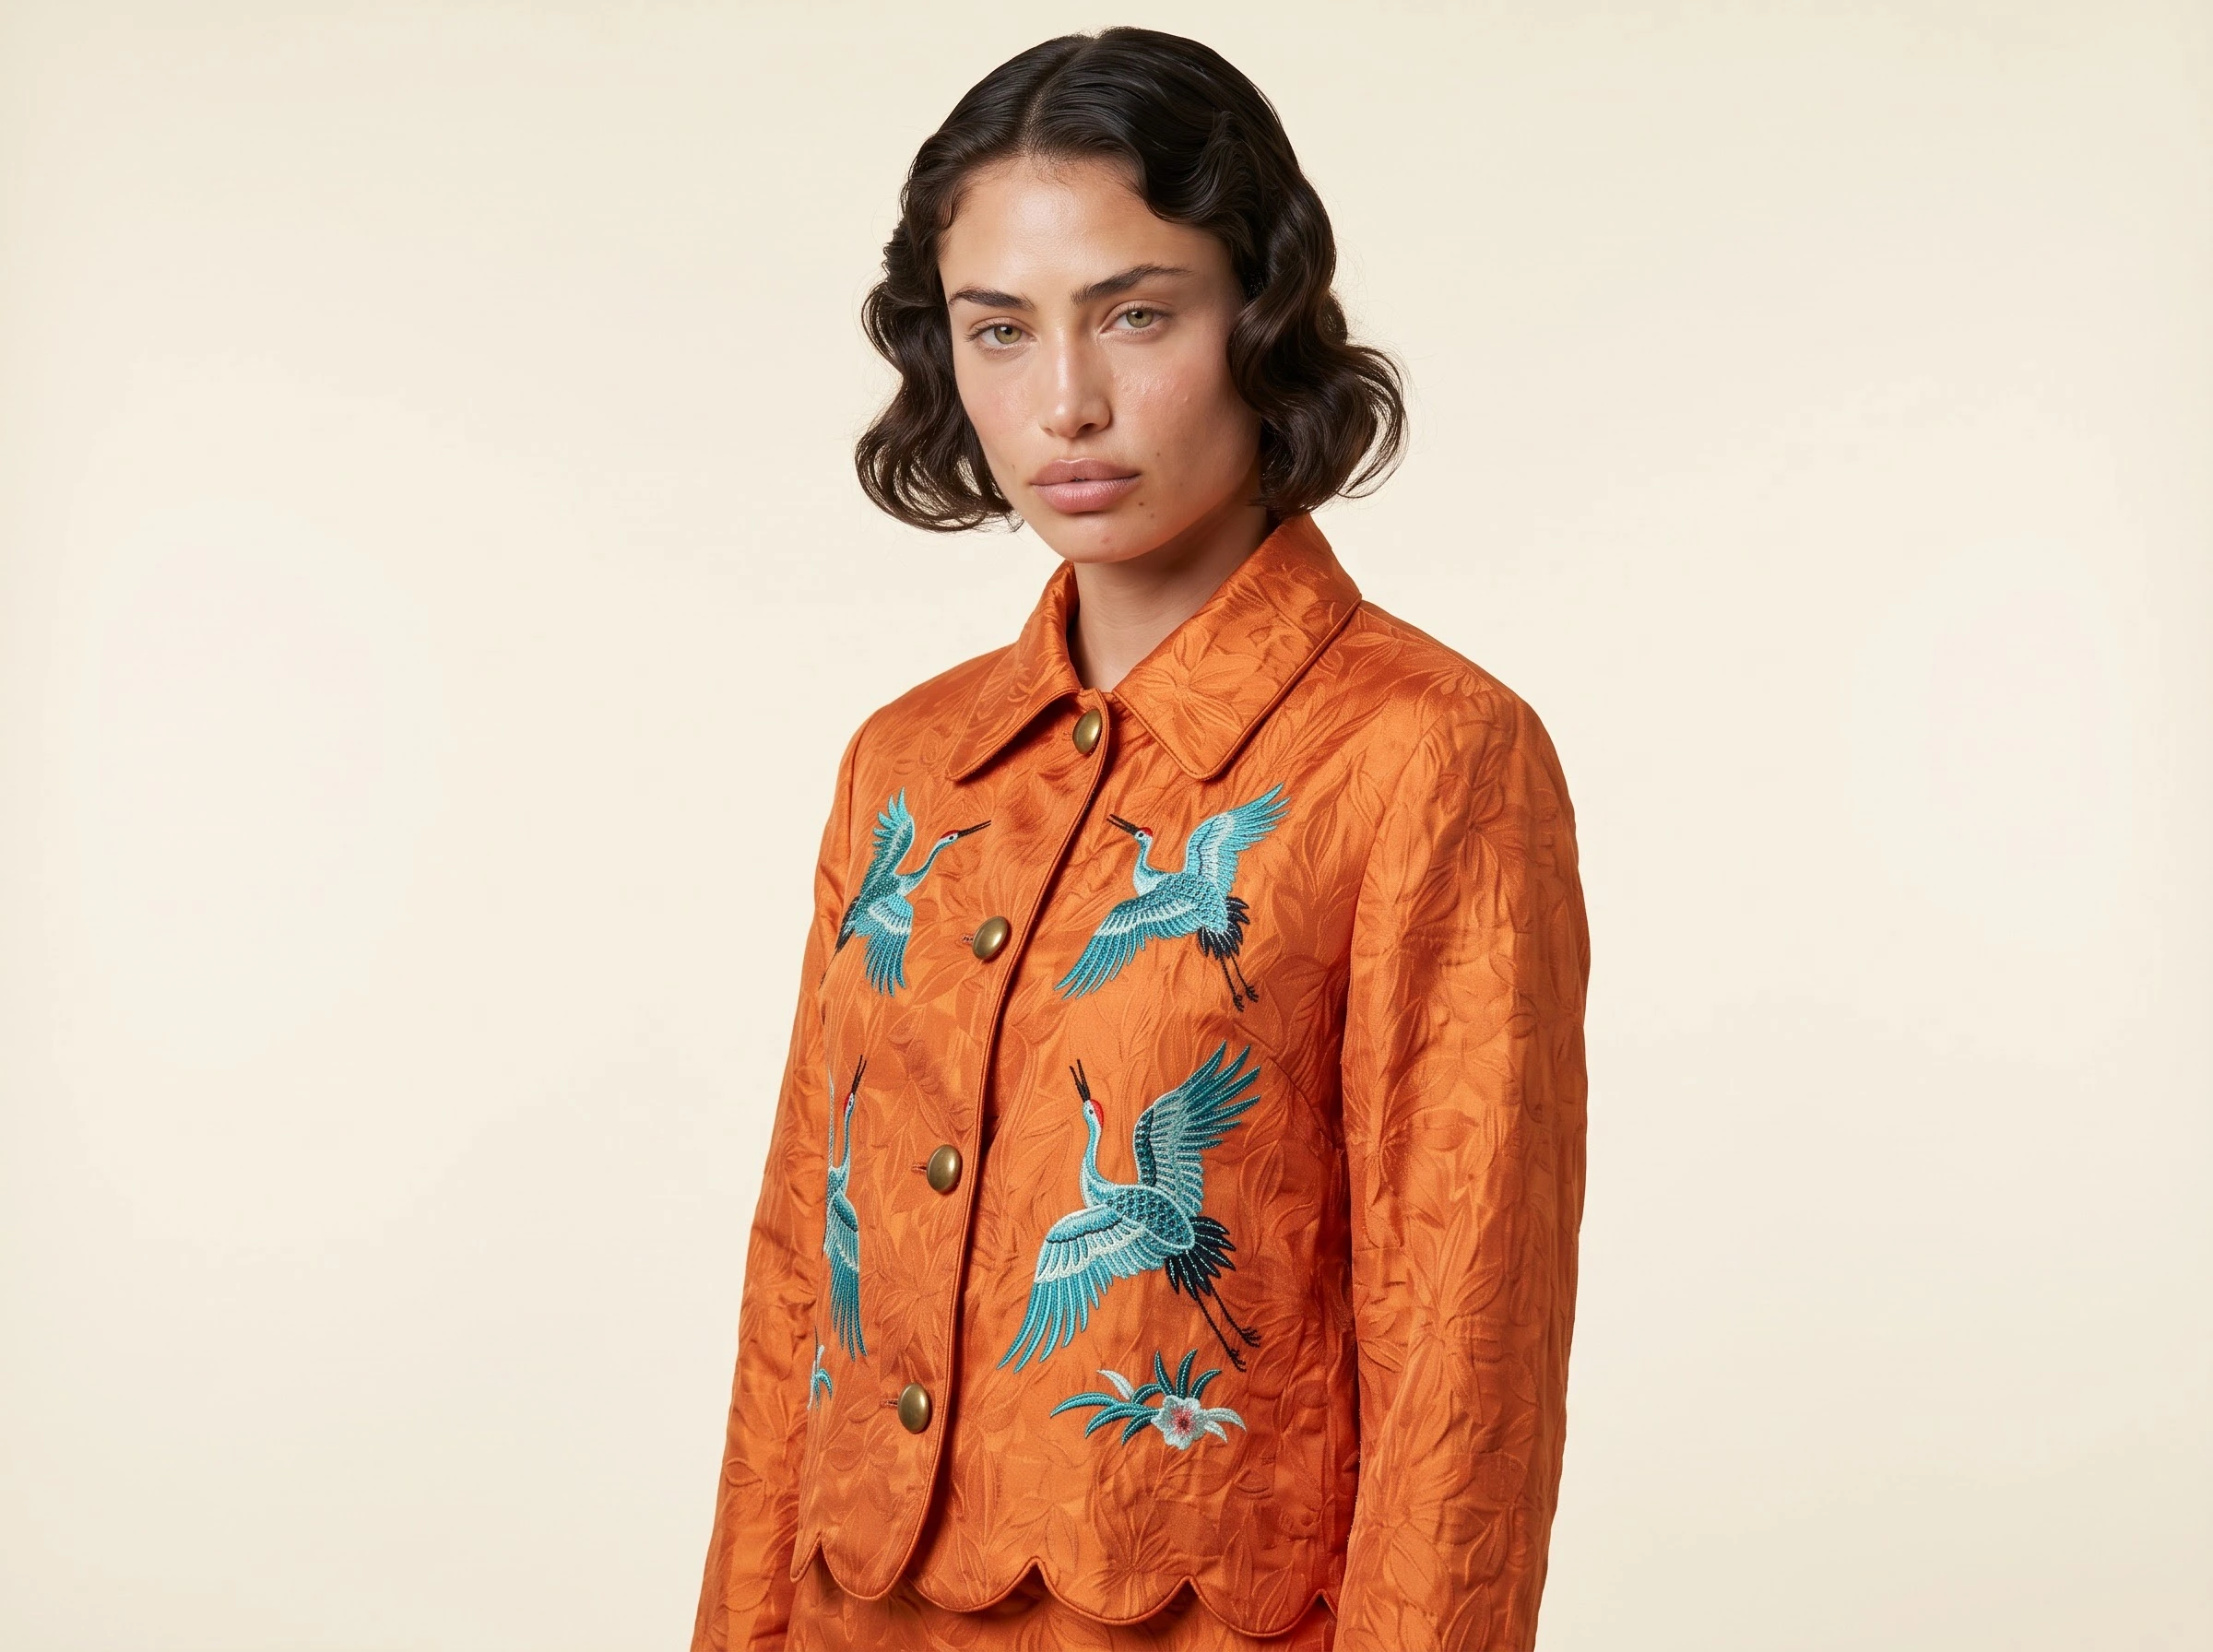
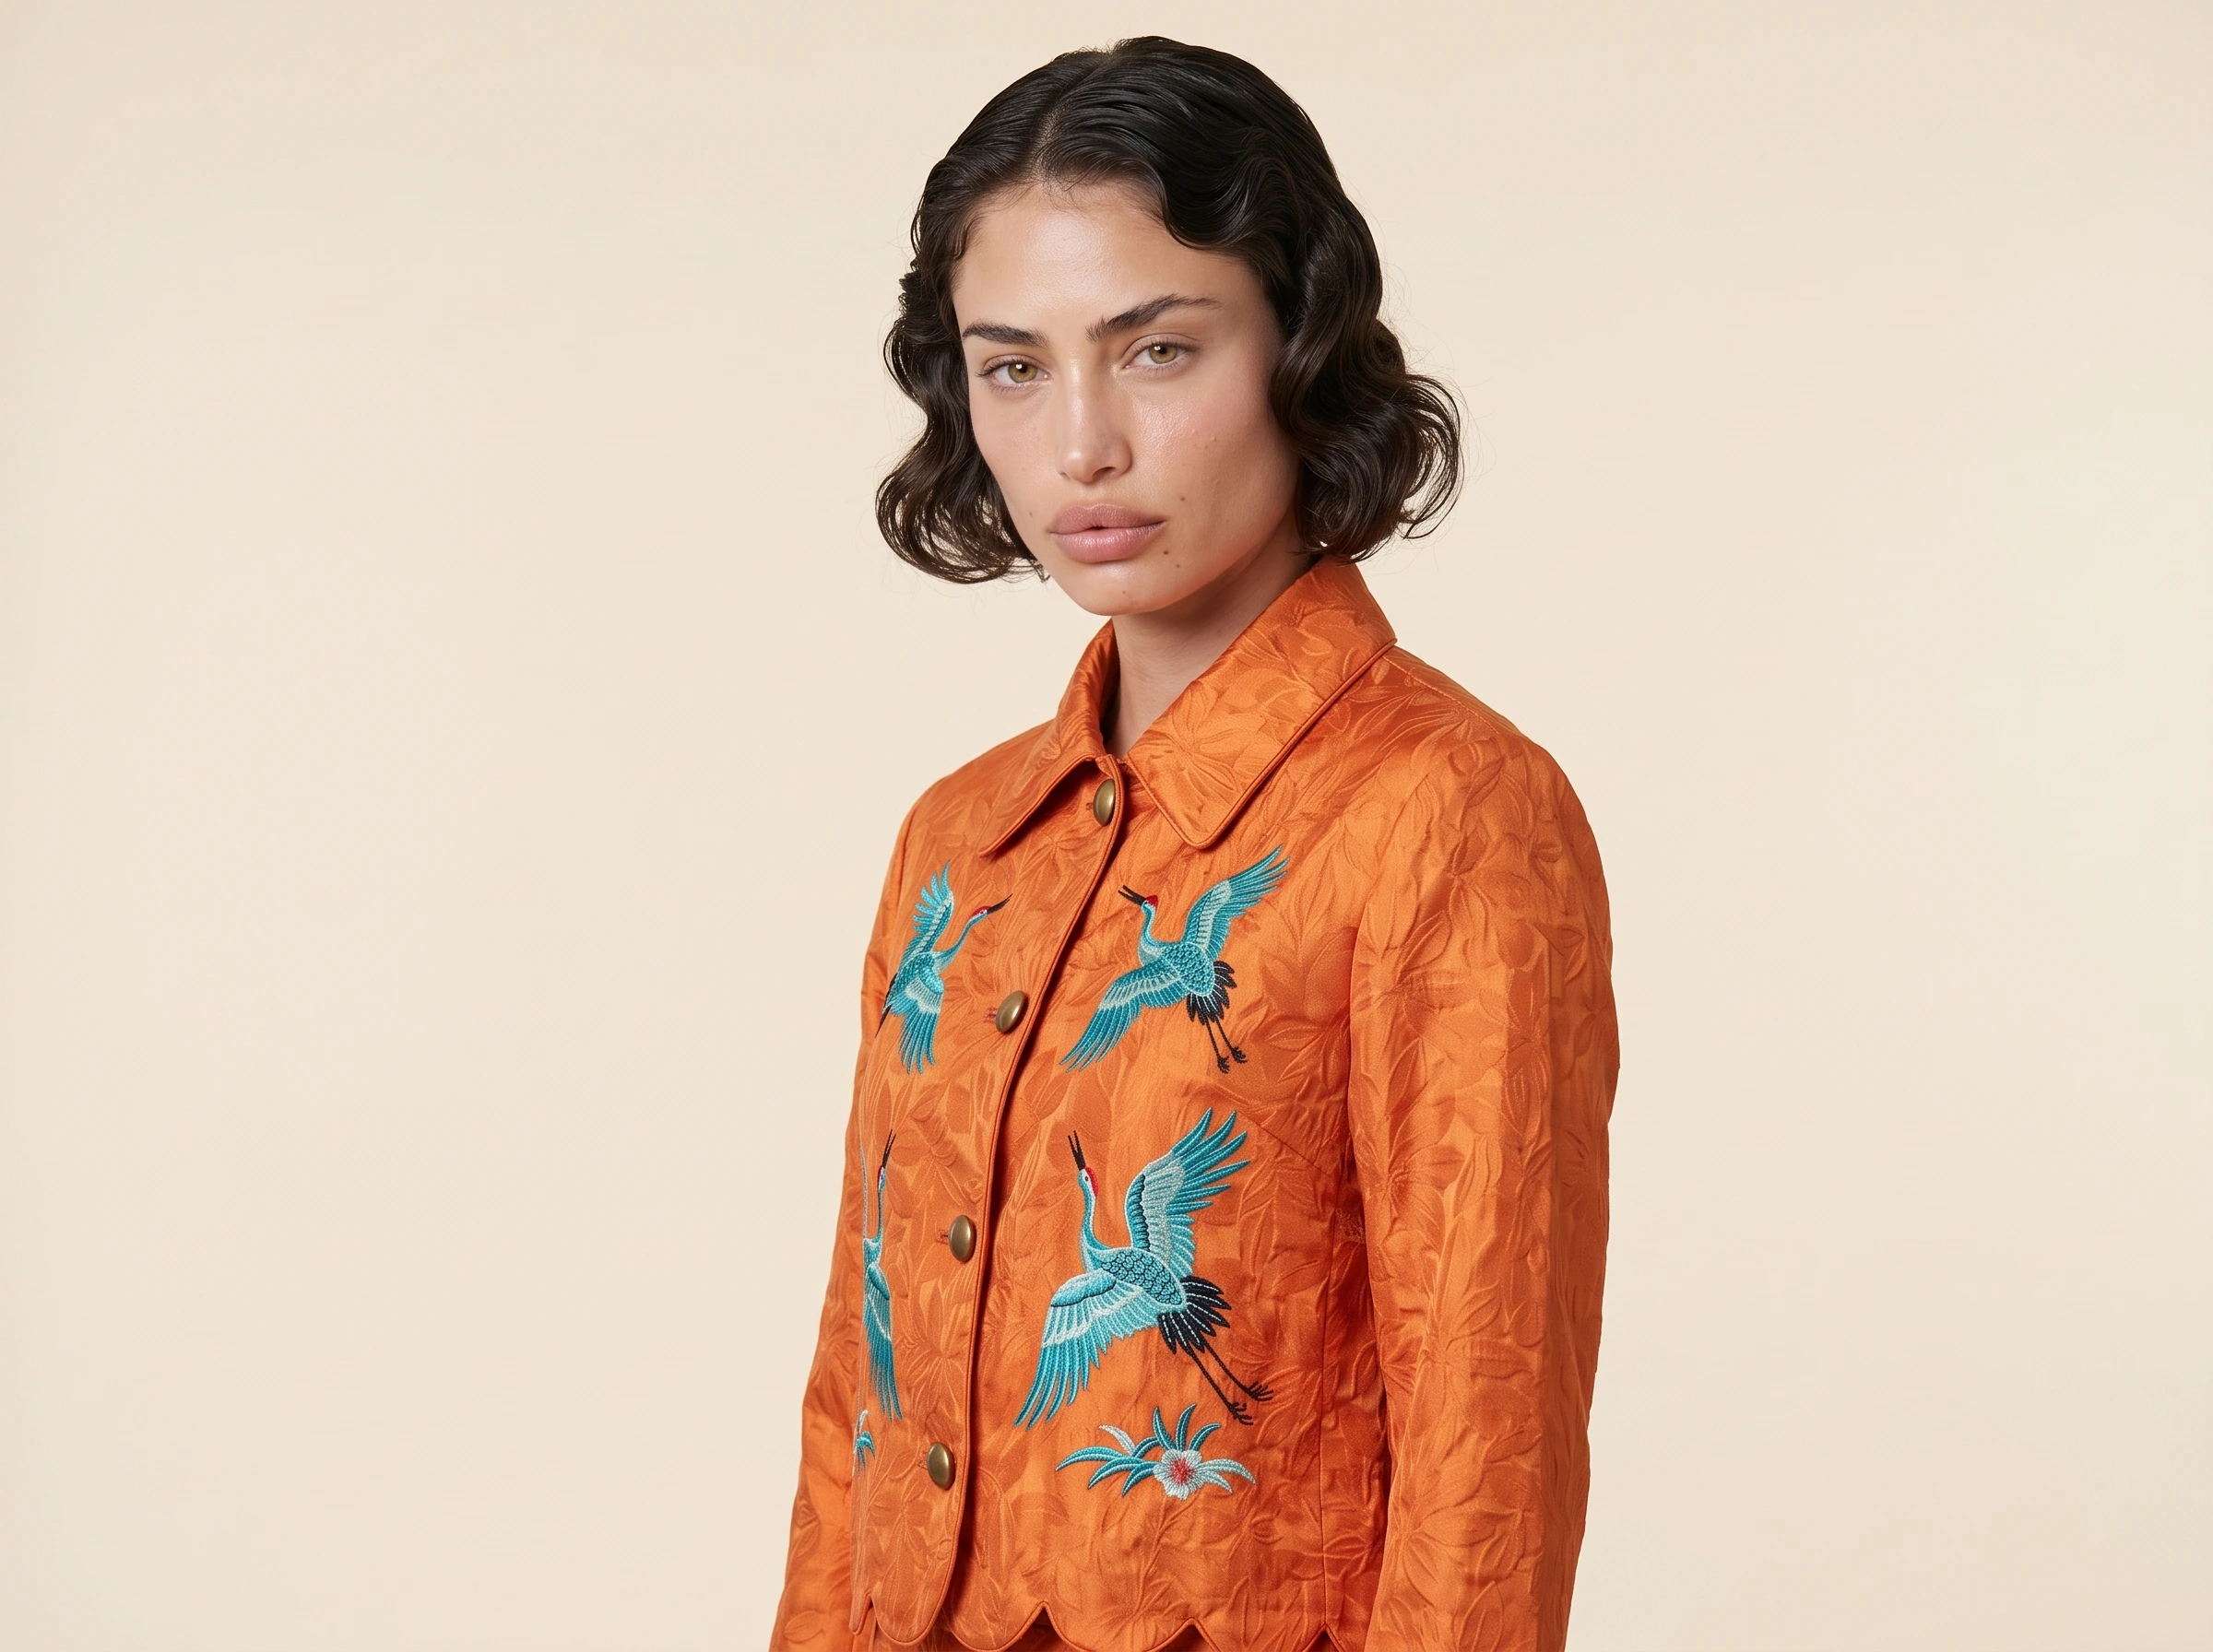
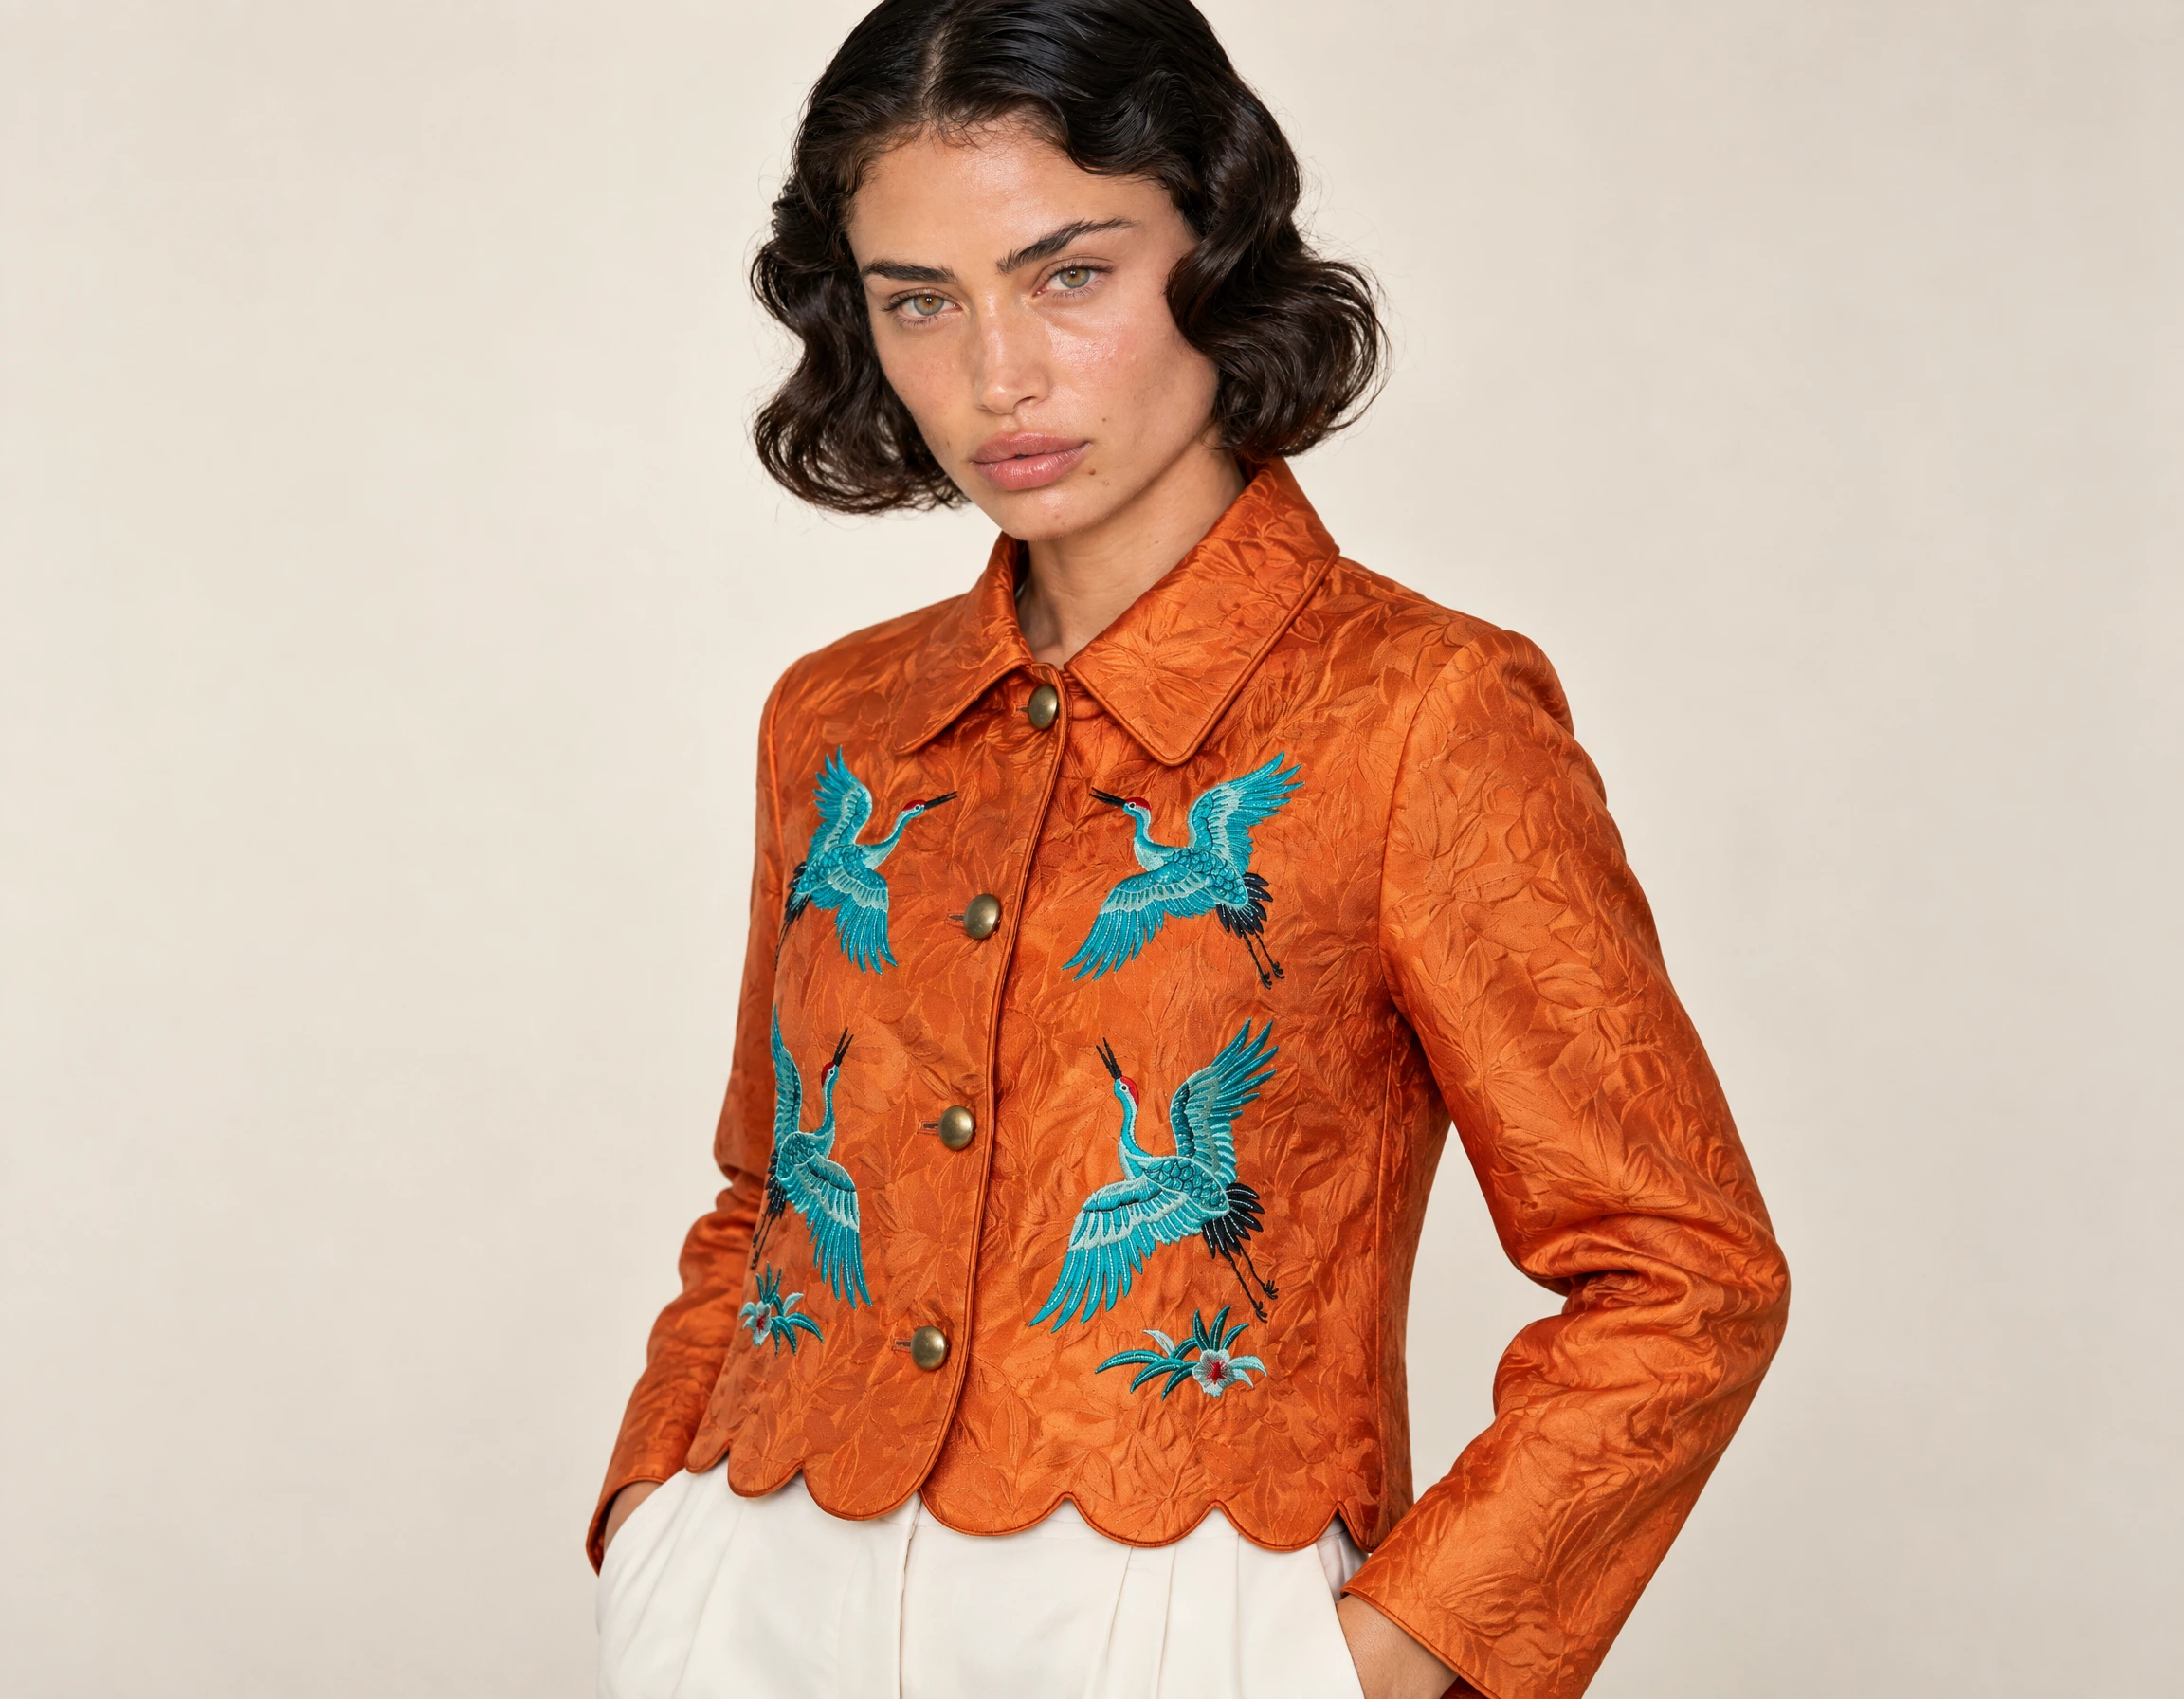
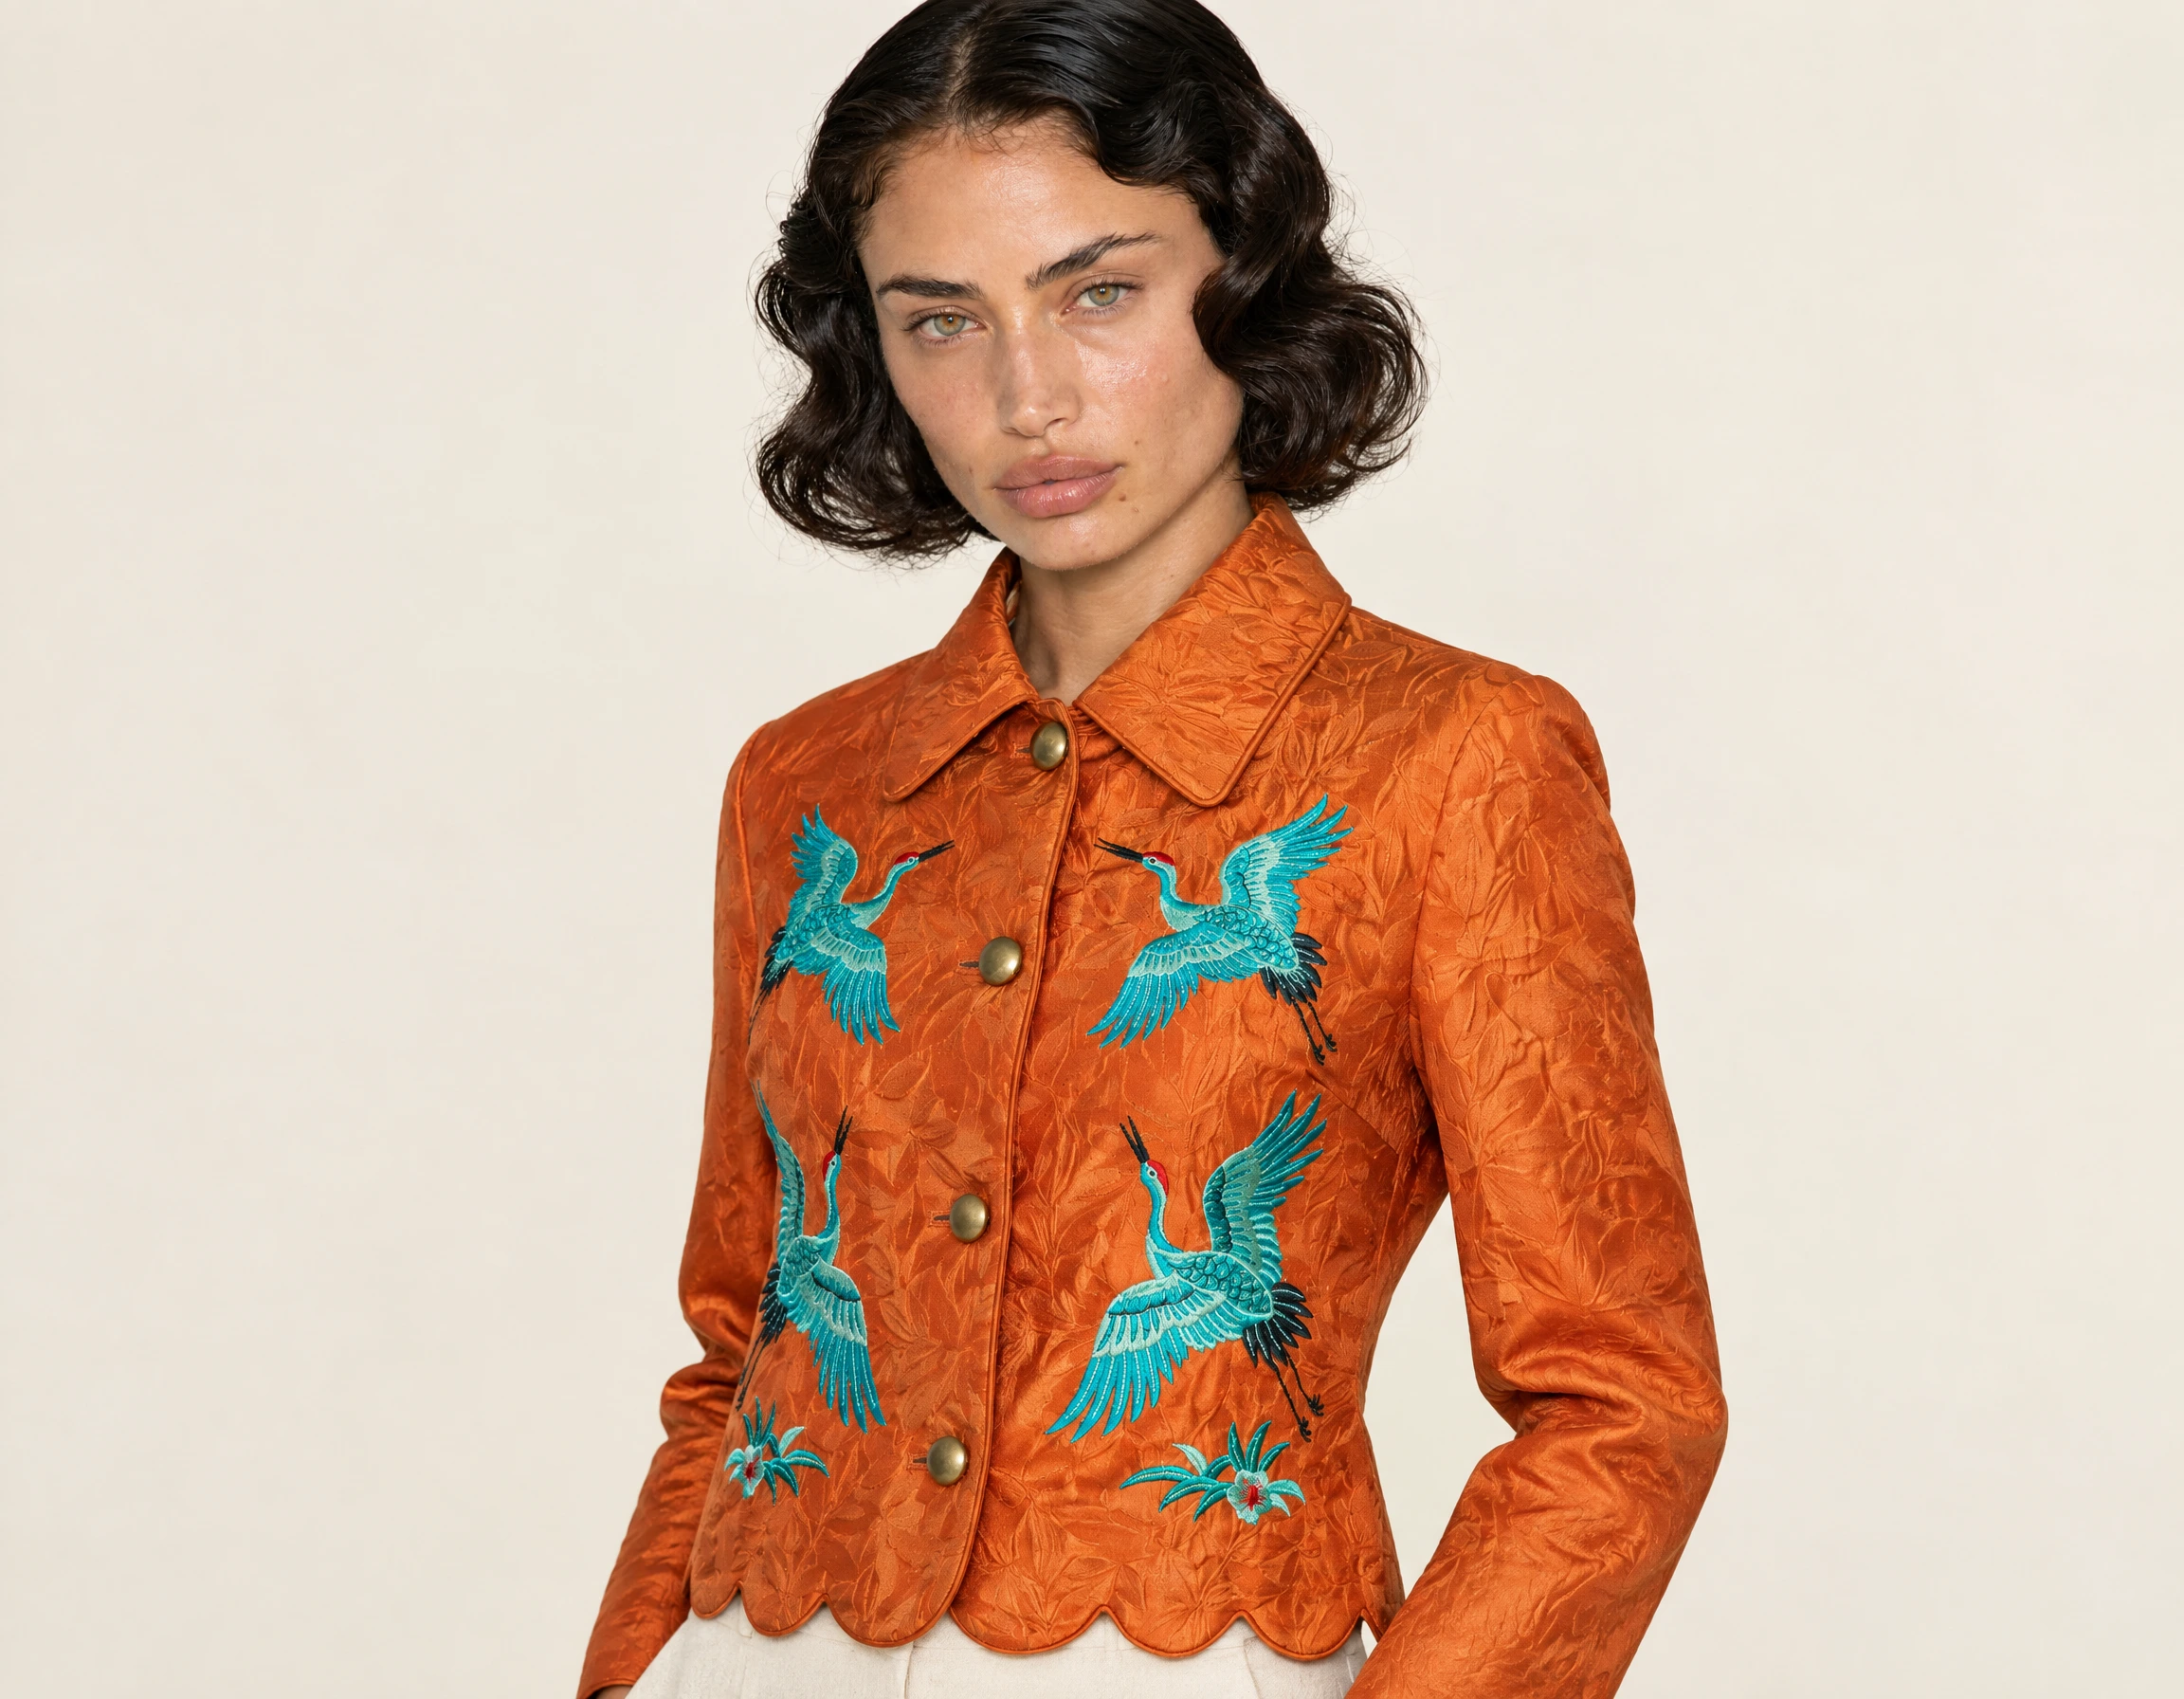
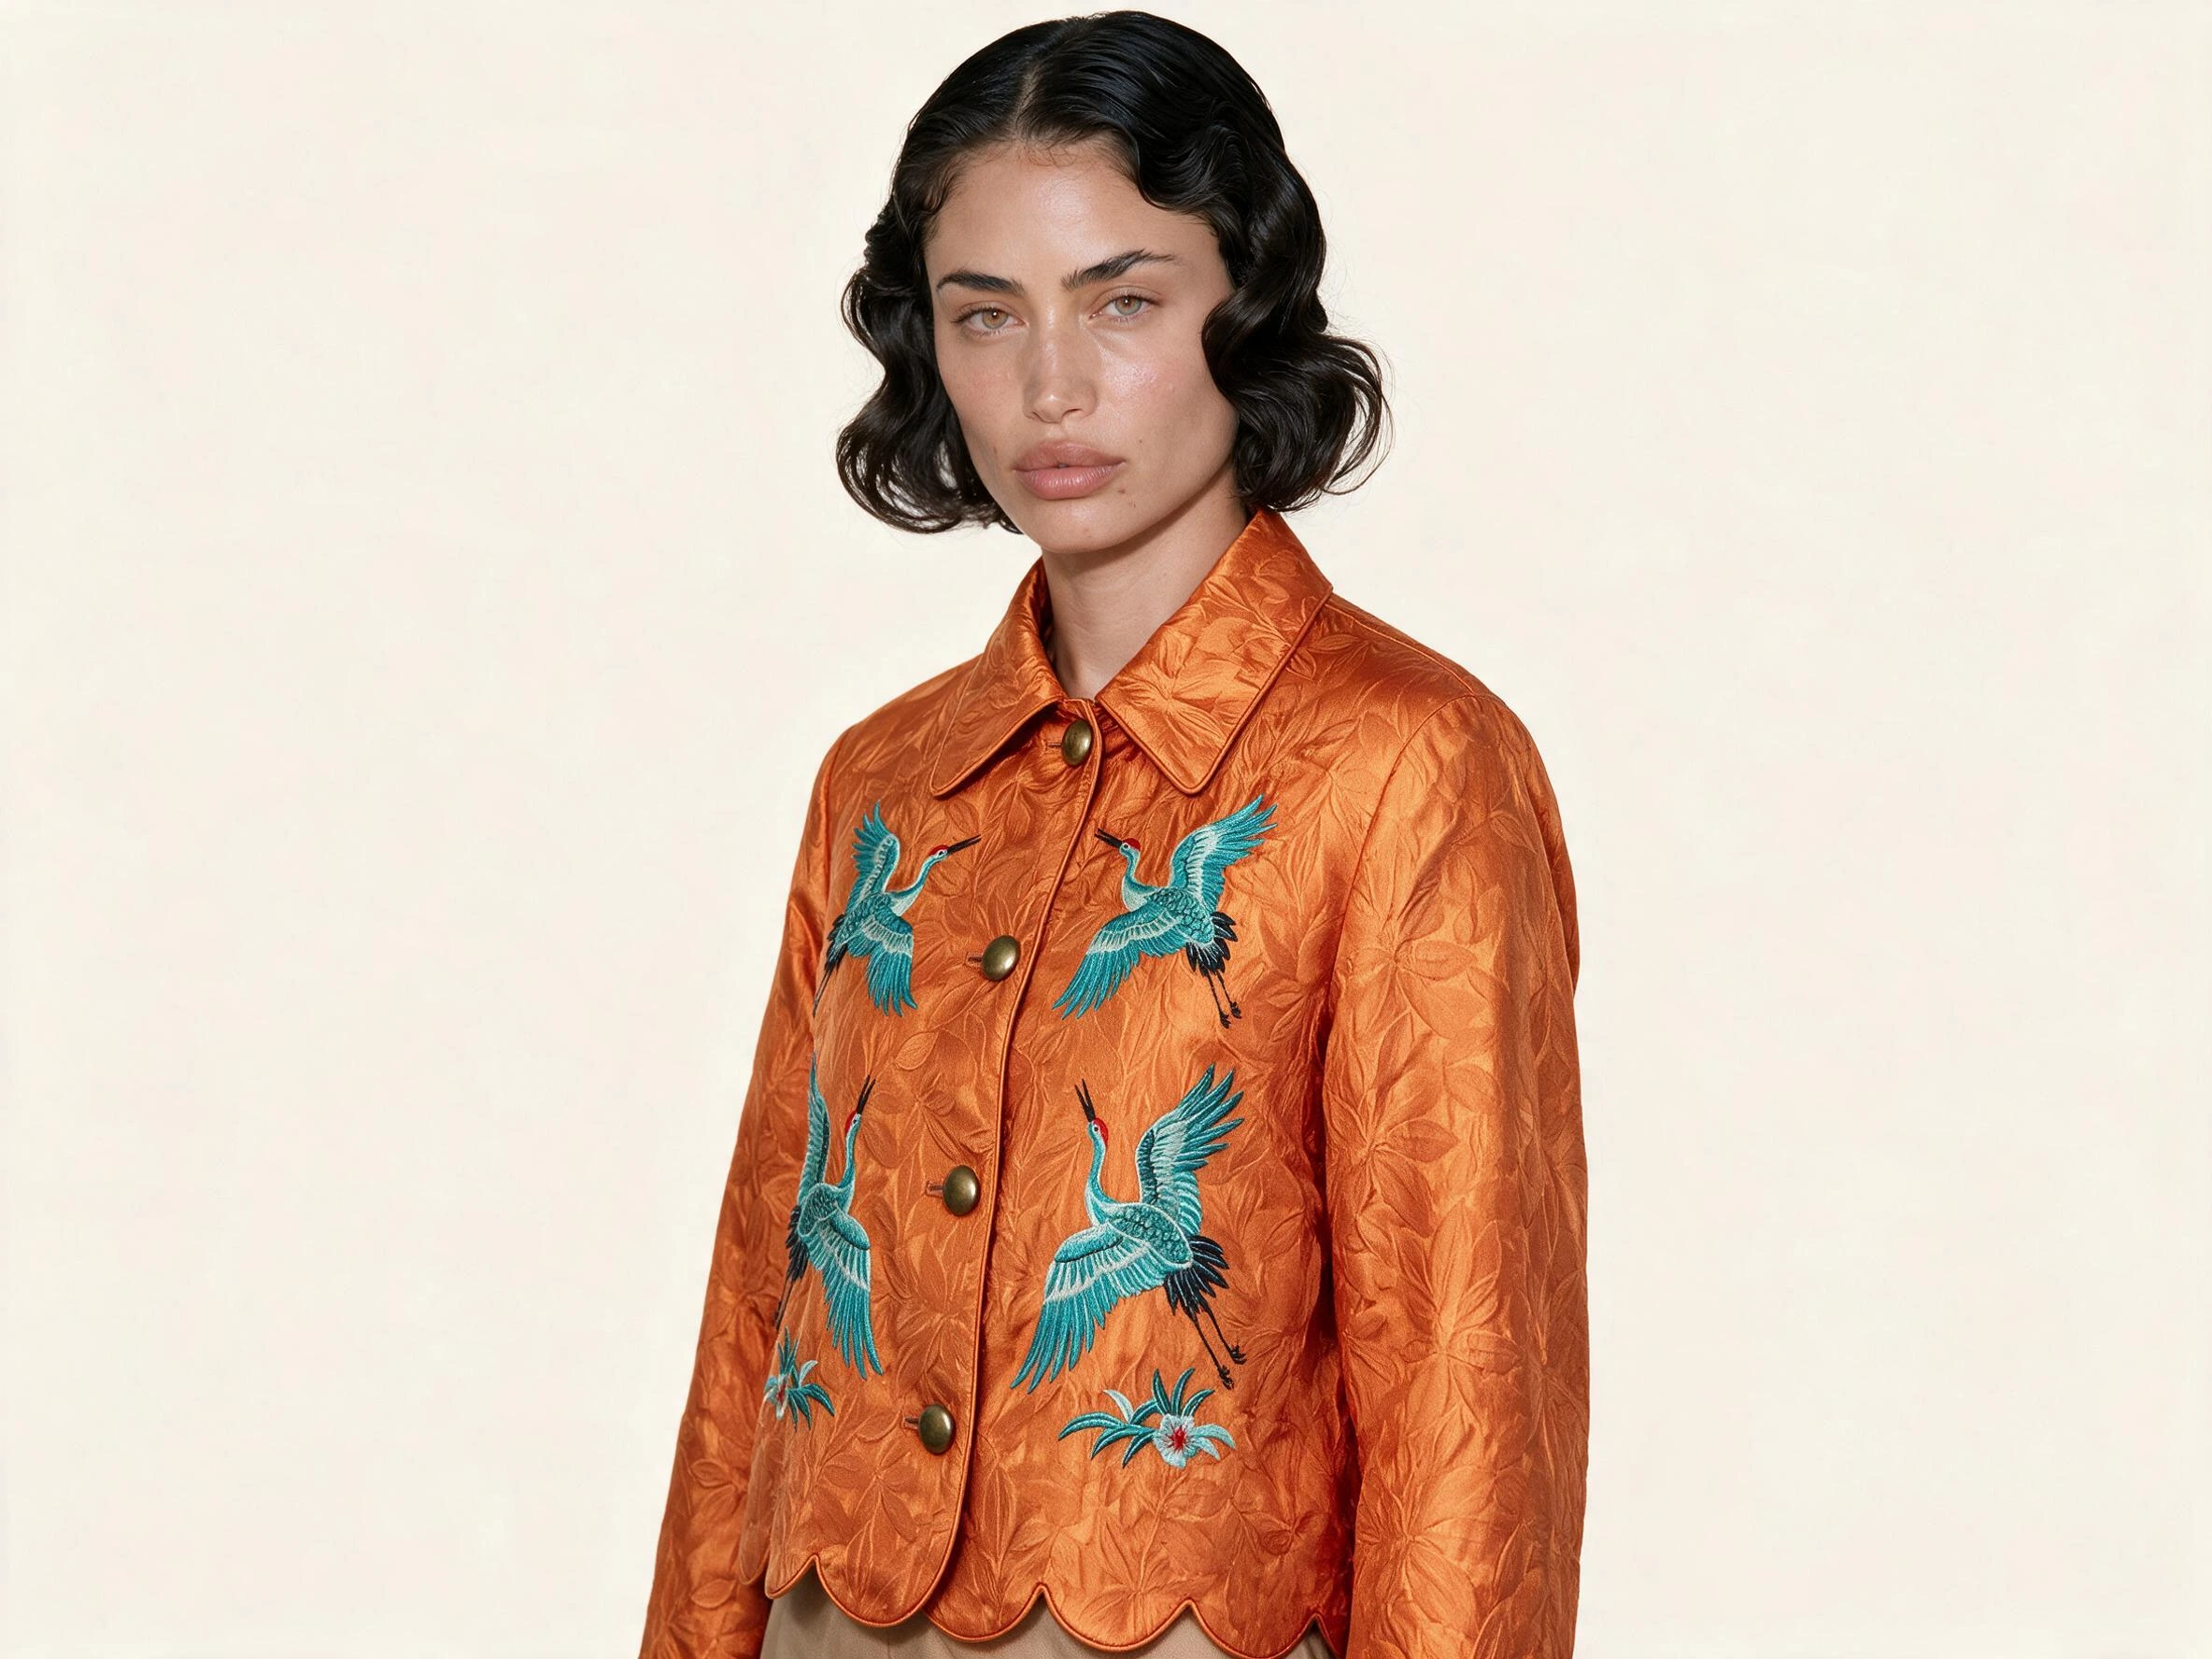
The pair does not reveal a decisive 2.1-over-2.0 identity win. Both Google versions create a coherent cast across these two views, while the supplied facial texture stays closer in the GPT variants. Skin smoothing, tiny marks, weave and crane feathers still change. A campaign can tolerate more variation than a casting approval or a product detail page; decide that tolerance before reviewing outputs.
Three-reference outfit and brand-direction test
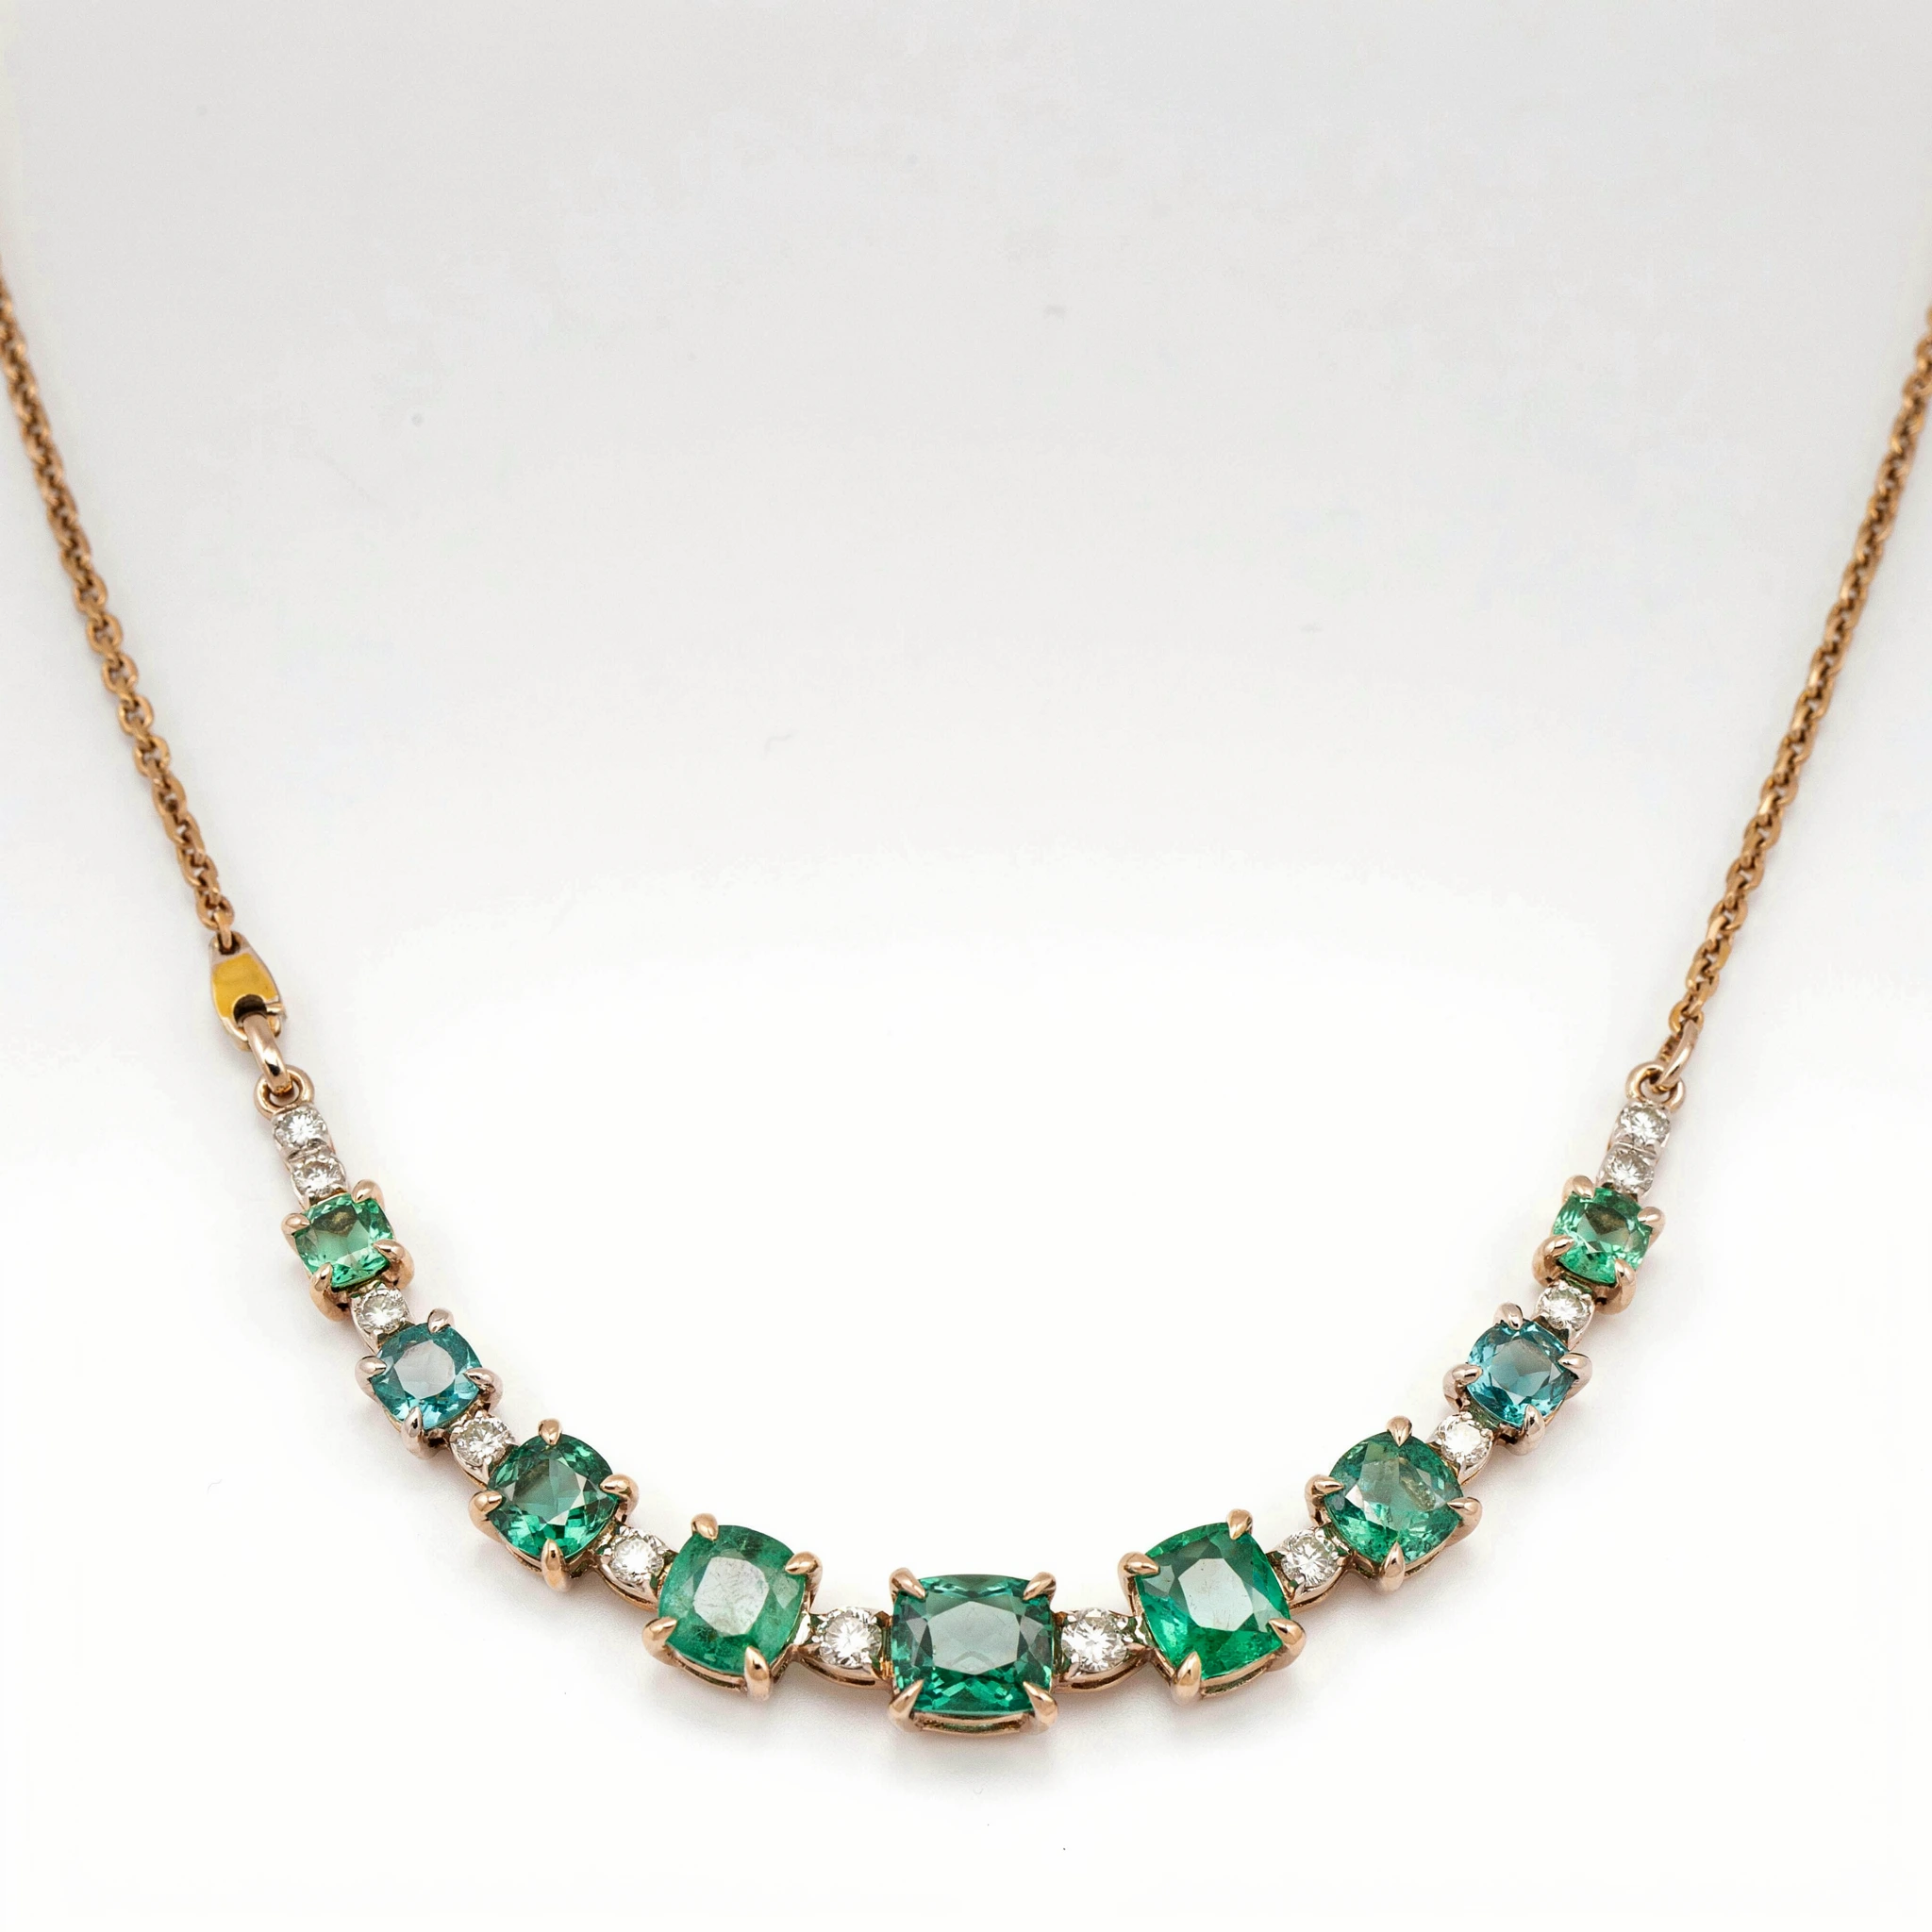
The fifth brief combines the same cast, jacket and nine-stone necklace in a pale limestone gallery, with ivory trousers, warm side light and a relaxed walking pose. The references have explicit roles; the necklace should stay separate from the teal embroidery. We supplied this identical brief to every model:
Create a full-length fashion campaign photograph of <faceid:5851882:1> woman wearing <faceid:5851059:1> jacket with plain ivory trousers and <faceid:5851884:1> necklace, in a pale limestone gallery. Brand direction: restrained ivory, burnt orange and teal, warm late-afternoon side light, relaxed walking pose, premium editorial realism. Preserve cast identity, jacket construction, four teal crane motifs, four brass buttons, leaf weave and scalloped hem. Preserve the necklace's nine green stones, white stone separators, rose-gold settings and cable chain; wear it visibly at the neckline without merging it with embroidery. Plausible anatomy and garment contact, no extra people, no additional jewelry, no invented product, no added text.
All five combine the three reference roles into a coherent fashion scene. None passes every strict campaign constraint. We keep these images internal and report the observations rather than featuring a compromised product example.
| Model | What works | Why this cell needs revision |
|---|---|---|
| Nano Banana 2.1 | Complete walking figure, plausible hands, warm limestone setting, recognizable cast and four cranes | Open neckline leaves only three buttons clearly visible; tiny necklace settings and stone geometry are not verified as exact |
| Nano Banana 2.0 | Complete walking pose and strong warm directional light | Introduces a cream collar that changes the jacket; necklace geometry is reinterpreted |
| Sunburst | Strong likeness, rich cloth detail and convincing warm architecture | Clips the top of the head, opens the neckline and shows three buttons; necklace settings change |
| Flare | Close likeness, four visible buttons and polished garment-and-jewelry separation | Crops below the knees instead of a full-length frame; necklace stone geometry changes |
| Seedream 5 Pro | Recognizable cast, four visible buttons, coherent architecture and lighting | Crops the lower legs; tiny necklace settings cannot be approved as an exact accessory reproduction |
The useful distinction is between assembling the references and preserving every product constraint. The models manage the first more consistently than the second. For a brand campaign, review the neckline, closures, jewelry settings, hands and crop before judging the atmosphere. For a full catalog, qualify additional identities and garments, then inspect repeated edits for drift.
Which model would we start with?
For this cast and garment, Nano Banana 2.1 is a credible starting point for pose-directed, reference-led fashion portraits. It maintains the main garment anchors and produces a coherent identity pair. The product-only label miss and uncertain campaign accessory detail mean we would not approve every output automatically.
Sunburst and Flare deserve the same brief when close source likeness and editorial material detail matter. In these samples they retain more facial texture, while occasionally retaining the source pose too strongly or choosing a crop the brief did not request. Their Arena lead is relevant shortlist evidence, not a substitute for product review.
Nano Banana 2.1, Pro, Sunburst, Flare and Seedream all preserve the 11 measured lines in the clean-packshot-to-real-scene round. Nano Banana 2.0 misses one small-copy line. Seedream 5 Pro remains a useful fabric-and-color alternative at 2K. It keeps the principal jacket features and coherent casting here, but the packaging duplication and campaign crop need correction. Nano Banana 2.0 remains competitive on these small samples; we did not measure a consistent upgrade advantage in identity or three-line ad copy.
These are 31 qualification samples, including six packshot-to-real-scene results, not a statistically reliable model ranking. They use provider defaults rather than matched internal inference budgets: Google's 2.1 default thinking is medium, while its predecessor defaults to minimal. Actual delivered ratios also vary slightly. We did not test long editing chains, wider real-product catalogs, wider cast diversity or a matched latency distribution. Keep aesthetic, identity, product and copy approvals separate.
What the community is saying
Grokbot was unavailable in this session. We used web search and checked the following short quotations against the original posts. Both pages displayed “2h ago” when checked on October 7, 2026; the October 7 posting date is inferred from that relative timestamp. These are community anecdotes, not Astria measurements.
- u/TimeCounty7878, posting in reAPI's official subreddit, wrote: “2.1 kept the exact wording, and the layout is cleaner.” Their comparison used one run per prompt and different models' default thinking settings. The vendor-affiliated venue and small sample matter when assessing the claim. Original post, checked October 7.
- u/mementomori2344323, describing a recursive FLUX 3 versus 2.1 edit test, qualified its metric as measuring “only preservation of untouched regions.” The test used different model-specific interfaces and three source images. It raises a useful concern about drift through repeated edits, but does not measure overall commercial-image quality. Original post, checked October 7.
Those reports suggest useful qualification tests: exact-copy layouts, repeated local edits, and settings-aware latency checks. They do not replace our controlled reference comparison.
Standard versus Flex, resolution, and budgeting
Standard is available; Nano Banana 2.1 does not support Flex. Google's Cloud pricing page explicitly says so in the Nano Banana 2.1 footnote, even though a combined table heading mentions Flex/Batch/Off-peak. Batch support is separate and should not be mistaken for Flex availability. See Google Cloud pricing and Gemini API pricing, checked October 7, 2026.
For an interactive creative review, plan around Standard and measure the complete round trip. For an asynchronous approved catalog batch, check whether your chosen interface exposes Google's supported Batch path. The Astria generation tool used here does not expose a service-tier selector; we make no claim that these runs used Batch or Flex. Priority availability differs across Google's documented surfaces, so confirm the specific API before designing a deadline-critical workflow around it.
Budget with current rates for input, reasoning or text output, image output at the chosen resolution, and any search grounding. Divide total generation and review effort by the number of approved assets. A lower output component does not guarantee a cheaper completed campaign when references, reruns, and manual correction change. Get current Astria rates from Astria pricing.
For reproducibility, archive the source images and provider model ID, not just the interface's model name. Use approved reference packs for production, and requalify them after a provider upgrade. Our benchmark methodology explains how we separate material fidelity, identity, copy, and aesthetic judgments.